July 20, 2023
|
5 minutos de lectura


Obtenga acceso instantáneo a un entorno TrueFoundry en vivo. Implemente modelos, dirija el tráfico de LLM y explore la plataforma completa: su sandbox estará listo en segundos, sin necesidad de tarjeta de crédito.



Published: August 26, 202616
¡Una forma increíblemente rápida de crear, rastrear e implementar sus modelos!
Gemini 3 Pro is the flagship tier of Google's Gemini 3 model family, positioned for demanding reasoning, coding, long-context, and multimodal work. As the "Pro" tier, it targets higher-quality output than the lighter, faster tiers in the same family, at a higher cost per token.
For teams, the practical questions are the ones the benchmarks and the launch material should answer, and which you should confirm against the official source before relying on them:
Benchmarks sell a launch, but only a few translate into whether a model is right for your workload. Weigh these against the tasks you actually run rather than the headline leaderboard.
The most useful benchmark is always your own. Because a gateway lets you route a slice of live traffic to Gemini 3 Pro next to your current model, you can compare them on your prompts and your latency budget, which is worth more than any public score. That kind of side-by-side is a core part of AI agent portability.
Rather than wiring Gemini 3 Pro directly into every application, you add it once to the AI Gateway and every app and agent can call it through one OpenAI-compatible API. TrueFoundry supports Google Gemini as a provider, so you connect your Gemini account, select the models, and manage access centrally.
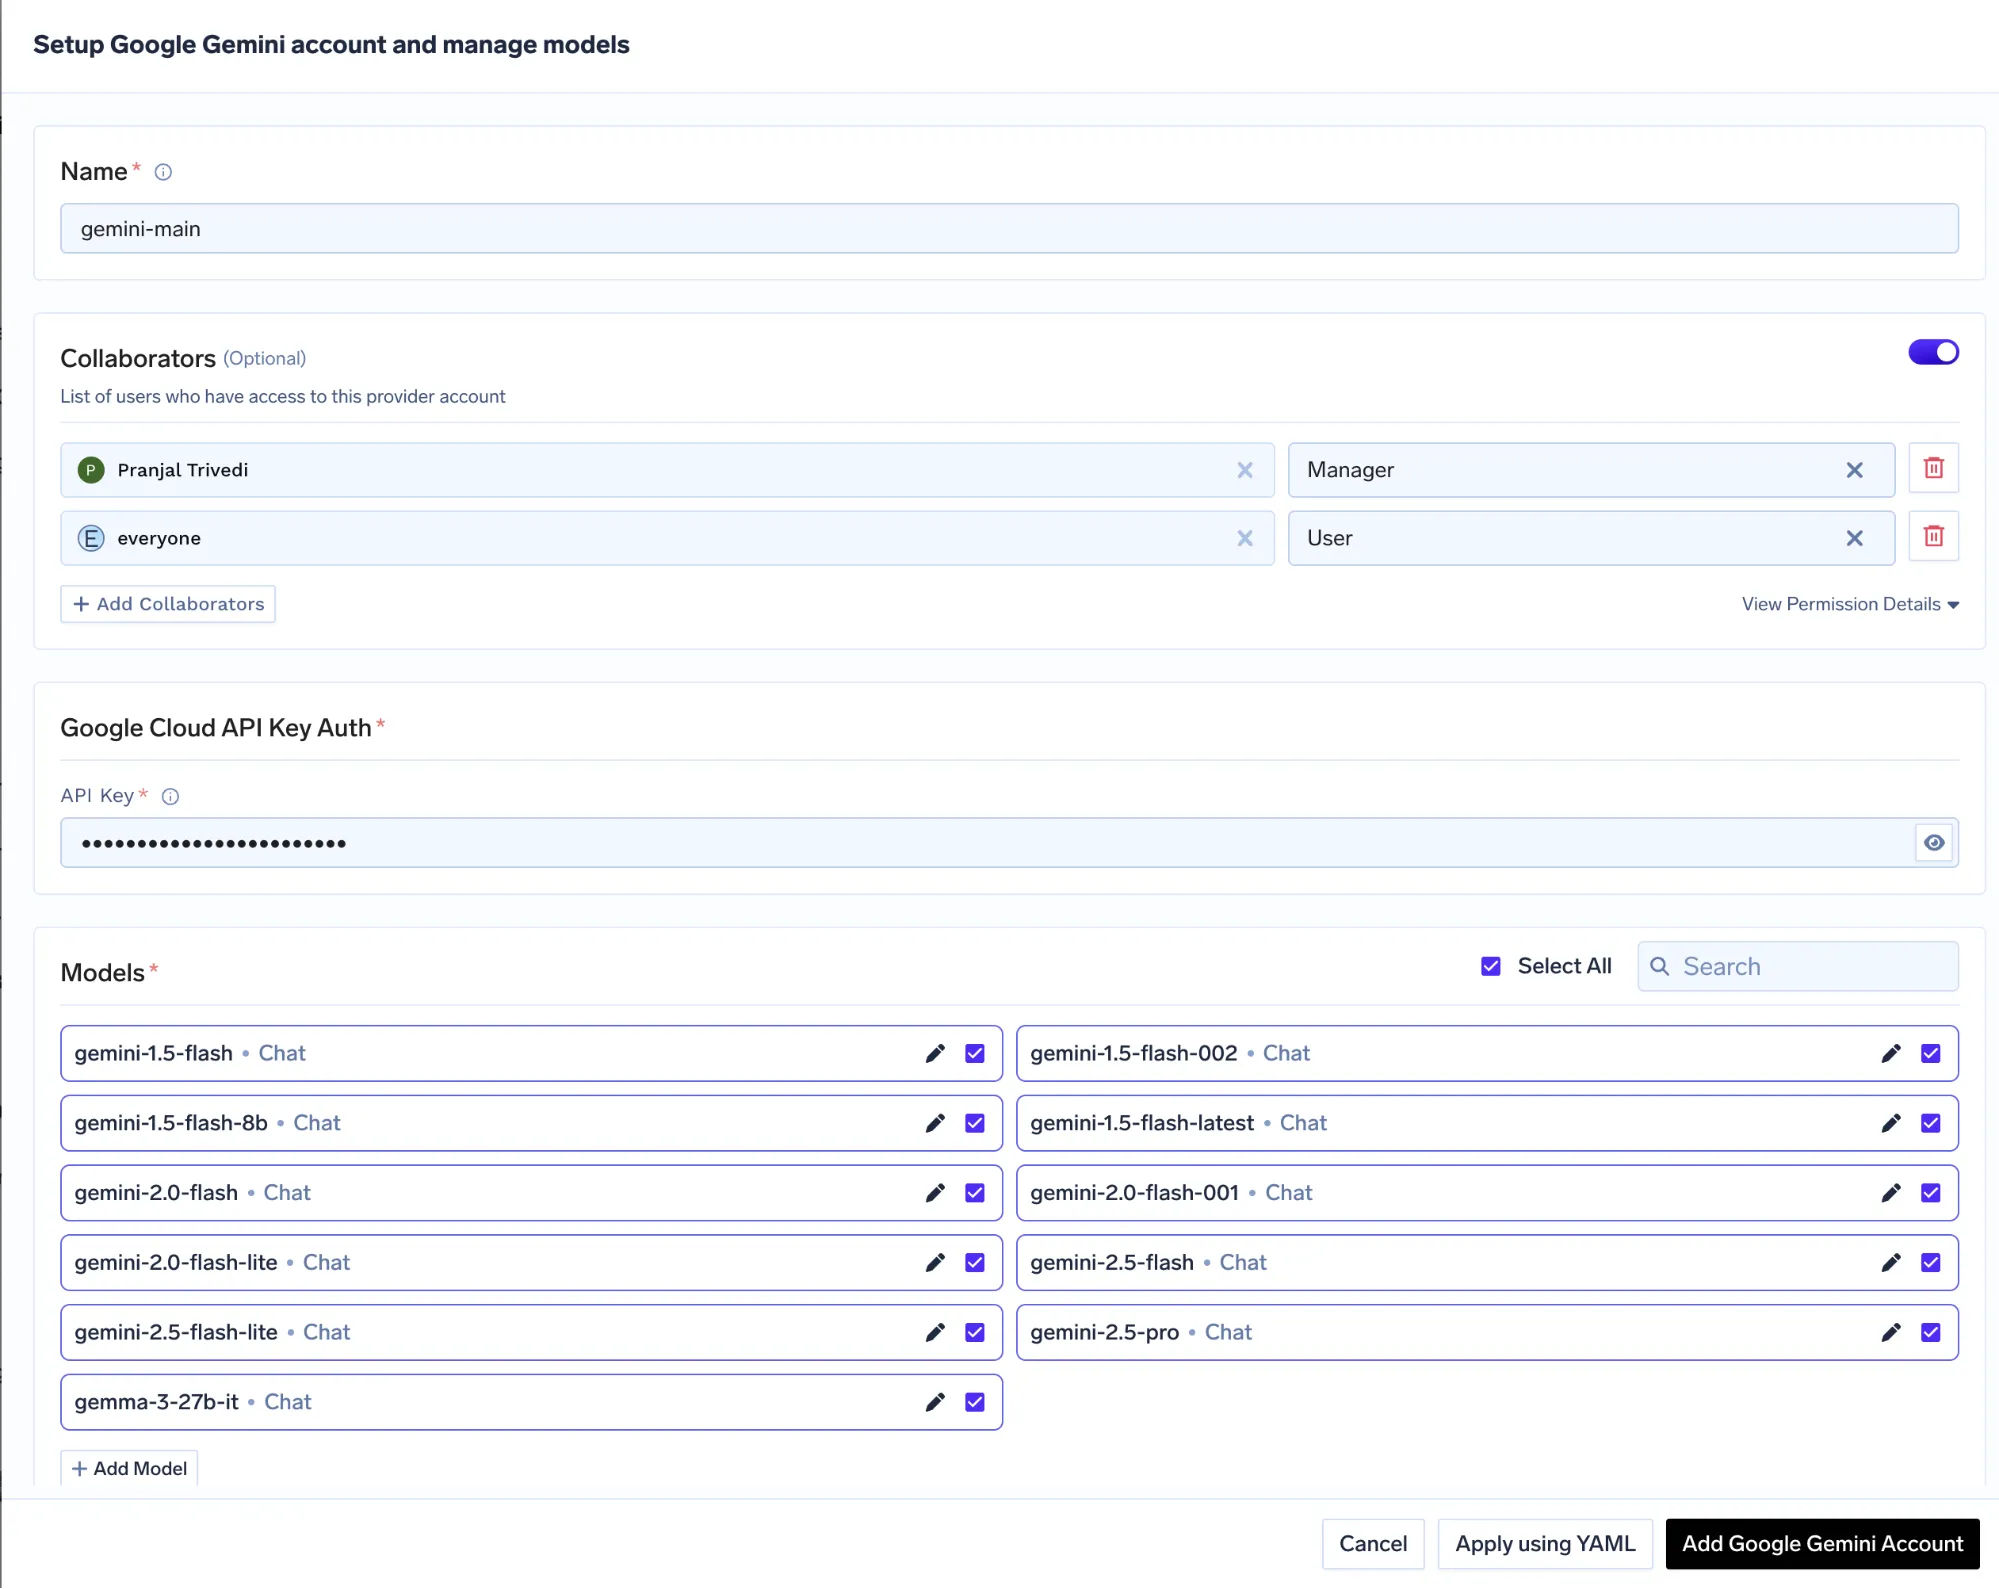
You navigate to AI Gateway, then Models, then Google Gemini, add your account and authentication, add collaborators for access control, and select the Gemini models to expose. From then on, calling Gemini 3 Pro looks like calling any other model, and switching to it is a one-line change:
from openai import OpenAI

client = OpenAI(
    api_key="your-truefoundry-api-key",   # a gateway token
    base_url="https://gateway.truefoundry.ai",
)

resp = client.chat.completions.create(
    model="google-gemini/gemini-3-pro",
    messages=[{"role": "user", "content": "Explain this architecture diagram"}],
)
Routing coding assistants and CLIs to it works the same way. If your team uses the Gemini CLI, you can point it at the gateway so those requests are governed alongside everything else, rather than going straight to the provider.
What you gain by going through the gateway instead of the raw provider API:
The gateway adds only a few milliseconds of overhead while doing this, across 1,000+ models behind the one API, so adopting a new frontier model does not mean adopting a new integration each time.
Gemini 3 Pro is worth testing on real work, and the way to do that without regret is to treat it as one more model behind a unified gateway rather than a fresh integration. Add it once, benchmark it on your own traffic, govern its cost and access, and keep a fallback ready, and adopting or dropping it later stays a configuration change. It leads major reasoning, coding, and multimodal benchmarks, so it is well worth testing on your own workloads.
See how TrueFoundry lets you access Gemini 3 Pro and 1,000+ models from one control plane. Book a demo or start free.
TrueFoundry AI Gateway ofrece una latencia de entre 3 y 4 ms, gestiona más de 350 RPS en una vCPU, se escala horizontalmente con facilidad y está listo para la producción, mientras que LitellM presenta una latencia alta, tiene dificultades para superar un RPS moderado, carece de escalado integrado y es ideal para cargas de trabajo ligeras o de prototipos.




Gemini 3 Pro es el nivel insignia de la familia de modelos Gemini 3 de Google, creado para tareas exigentes de razonamiento, programación, contexto largo y multimodales. Busca una calidad de salida superior a la de los niveles más ligeros de la familia, con un coste por token más alto. Confirme sus especificaciones exactas en el material oficial de lanzamiento.
Puede invocarlo directamente a través del proveedor o mediante un AI Gateway que lo expone con una API unificada compatible con OpenAI. Al pasar por el gateway, usted añade el modelo una sola vez y todas las aplicaciones y agentes pueden invocarlo con control de acceso centralizado, seguimiento de costes y fallback, y cambiar de modelo supone modificar una sola línea.
Gemini 3 Pro es un modelo de pago de gama insignia, y el precio lo fija el proveedor. Consulte las tarifas por token vigentes antes de comprometerse y use los controles de coste del gateway para limitar y atribuir el gasto. Google ha lanzado desde entonces Gemini 3.1 Pro, así que confirme la tarifa por token actual.
Sí, está disponible a través de la API de Google, y también puede acceder a él mediante el AI Gateway de TrueFoundry como google-gemini/gemini-3-pro, lo que le ofrece una única interfaz compatible con OpenAI para Gemini 3 Pro y más de 1.000 modelos adicionales.
A más de 1.000 LLM mediante una única API compatible con OpenAI, que abarca Google Gemini, OpenAI, Anthropic y modelos autoalojados, de modo que usted cambia de modelo con solo cambiar su nombre.
Sí. TrueFoundry se ejecuta en su VPC, on-prem, en entornos air-gapped o híbridos, de modo que el tráfico hacia Gemini 3 Pro y todos los demás modelos permanece gobernado dentro de su propio dominio.



Las últimas noticias, artículos y recursos enviados a tu bandeja de entrada