August 26, 2026
|
5 min de lecture


Accédez instantanément à un environnement TrueFoundry en direct. Déployez des modèles, acheminez le trafic LLM et explorez la plateforme complète : votre sandbox est prête en quelques secondes, aucune carte de crédit n'est requise.


Published: October 6, 2026
Une méthode incroyablement rapide pour créer, suivre et déployer vos modèles !
When OpenAI shipped GPT-5.6 on July 9 as three tiers (Sol, Terra, and Luna), most of the attention went to the tier ladder itself. The quieter change is more interesting: cache writes are now billed for the first time, at 1.25x the normal input rate, while cache reads keep their existing 90% discount. Caching used to be close to free upside. Now it has a cost, which means it also has a point where it stops being worth it.
So where's that point? We built a small cost model to find out, across all three tiers.
For a typical agent workload, you've got a large shared context (system prompt, toolschemas, repo context) reused across many calls, plus a small unique part per request. The break-even comes down to three numbers: the full input price, the cache-write price, and the cache-read price. Solve for the write/read mix where caching costs the same as not caching at all, and you get a single ratio.
Here's the part we didn't expect: that ratio is identical across Sol, Terra, and Luna. Writes can be up to 78.3% of requests before caching stops paying off, and that number doesn't move with context size, request volume, or which tier you're on. OpenAI applied the same 1.25x/0.10x multipliers uniformly across the family, so tier choice changes your absolute costs, not your caching strategy.
Context size doesn't move the break-even point, but it does change how much is at stake. Running the same write/read ratio across three context sizes:
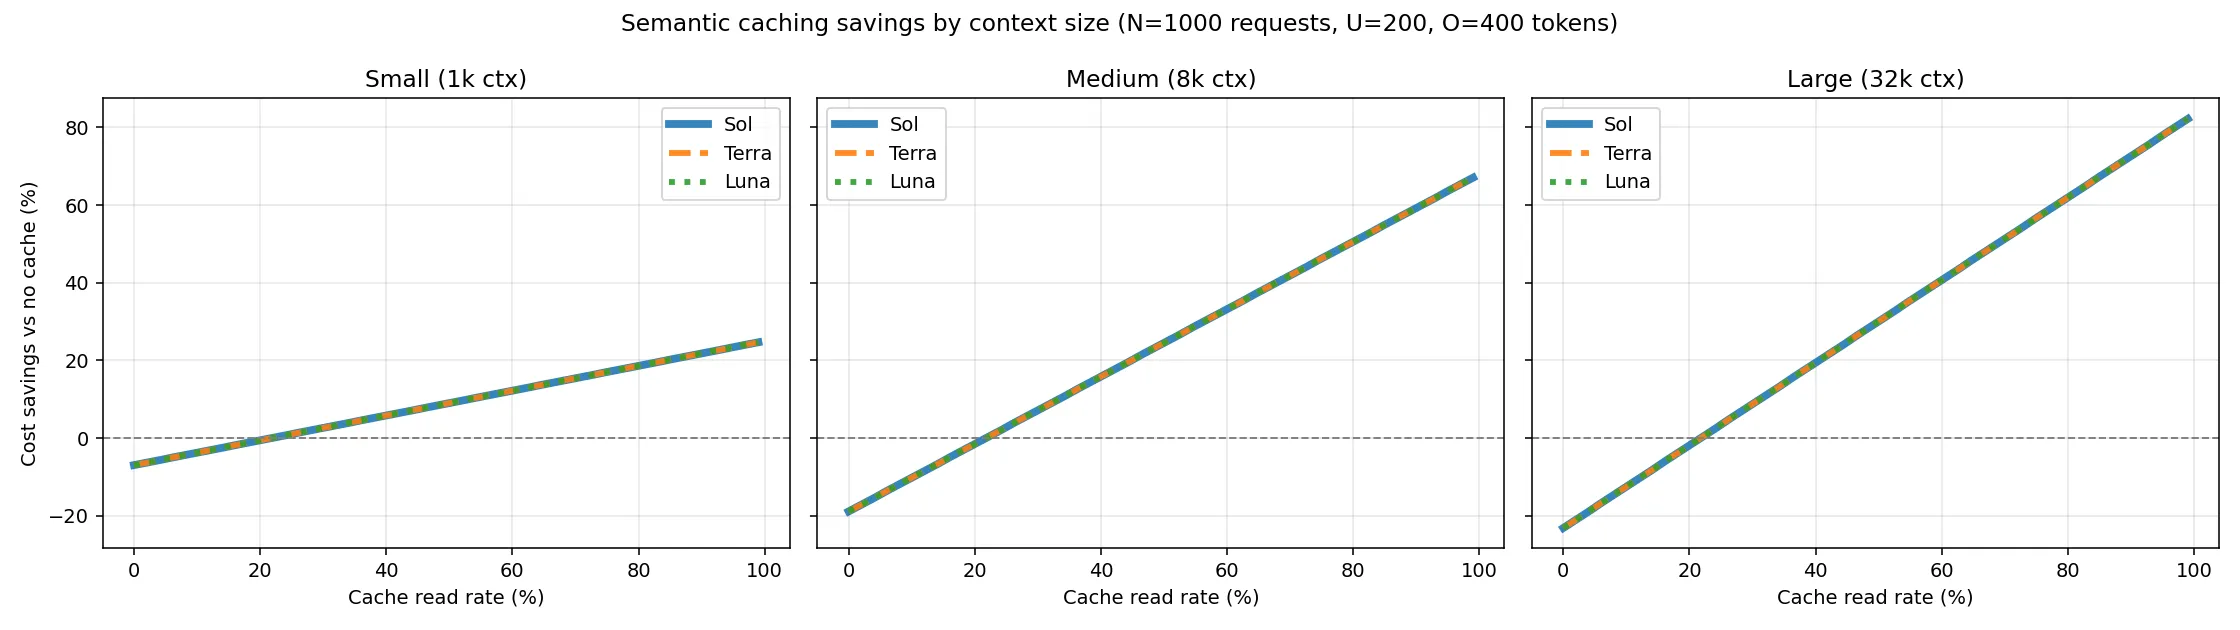
With a small shared context (1k tokens), savings are real but modest even at high repeat rates. With a large one (32k tokens, think long system prompts and big tool schemas), the same repeat rate produces dramatically larger savings, simply because there's more being discounted on every read.
A fixed, clean repeat rate is a nice teaching example, but real agent traffic isn't that tidy. Session lengths (how many calls share one cached context before it changes or expires) vary a lot. We modeled session lengths with a log normal distribution (mean 25 requests per session, heavy tail) and got a simulated write share of about 3%, with a median session of 23 requests and a 90th-percentile session of 58. That's nowhere close to the 78.3% break-even threshold. In this simulation, caching won comfortably: savings ranged from 24% on a small 1k-token context up to nearly 80% on a 32k-token one.
The one failure mode worth watching for: context that churns fast. If your agent's shared context changes every few requests instead of persisting across dozens, you can end up on the wrong side of that threshold, and caching becomes a cost instead of a saving.
Don't judge GPT-5.6's cache pricing by the list price alone. Model your own write/read mix against the 78.3% threshold. If your agent's context stays stable for tens of requests at a time, caching is very likely still a clear win under the new pricing, no matter which tier you're running.
TrueFoundry AI Gateway offre une latence d'environ 3 à 4 ms, gère plus de 350 RPS sur 1 processeur virtuel, évolue horizontalement facilement et est prête pour la production, tandis que LiteLM souffre d'une latence élevée, peine à dépasser un RPS modéré, ne dispose pas d'une mise à l'échelle intégrée et convient parfaitement aux charges de travail légères ou aux prototypes.





Les dernières nouvelles, articles et ressources envoyés dans votre boîte de réception