



October 30, 2026
|
5 min read



Blazingly fast way to build, track and deploy your models!
Shipping an LLM prototype now takes days. Model APIs require a single HTTP call, while frameworks handle much of the scaffolding. A small team can quickly demo a generative AI assistant. The hard part usually starts the following Monday, when live users, data, invoices, and compliance requirements arrive.
The model rarely changes between prototype and launch. Everything around it changes once production traffic arrives. An LLM in production must handle unpredictable traffic, meet latency targets, and keep inference spending within budget. It also needs auditable traces, access rules, failover, and clear ownership during failures.
This guide defines what LLM in production means and compares prototypes with live enterprise systems. It covers six infrastructure layers, deployment, evaluation, cost control, and governance. The goal is a reliable LLM application aligned with business goals while protecting user experience, data privacy, and operational control.
An LLM in production serves real users or downstream systems under live operating conditions. Its outputs reach customers, support queues, compliance processes, or automated decisions. A poor answer now carries real business cost. The risk increases when one use case connects model output with operational actions.
The production LLM meaning covers more than the model endpoint. It includes routing, version management, observability, cost controls, access policies, and governance. These layers turn ordinary LLM inference into an accountable production environment. A reliable LLM deployment therefore depends on the complete surrounding system.
Teams searching what is production LLM are usually asking about the operating system around the model. A prototype proves that an LLM can complete a task. A live deployment proves the entire system works reliably, safely, and within budget. It must also handle changing traffic, real user queries, and infrastructure costs created by sustained usage.
Most teams underestimate this gap because the demo already works. A prototype validates capability inside a controlled baseline. Production adds reliability, governance, cost, and compliance pressure under live traffic. The main factors now include model performance, response time, error rate, output quality, and cost attribution.
Two rows deserve extra attention. Cost tracking may seem harmless during a prototype, where a single shared API key may seem sufficient. Production teams need data points by team, feature, model, and environment. A shared key weakens chargeback, cost reduction work, and accountability across expanding LLM workloads.
Failure handling deserves the same level of engineering attention. Every cloud provider can experience an unexpected service outage. OpenAI reported elevated error rates across 10 API components on June 10, 2025. The incident lasted more than 15 hours from the first update through resolution. An application tied to one provider lacked a reliable fallback path.
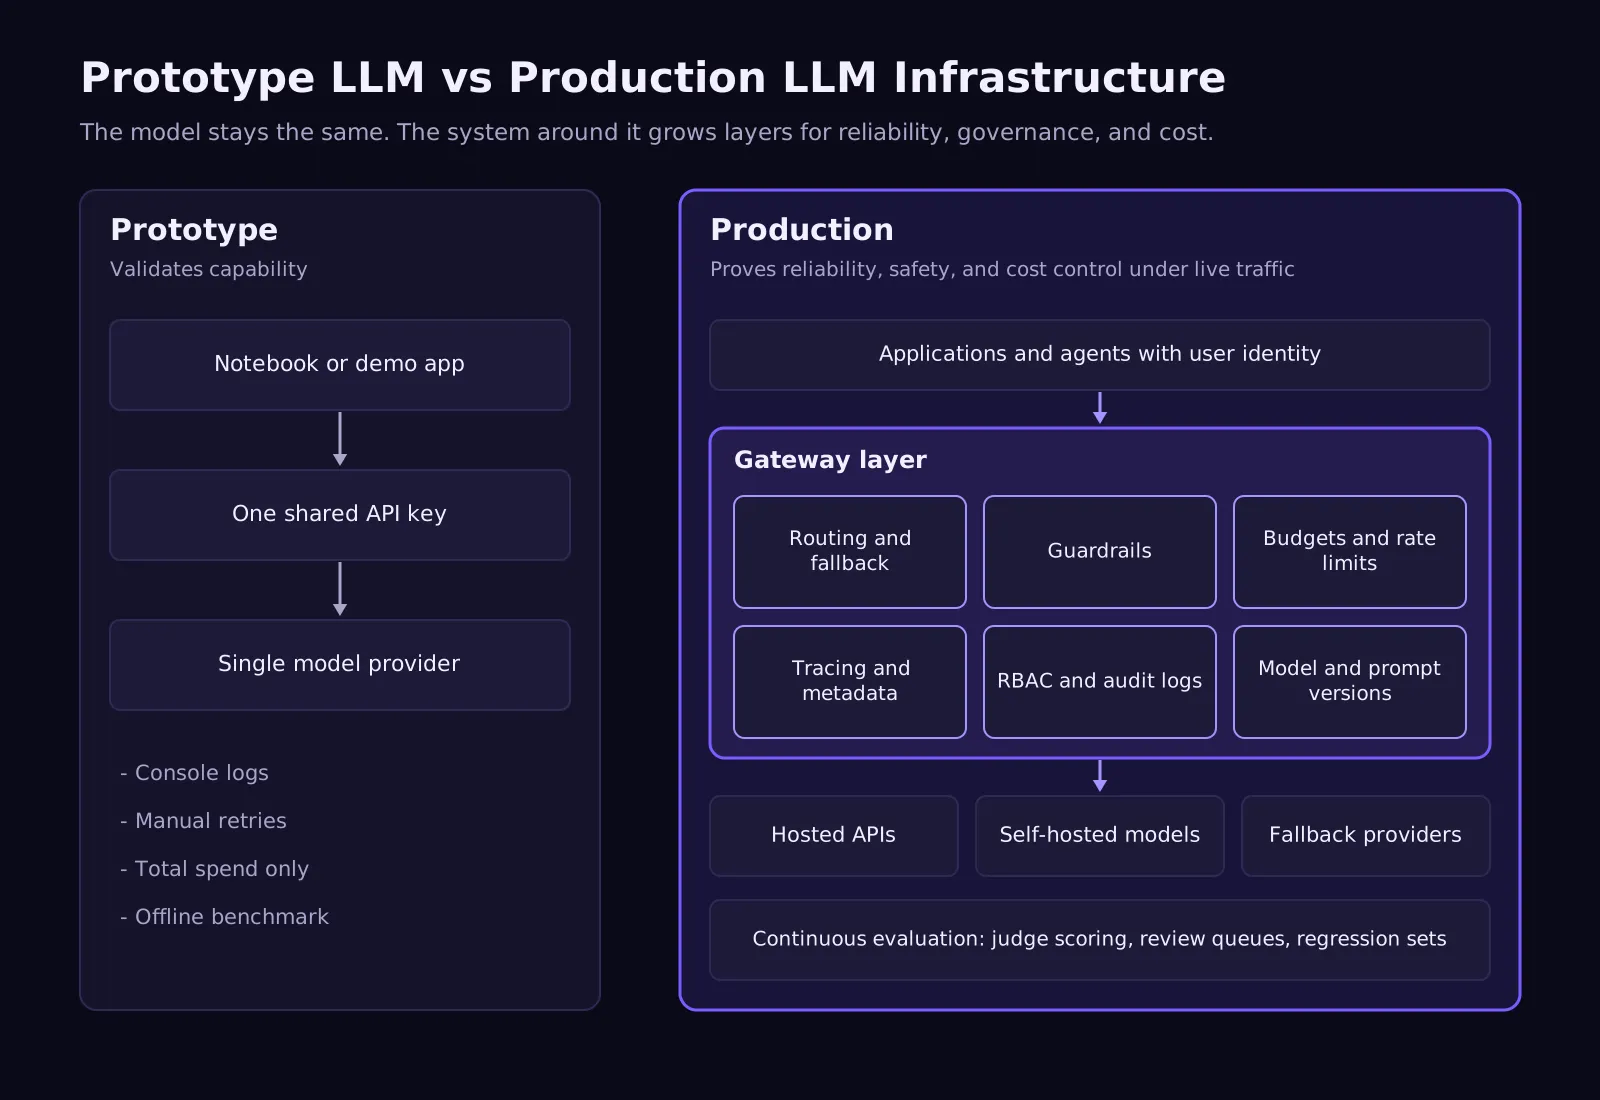
A production-ready LLM depends on the system around it as much as the model itself. Enterprise teams should verify six layers before workloads reach users. Together, these layers cover deployment architecture, serving, routing, observability, evaluation, and governance. Missing controls usually appear later as reliability, security, performance, or cost incidents.
The first decision is where each model runs, and data requirements often decide early. Teams can call hosted APIs, self-host open source models on cloud GPUs, or run models on-premises. The right choice depends on data residency, model control, throughput, and infrastructure costs. Teams must also consider their capacity for ongoing resource management.
Hosted APIs provide the fastest path because providers manage the GPUs. Self-hosting adds control over model size, GPU memory, and serving optimization. Teams must also manage queue depth, continuous batching, scaling, and capacity planning. A small model can reduce cost, while larger models need more GPU resources.
On-premises and air-gapped options matter when inference data cannot leave approved infrastructure. These choices are common where data privacy or regulatory rules restrict external processing. Most enterprises eventually use a mix of these deployment options. One chat app may call a hosted model, while a sensitive document pipeline runs privately inside the company VPC.
For an LLM in production, serving needs the same release discipline as any critical software service. Sending all traffic to a new model, prompt, or routing policy creates unnecessary risk. Model versions, prompt changes, and routing rules should move gradually, with clear rollback paths and measurable performance comparisons.
The core controls include canary releases, model version pinning, prompt versioning, rollback workflows, and A/B testing. Pinning matters because a floating model alias can change behavior without application changes. Prompt engineering requires similar release discipline, as wording can alter output quality and refusal patterns. It can also change task success across live traffic.
At the gateway, a canary becomes a routing rule. Weight-based routing can send 5% of traffic to a new target. The remaining 95% stays on the current baseline until results improve. Rollback then means setting the new target weight to zero, without changing application code or interrupting active users.
Prompts need the same disciplined versioning treatment as models do. A versioned registry can promote a tested prompt without a full redeploy. It can also restore the last working version after regression. TrueFoundry’s prompt versioning workflow supports immutable history, environment separation, comparison, and rollback for prompt-driven applications.
A production LLM should not depend on one provider. Outages, rate limits, latency spikes, and model behavior changes can disrupt critical workflows. Multi-provider routing lets teams select targets using cost, health, capability, or latency. Fallback chains keep the service available when the preferred model fails.
The application code can remain unchanged because it calls a single logical model name via the gateway API. A contextual LLM Gateway can keep provider-handling outside the application code. This pattern reduces migration work across Azure-hosted models, OpenAI endpoints, and self-hosted inference.
In TrueFoundry, a virtual model can use priority-based routing with retries and fallbacks:
routing_config: type: priority-based-routing load_balance_targets: - target: azure/gpt-4o priority: 0 retry_config: attempts: 3 delay: 200 on_status_codes: ["429", "500", "503"] fallback_status_codes: ["429", "500", "502", "503"] - target: openai/gpt-4o priority: 1 retry_config: attempts: 2 delay: 100 fallback_status_codes: ["429"]Here is how the gateway reads it:
The gateway sends traffic to the healthy target with the lowest priority number. Retry rules handle temporary failures before traffic moves elsewhere. Fallback codes define when the next target receives traffic. Health tracking can deprioritize unhealthy targets until recent failures leave the monitoring window.
Every request from an LLM in production needs a structured trace. Useful traces record user identity, model, provider, prompt version, tokens, cost, latency, and error details. Teams also need first token latency, total response time, output tokens, throughput, and error rate. These fields connect model behavior with the user experience.
These signals answer recurring production questions for engineering teams. Teams can identify why a response failed and which version of the prompt produced it. They can also compare SLA performance across providers or environments. Existing ML monitoring practices help, though natural language outputs require richer traces than ordinary machine learning metrics do.
Tag requests at the source so each user query carries business context. The Python example below keeps the existing OpenAI SDK and adds TrueFoundry metadata:
from openai import OpenAIclient = OpenAI( api_key="<TRUEFOUNDRY_API_KEY>", base_url="<GATEWAY_BASE_URL>",)response = client.chat.completions.create( model="support/production-chat", messages=[{"role": "user", "content": "Where is my order?"}], extra_headers={ "X-TFY-METADATA": '{"team": "support", "feature": "order-status", "env": "prod"}' },)Replace the two placeholders with the API key and base URL from your gateway's settings. The model value names a virtual model, so routing changes never touch this code. The X-TFY-METADATA header attaches string key-value pairs that the gateway uses for routing, rate limits, budgets, and metric filters.
Every trace for this call now carries team, feature, and environment. That is what makes a per-team cost report possible at the end of the month. For deeper analysis, the gateway exports traces via OpenTelemetry to platforms such as Grafana Cloud or Datadog, and TrueFoundry's post on observability in LLM workflows goes into trace design in more detail.
Production evaluation differs from offline benchmarking because real users generate messy, domain-specific requests. Search engines, RAG systems, and assistants also introduce retrieved context that can change unexpectedly. Long context window usage introduces another variable, as irrelevant evidence may alter the final answer or increase cost.
Teams need groundedness checks, refusal monitoring, PII detection, prompt injection filtering, and response safety checks. OWASP’s 2025 Top 10 ranked prompt injection first and sensitive information disclosure second. Effective best practices, therefore, combine evaluation with enforceable guardrails to prevent unsafe content from reaching users or downstream systems.
Run guardrails through an AI Gateway so applications follow consistent rules. TrueFoundry supports input, output, MCP pre-tool, and MCP post-tool guardrail points. A guardrail can block or transform payloads, including sensitive-data redaction before inference. Teams can start in audit mode to measure false positives before enforcing the policy.
An LLM in production needs financial controls before traffic scales. Token costs grow quickly when LLM agents trigger planning, tools, validation, and retries. Production systems need attribution, budgets, rate limits, cache policies, RBAC, audit trails, and identity-aware access before expensive work executes.
TrueFoundry currently separates request rate limits from monetary budgets. Rate rules can cap requests or tokens per time window, while budget policies control spend. Its token rate limits and budgets support separate request and token ceilings per user:
type: tenant-rate-limit-config/modelname: per-user-caplimits: requests_per_minute: 100 tokens_per_hour: 200000applies_to: type: per-usermode: enforceA breached rule returns HTTP 429 and identifies the applied rule in response metadata. That gives clients a clear backoff signal and gives operators an auditable control. Teams should also review model pricing, as equal token volumes can result in very different spending across model families.
Caching can reduce repeated inference work across production traffic. Semantic caching compares new requests with previous requests using embeddings. A cache hit returns a stored answer without another model call. TrueFoundry recommends starting with a 0.9 similarity threshold, then tuning based on observed quality and risk tolerance. Its semantic caching guide explains the tradeoff.
The six layers describe what a production stack contains. The steps below put those controls into a practical build order. Each subsequent step should connect architectural choices to the workload’s use case, risk profile, expected scale, and operating team. That sequence prevents platform decisions from drifting away from business goals.
Start with data and compliance requirements, as they can immediately eliminate unsuitable options. Hosted APIs fit teams prioritizing speed and lower operational work. Self-hosting fits cases needing deeper model control or predictable compute. VPC, on-premises, and air-gapped options become important when data residency or regulatory requirements limit external processing.
Write the decision down for each workload, including the data classification behind it. That record becomes useful when teams revisit costs later. It also prevents a cheaper cloud provider option from quietly replacing a deployment selected for regulatory or privacy reasons.
Put a gateway between applications and models before several teams start building independently. The gateway centralizes routing, authentication, caching, guardrails, policy, and observability. Without one, every application team has to recreate retries, keys, logging, and provider handling. Governance then varies across workloads, and one policy change can require edits across many codebases.
Most gateways expose an OpenAI-compatible interface, so early adoption often requires changing a base URL. A single gateway can support different surfaces without changing governance patterns. A chat assistant, a RAG search tool, or a social pipeline can share a single policy boundary. That includes workloads using LinkedIn and Twitter content.
Version both models and prompts before production traffic reaches users. One prompt edit can break a workflow as easily as a model upgrade. Define rollout rules, approval gates, regression datasets, and rollback procedures before launch. Every candidate should run against anonymized production examples before a reviewer promotes the new version.
This discipline keeps prompt changes connected with measurable outcomes. It also makes rollback predictable when quality drops. Version identifiers should travel with traces across the full request path. Engineers can then connect responses with exact model and prompt configurations.
Production systems need live quality monitoring because offline benchmarks cannot represent every real request. Track factuality, relevance, safety, refusal rates, latency, and user feedback. Send low-confidence responses toward human review when business risk requires additional judgment.
Failed responses should be fed into regression datasets, so incidents strengthen future releases. Automated scoring can monitor large samples, while human labels provide a quality baseline for sensitive decisions. This process turns evaluation into continuous release control rather than a one-time prelaunch test.
Before launch, set token budgets by team, application, model, and environment. Add circuit breakers for agents, fallback rules for provider failures, and RBAC for model access. A per-run step or token cap can prevent a looping agent from consuming the daily allocation with a single request.
Every request should carry identity, model, cost, and environment metadata. Finance can attribute spend, engineering can debug incidents, and compliance can reconstruct access. This shared metadata also supports policy optimization as new models, teams, and workloads enter the platform.
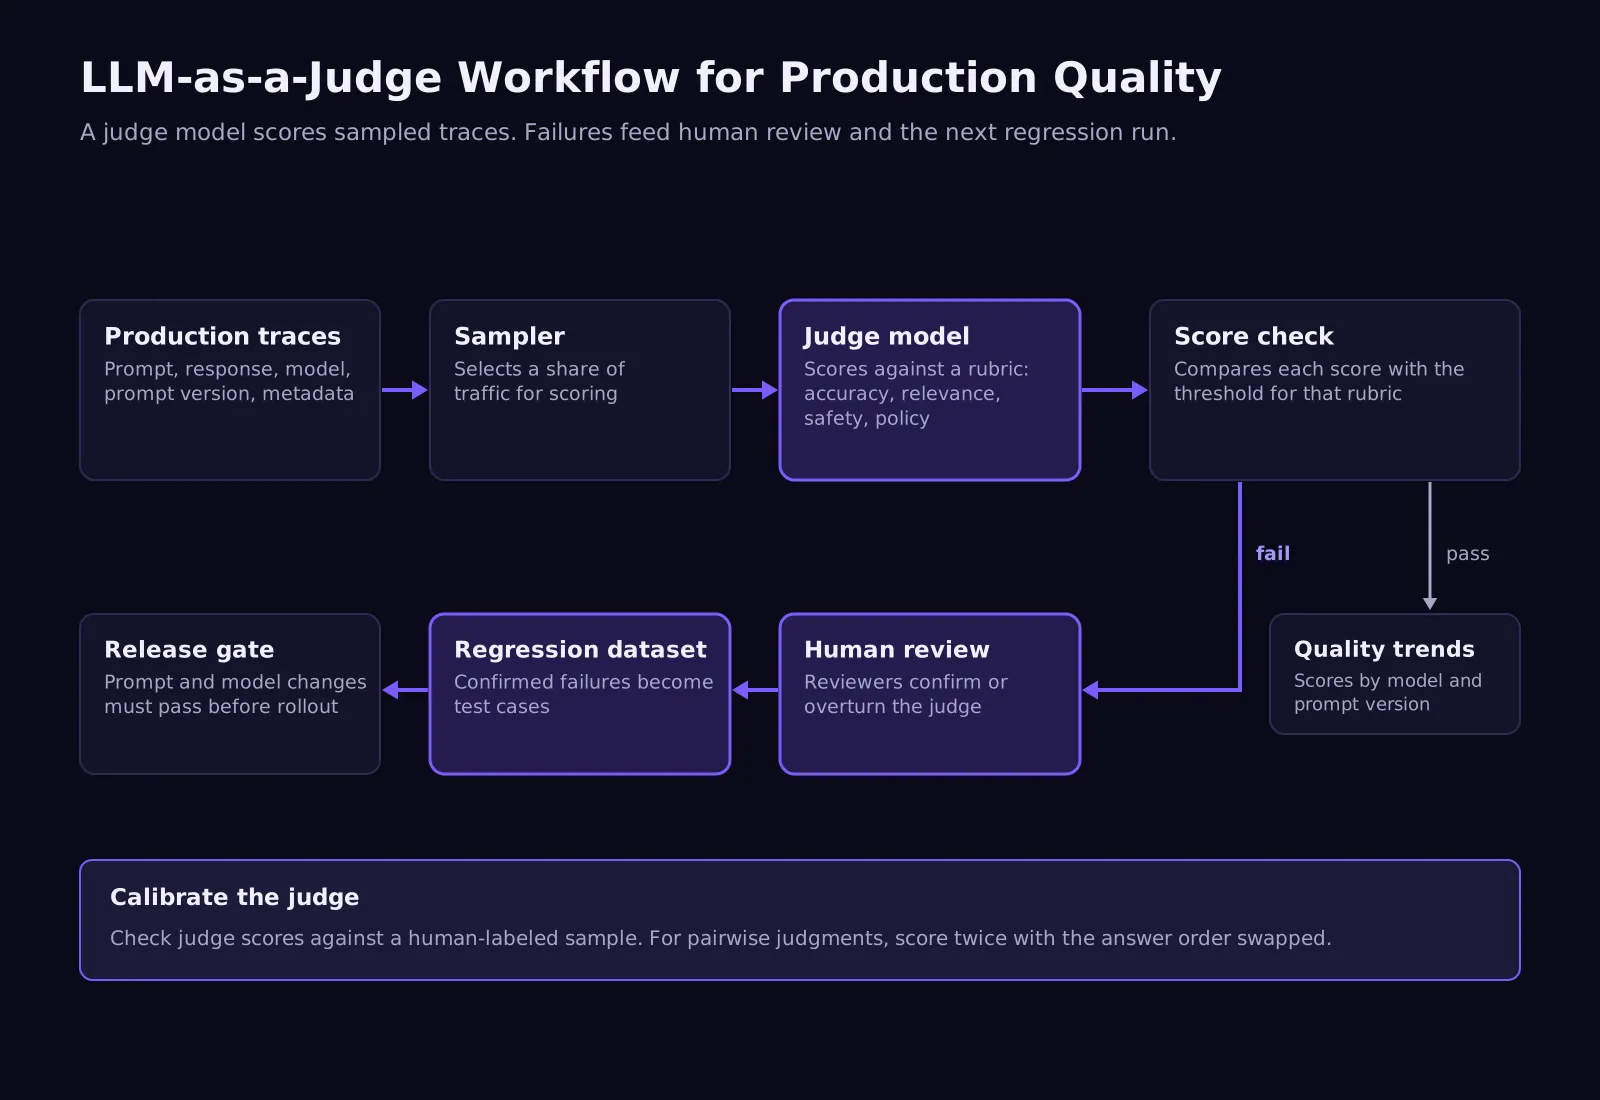
Continuous evaluation needs a scorer that can handle production volume. LLM as a judge uses a separate model to grade the primary production LLM against defined criteria. A judge can score accuracy, completeness, relevance, policy compliance, or safety using a written rubric and structured result.
In production, judges can score sampled traces asynchronously without requiring humans to read every response. They can also run inline before a response reaches users, which adds another model call and additional latency. Some input checks can run in parallel with the primary request, while output checks must wait for generated content.
Judge models can exhibit measurable, repeatable evaluation bias. One study evaluated 12 LLM judges across more than 100,000 instances and found systematic position bias. Its strength varied widely across different judges and tasks. Pairwise evaluation should therefore swap answer order, while teams should calibrate judge results against human-labeled examples before trusting them.
LLM as a judge should not replace human oversight for high-risk decisions. It works best as an early-warning layer for quality drift, unsafe patterns, and regressions. A smaller judge can also reduce evaluation cost when its performance meets the required standard.
Production failures often arrive after the first successful request. They appear inside governance, evaluation, cost controls, access controls, and audit readiness. These concerns often look secondary during early prototypes. They become central once the potential of LLMs reaches more business workflows.
Three scenarios appear repeatedly:
Each scenario is actually a production architecture problem. Gartner predicted that more than 40% of agentic AI projects will be canceled by 2027. It cited escalating costs, unclear business value, and inadequate risk controls as the main causes.
Teams avoid these failures by adding governance, observability, and cost controls before launch. When an incident happens, the platform team should trace the missing control and fix it centrally. That response prevents the same failure from spreading across other teams or workloads.
TrueFoundry provides an enterprise control plane for production AI systems. Its gateway layer sits between applications, model providers, MCP servers, and agent workflows. It centralizes routing, observability, governance, cost controls, and guardrails across hosted and self-managed models.
The AI Gateway centralizes model access, routing, guardrails, observability, and cost controls. These policies apply consistently across production LLM workloads. This matters when several teams use different models, providers, prompts, environments, or rate-limit requirements.
A security team can apply a PII rule centrally rather than rebuilding protection in every service. The same policy layer can support authentication, metadata-based controls, budgets, and routing. Centralization gives engineering teams one operating model while security and finance teams gain consistent oversight.
The LLM Gateway routes requests to hosted and self-hosted models through a single interface. Virtual models support priority-, weighted-, and latency-based strategies, as well as retries and fallbacks. Teams can therefore change providers without rebuilding application integrations or hardcoding model vendors inside every service.
Provider dependency falls because each workload can use the model that fits its requirements. Routing can optimize availability, latency, capability, or cost. Application teams use a single logical model name, while platform teams adjust targets via configuration.
The MCP Gateway governs how AI systems reach tools, APIs, databases, and internal services. It supports enterprise identity, OAuth-based authorization, RBAC, metadata policies, and tool-level observability. These controls matter when model responses move beyond recommendations and begin triggering actions inside business systems.
Tool governance should preserve the user’s identity and permissions wherever possible. An agent should reach only the tools that its policy allows. Rate limits and audit records add another boundary by controlling request volume and recording what tools executed
The Agent Gateway governs multi-step agent workflows with retries, timeouts, quotas, and access controls. It also provides end-to-end traces across workflow execution. Runtime limits can stop looping behavior, excessive tool use, or runaway token consumption.
Agent observability then connects each step with models, tools, latency, tokens, and cost. This matters because autonomous workflows can trigger multiple model and tool calls from a single request. Workflow-level context makes debugging, governance, and incident reconstruction far clearer.
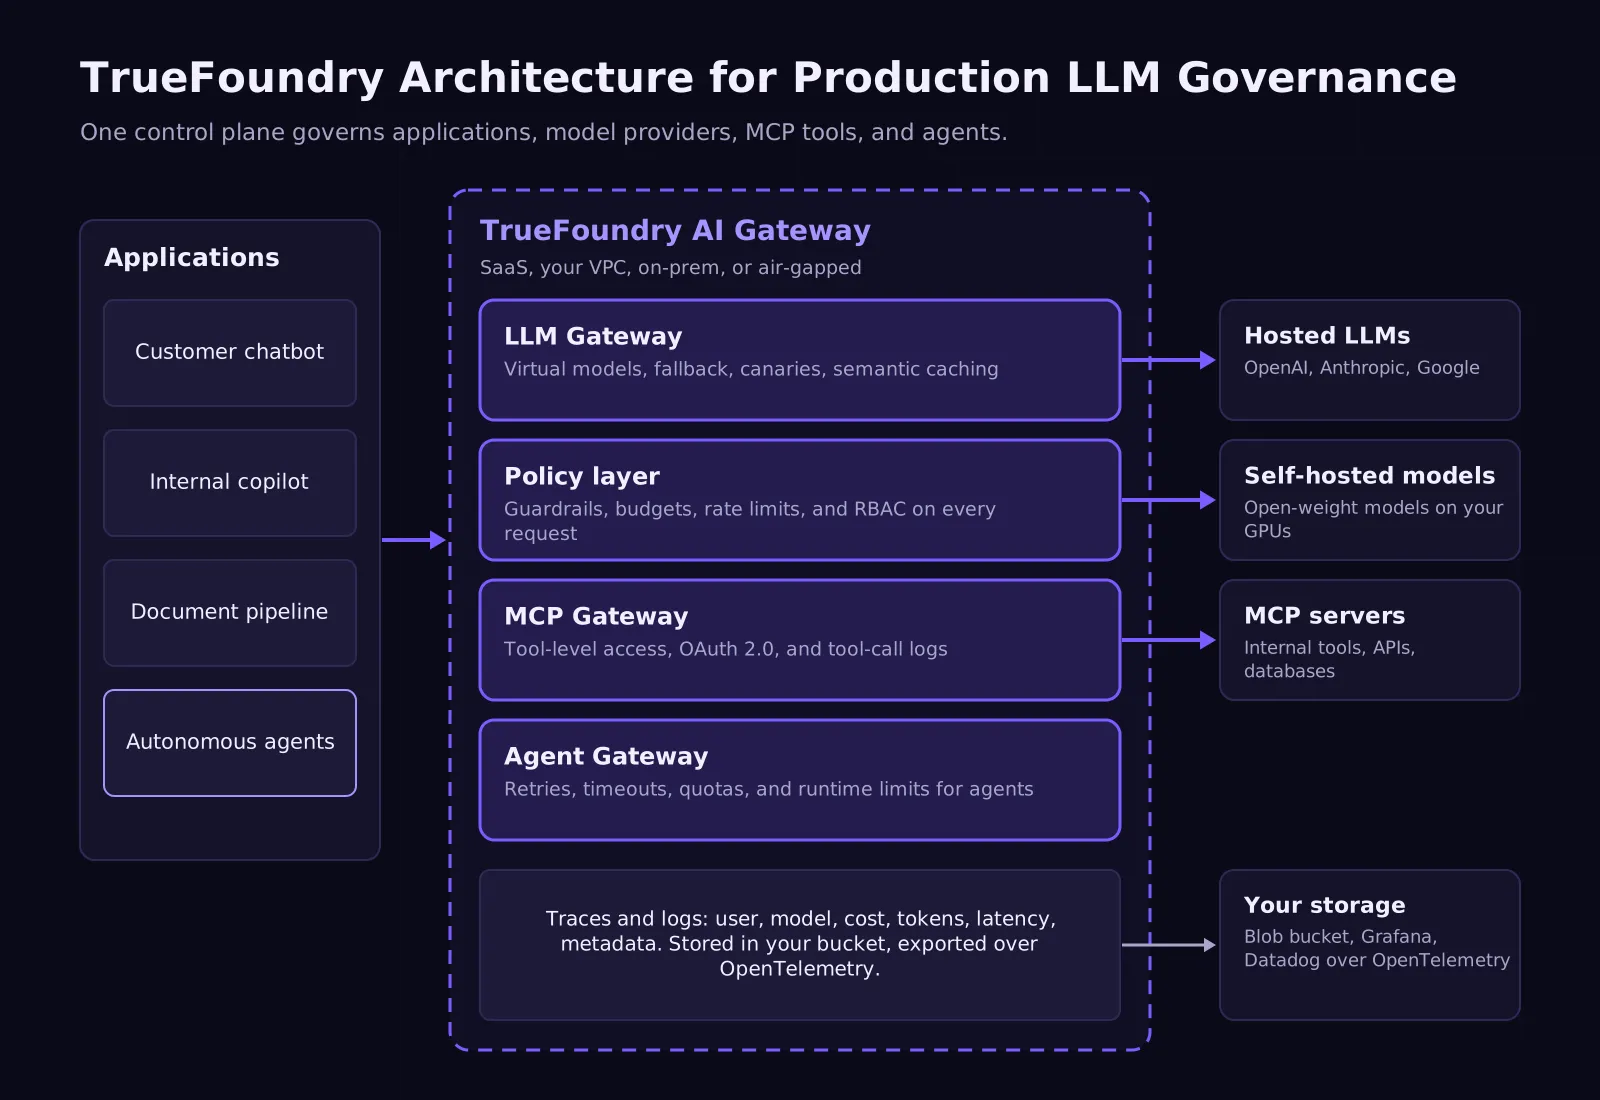
TrueFoundry can keep request logs inside the customer's environment. In the hybrid deployment, the gateway plane runs in your infrastructure and writes request and response data to your own blob storage in Parquet format, where tools such as Spark or DuckDB can query it. Data routing rules can send traces from different workloads to different buckets.
Each trace carries user identity, model, cost, token counts, latency, and the metadata your applications attach. TrueFoundry's managed infrastructure is SOC 2-, ISO 27001-, GDPR-, and HIPAA-compliant.
The company also announced ITAR-compliant gateway deployments for on-premises and private VPC environments in December 2025, and air-gapped deployments keep governance data entirely off external infrastructure.
If you want to see these controls in action on your own models and traffic, book a demo with the TrueFoundry team.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.























