September 29, 2026
|
5 min read

Published: September 29, 2026

Blazingly fast way to build, track and deploy your models!
A judge is a model given three things: an output to assess, a rubric describing what “good” means, and an instruction to return a machine-readable verdict — pass/fail, a score, or a preference between two candidates.
It exists because the alternative does not scale. Exact-match metrics work when there is one right answer; they are useless for a support reply where five answers are all correct. Humans grade those well and slowly. A judge sits in between: worse than a careful human, far better than a string comparison, fast enough for thousands of samples. Treat it as a cheap, noisy, human-correlated proxy.
The most common mistake here is treating offline evaluation and online gating as one thing with two deployment targets.
The failure row is the one to internalise. Offline, a wrong score costs a decision you revisit next sprint; online, it is a user staring at an error. So tune an online judge for precision even at the cost of recall. Copying a rubric across modes is how teams end up blocking a few percent of good traffic.
Judges are good at criteria that are describable but not computable — is this grounded in the retrieved context, is the tone right for a clinical setting. You can write the rule in a paragraph but not as a regex. They fall over in three ways.
Position bias. Given two candidates, judges favour one slot; reverse the order and a meaningful share of verdicts flip. The mitigation is to judge each pair twice with positions swapped and count only agreement, which doubles your cost.
Verbosity bias. Longer answers score higher, roughly independent of whether the extra words added anything. This quietly pushes production prompts toward padding: you optimise against the judge, the judge rewards length, the token bill rises, nobody connects the two.
Self-preference. A model rates text resembling its own generations more highly. If GPT judges GPT output the score is flattered — the strongest argument for a judge from a different family than the model under test.
Judges are also badly calibrated on continuous scales: ask for a score out of 10 and everything clusters at 7 and 8. Binary pass/fail against a tight criterion is far more reliable. And a judge cannot verify a fact it does not have — with no reference material you get its priors, not a fact check.
Different family from the model under test, because self-preference is real and free to avoid. Smaller than you think, because judging is classification against a long prompt, not reasoning. Pinned, not floating, because a provider alias that rolls forward moves your quality bar without a code change. And a lower p99 than the thing it guards, or the judge becomes your tail latency.
Then the arithmetic. An inline judge is a second inference; check both prompt and response and it is two. That is not overhead you can engineer away, so the question is which slice of traffic:
If you can express the rule as code, express it as code.
They ship the offline rubric into the request path. A ten-dimension rubric that works in a nightly run becomes a slow, high-variance blocker in production. Online rubrics should be one criterion, binary, worded tightly enough for a small model to answer consistently.
They never measure the judge. It is a model in production with no evaluation of its own. Hand-label a few hundred real examples and read precision and recall separately. If you cannot state the false-positive rate, you cannot state what fraction of users the guardrail is failing.
They roll straight to blocking. A judge that is 90% accurate blocks one in ten good answers the day you enforce it. Audit first, read a week of traces, then promote.
They forget streamed responses. Stream tokens to the browser and an output judge has nothing to judge until the stream ends. Most gateways, TrueFoundry included, skip output guardrails on streaming requests.
TrueFoundry has no eval product. No eval page, no datasets, no experiment tracking, no scoring UI. Offline evaluation belongs to platforms built for it, and TrueFoundry’s role is exporting traces over OpenTelemetry — traces, not OTEL metrics, from that screen. For a scored dataset and a leaderboard, use Braintrust, Arize or an equivalent and point the exporter at it.
What TrueFoundry implements is the online half: a judge running as a guardrail in the request path, its verdict, latency and token spend on the same trace as the request it guarded.
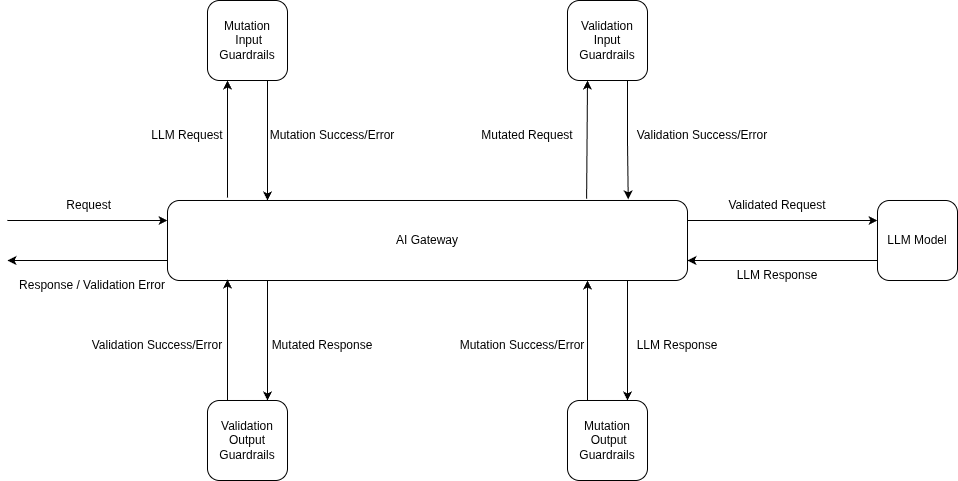
Each judge below is a small service you deploy, called by the gateway as a rail through the custom-guardrail contract. That contract has one rule worth memorising: HTTP 2xx means the guardrail ran to completion, and the policy decision lives only in the JSON body. The docs warn that a “blocked” signalled as HTTP 400 may be read as a runtime error and let through. Return 2xx with verdict: false.
NeMo runs as a FastAPI wrapper deployed on TrueFoundry — no native NeMo SDK calls from the gateway, no client SDK changes in your app. Inside, it uses a small judge LLM plus Colang, a domain-specific language, to evaluate prompts and responses through the self_check_input and self_check_output rails. The rubric lives in the Colang bundle, where config/prompts.yml holds few-shot examples that in v1 catch DAN-style role-play, “ignore previous instructions”, system-prompt extraction and policy-bypass markers.
The detail that matters operationally: the judge LLM calls back through the same TrueFoundry gateway. The wrapper’s .env carries TFY_BASE_URL, TFY_API_KEY and JUDGE_MODEL — the doc’s example is openai-main/gpt-4o-mini. Because the judge’s inference is gateway traffic, its tokens, cost and latency land in the same dashboards as everything else, so you can see what guardrails cost. Swapping judges is one line: change JUDGE_MODEL (the doc shows openai-main/gpt-4o) and redeploy.
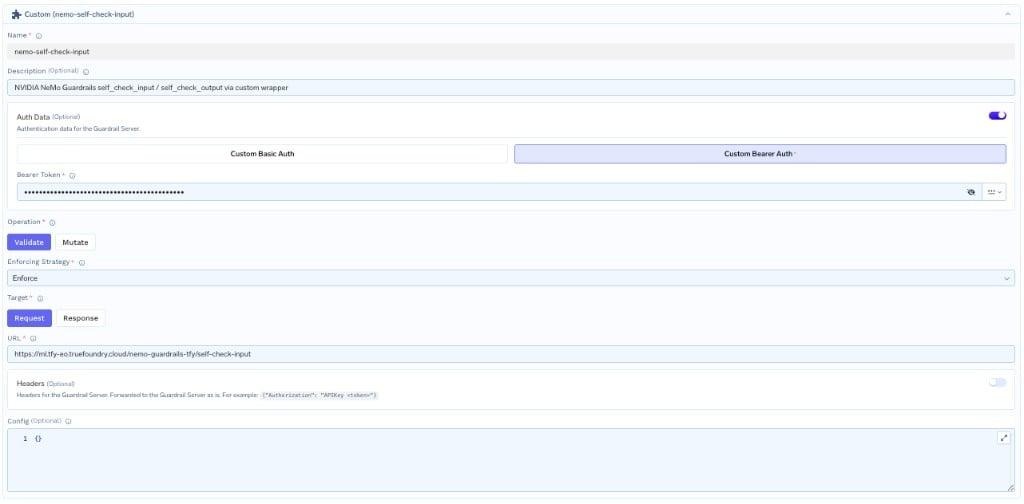
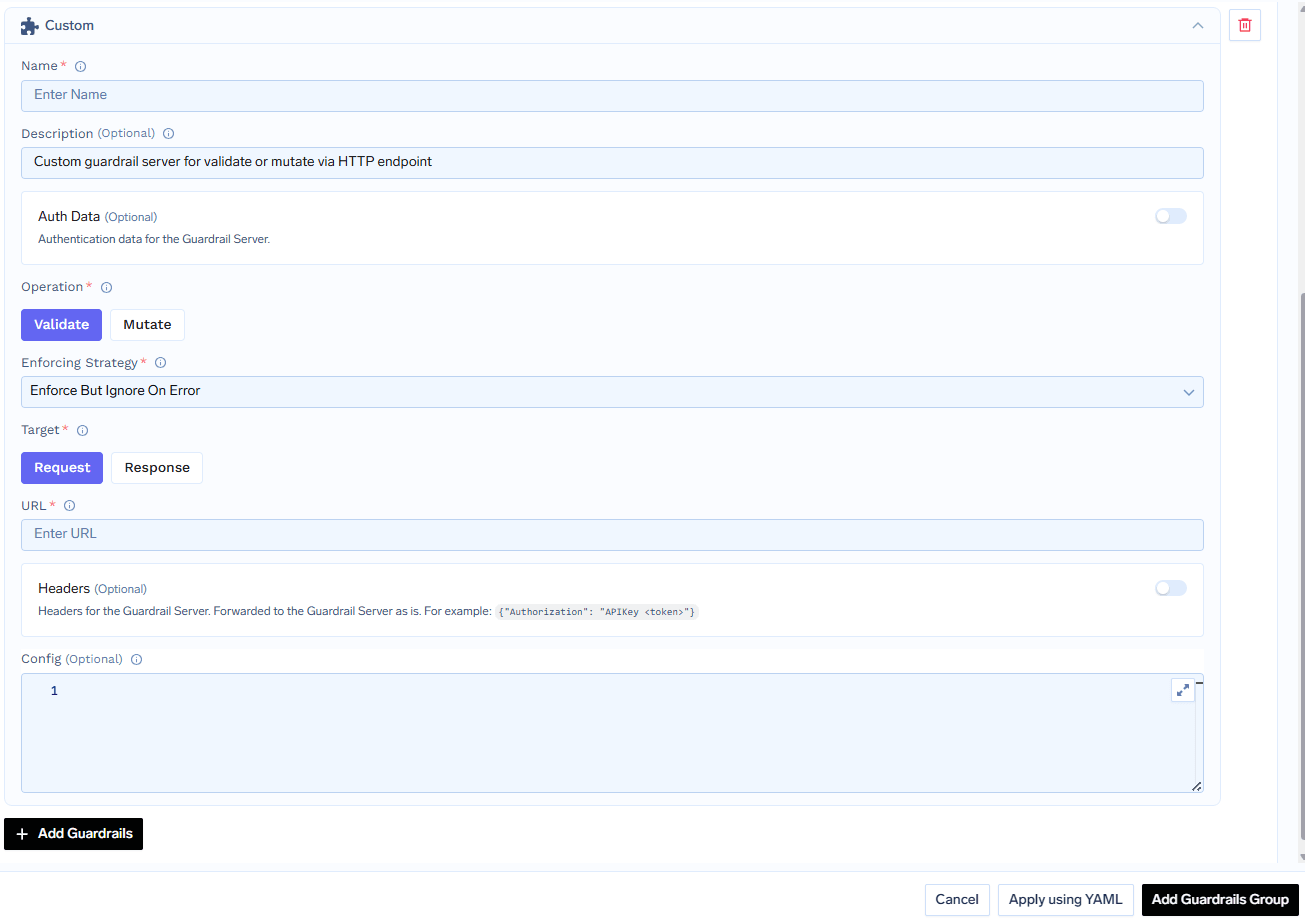
Register two Custom Guardrail Configs, both Validate — selectors nemo-self-check/nemo-self-check-input and .../nemo-self-check-output — with Enforce But Ignore On Error recommended. The verdict contract is tiny: HTTP 200 plus {"verdict": bool, "message": Optional[str]}; a genuine failure arrives as 5xx.
The gateway dispatches the input rail call and the model call in parallel, so the judge does not add to time-to-first-token; on a block it cancels the in-flight model call. The output rail runs sequentially, because it must.
The docs are candid about the price. Under known limitations, in their own words: every guarded request adds one or two LLM calls, one per direction. They also note there are no streaming-aware guardrails, because the contract is buffered, and that in-memory state is per-replica.
Patronus is the closest thing to a turnkey judge in the catalogue, and it is Validate-only — operation is the literal "validate", and the docs state it cannot mutate.
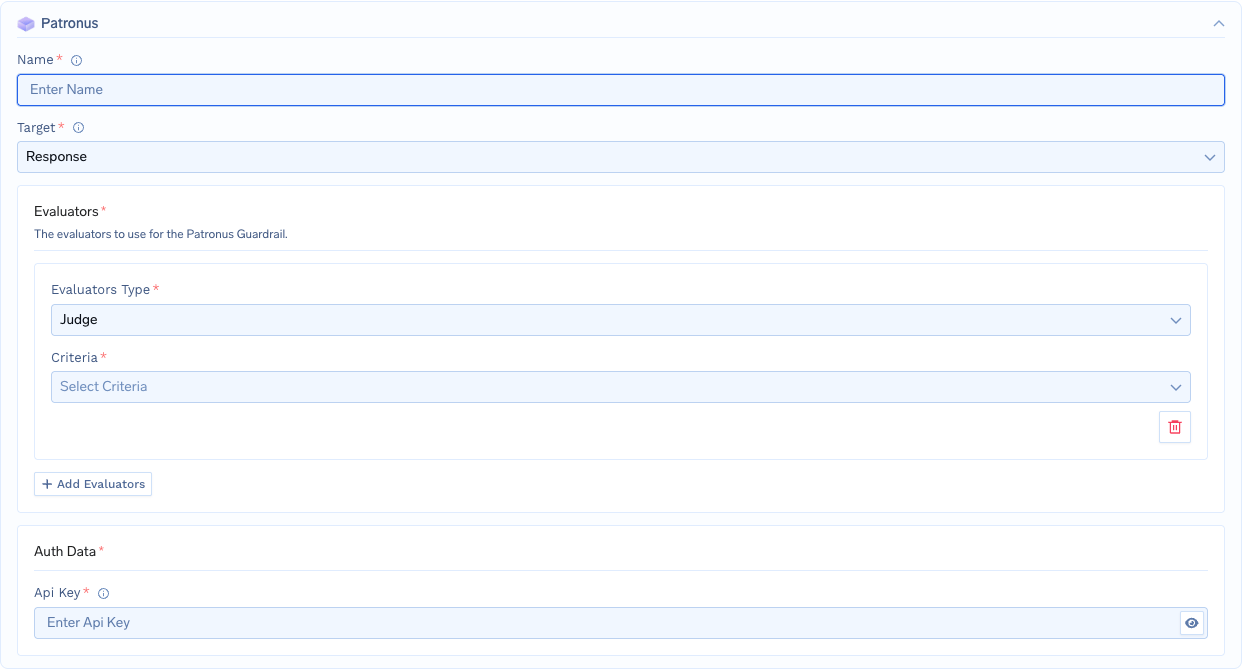
Config type is integration/guardrail-config/patronus. Set target to request or response, then list evaluators; six types exist — answer-relevance, glider, judge, pii, phi, toxicity. The judge type is the LLM-as-a-judge one, and its criteria field is required. All fifteen documented values:
The sibling glider family adds five: patronus:is-compliant, patronus:is-factually-consistent, patronus:is-good-summary, patronus:is-harmful-advice, patronus:is-informal-tone.
Against the decision table above, the split is obvious: is-json and is-csv are format checks a validator does better and cheaper, while no-harmful-therapeutic-guidance and is-good-summary are the prose-only criteria a judge is for.
If data.results[].evaluation_result.pass is false, the request is blocked and a 400 returned. The doc’s example response shows evaluator_id: "judge-large-2024-08-08", evaluator_family: "Judge", profile_name: "patronus:prompt-injection", pass: false, score_raw: 0, evaluation_duration: "PT4.44S", usage_tokens: 687, and evaluation_metadata.highlighted_words. The page claims response times as low as 100 ms; that 4.44-second example duration is a reminder that a judge’s tail is not its median.
Most of Guardrails AI is deliberately not a judge. Its v1 bundle — DetectPII, SecretsPresent, ToxicLanguage, ProfanityFree across seven endpoints — runs locally in the wrapper pod, no LLM round-trip per request, sub-100 ms steady-state latency.
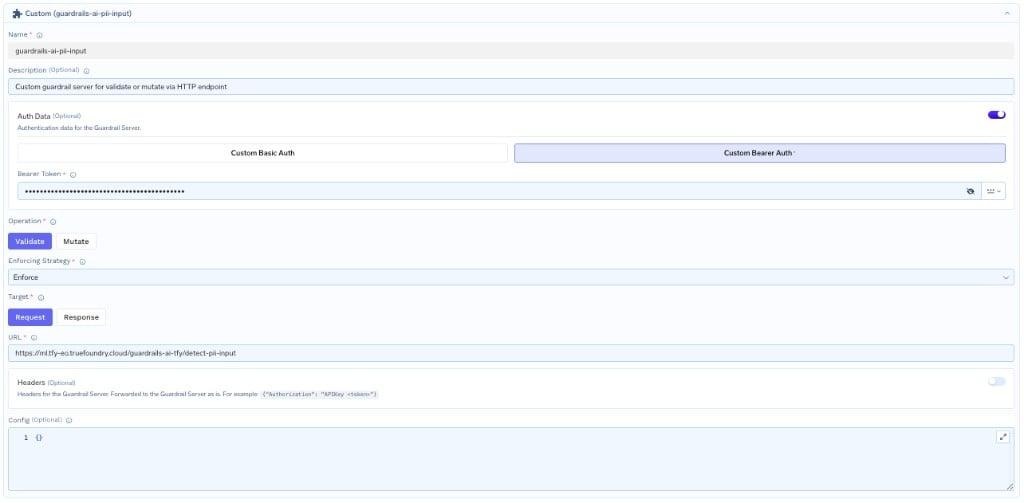
The judge-based validators are an opt-in tier from the Hub: hub://guardrails/restricttotopic (LLM-judged), hub://guardrails/provenance_llm — which the docs mark expensive — and hallucination_check. Configure them via LITELLM_* environment variables and route them through your gateway for unified observability, the same pattern NeMo uses for JUDGE_MODEL. Cheap alternatives sit beside them: competitor_check is allowlist-based, regex_match is, in the docs’ word, cheap.
TrueFoundry’s hallucination page documents four types — factual, contextual, logical and source — and exactly two implementation routes: AWS Bedrock Guardrails, where you enable Grounding and Relevance, set Guardrail Action to Block and set a threshold; or a custom guardrail on the template repo.
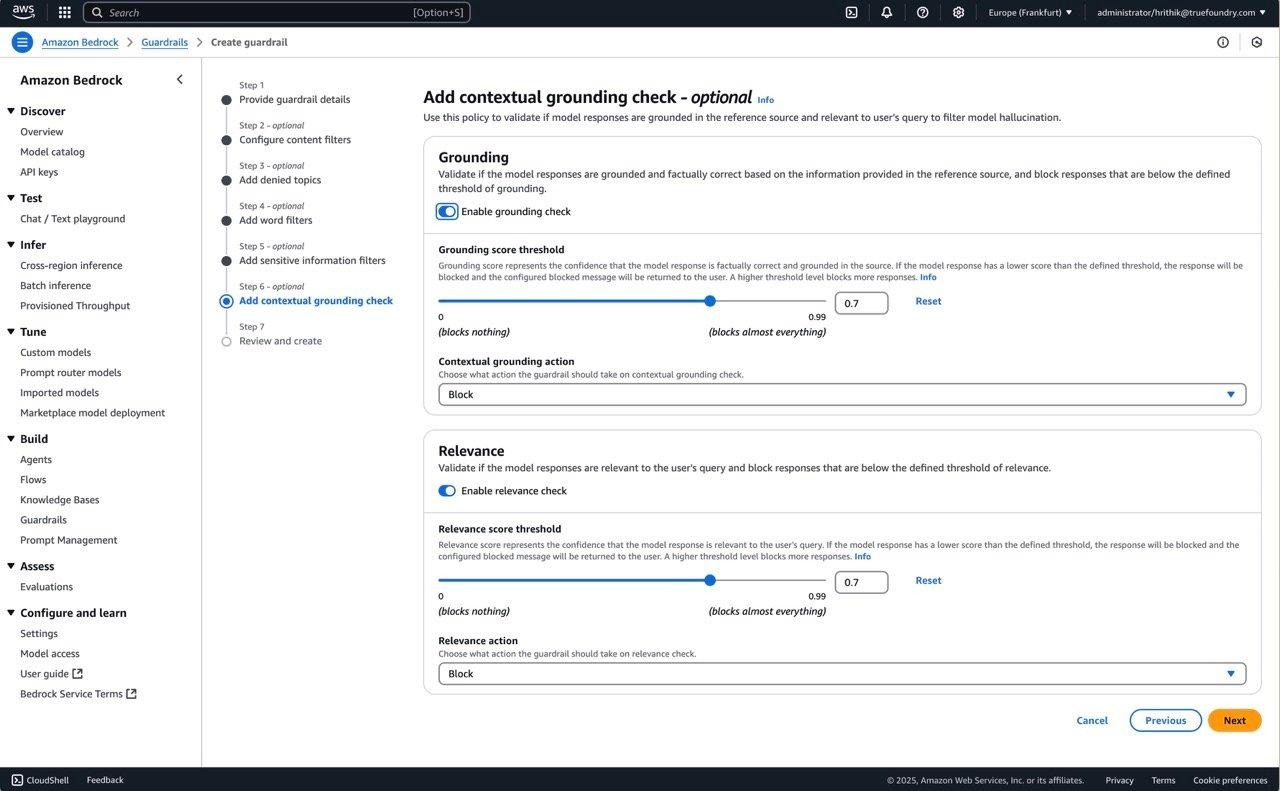
The docs say plainly that the template repository does not currently include a hallucination guardrail out of the box — it ships examples such as PII redaction and NSFW filtering. The custom route is real work, not a checkbox.
The Playground runs all four hooks, so you can fire an adversarial prompt at the input rail before any policy exists.
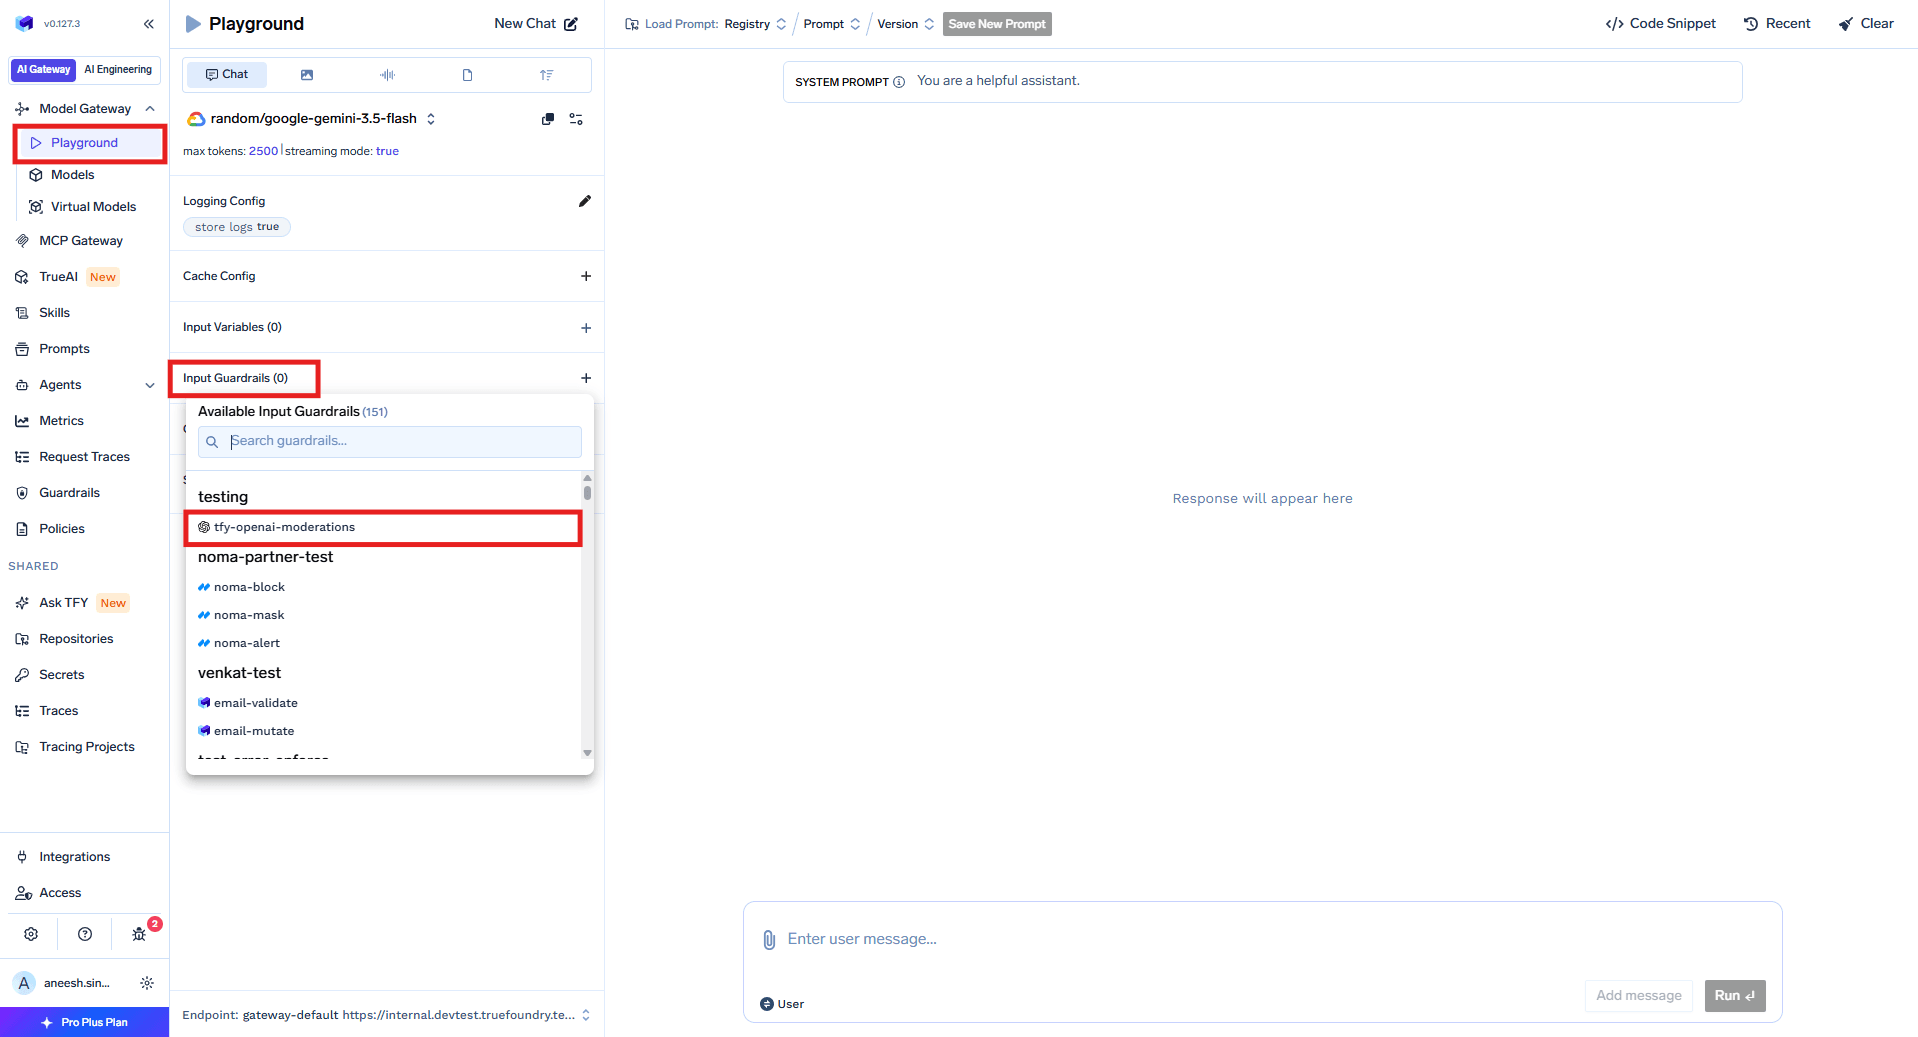
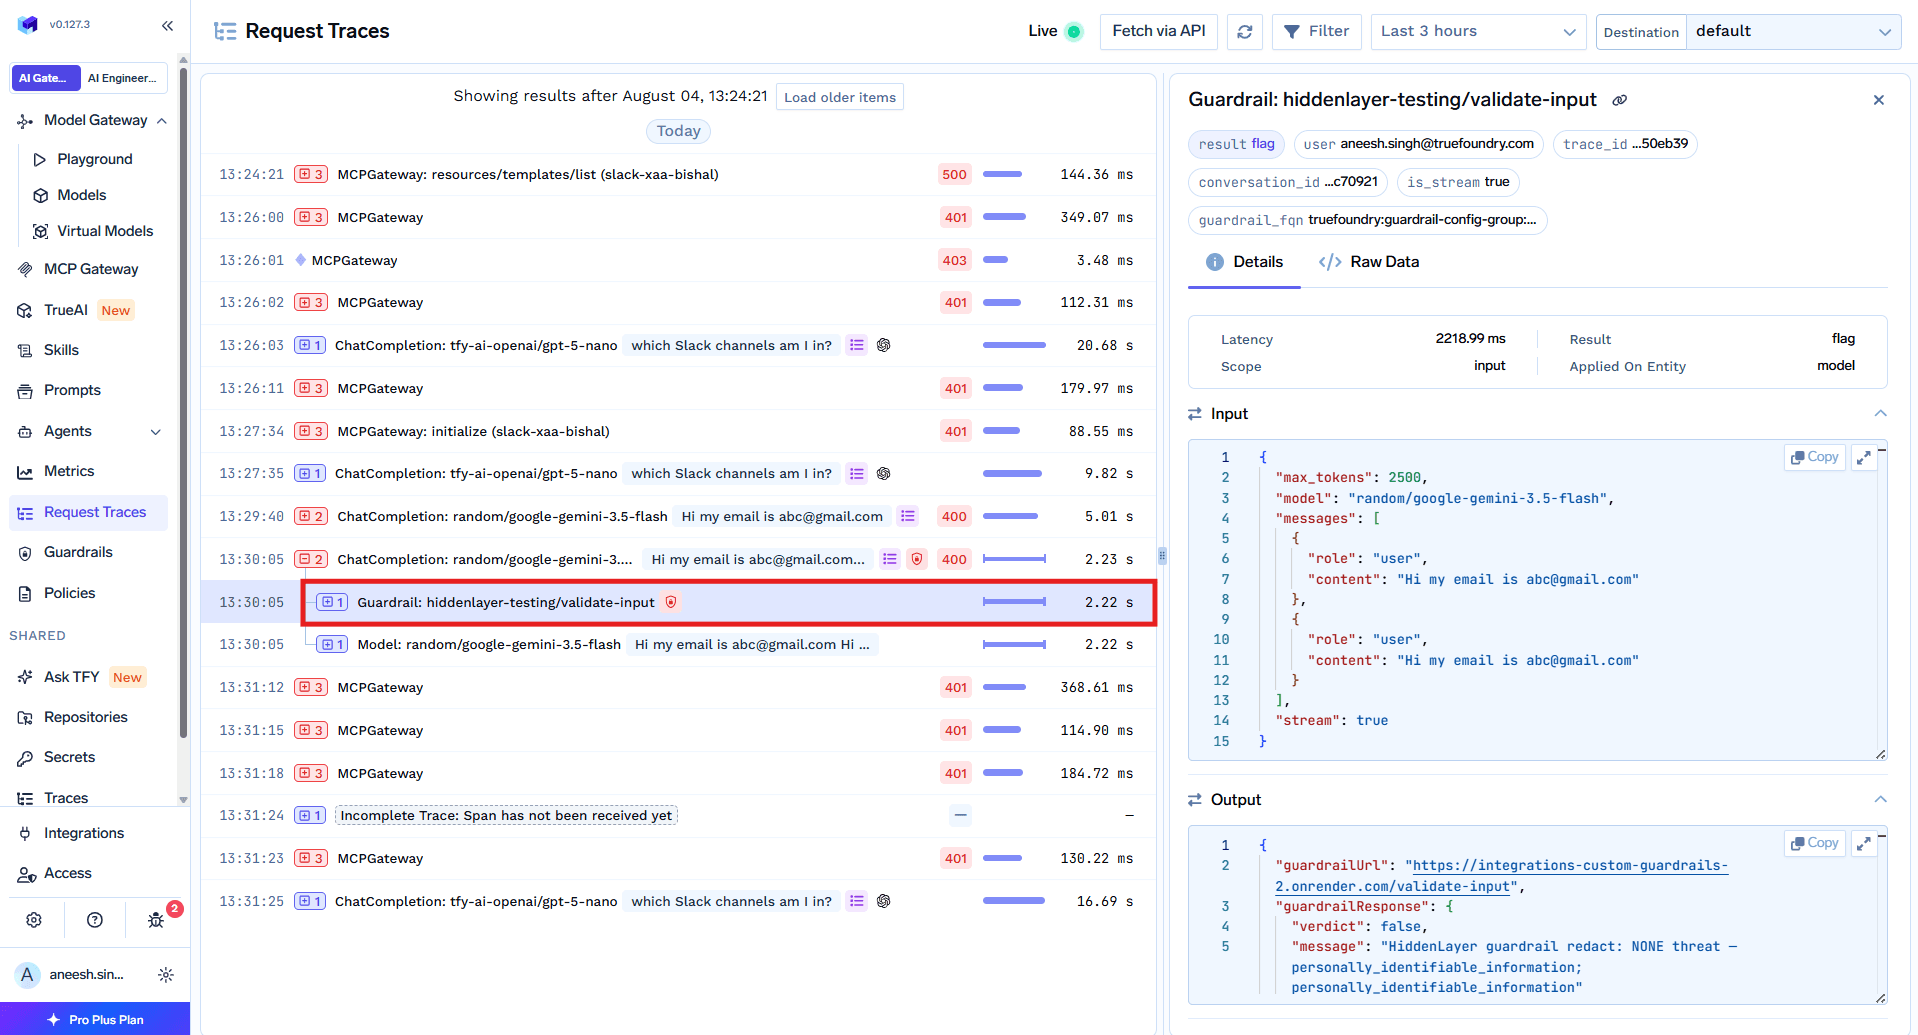
Once live, each guardrail evaluation is its own span in Monitor → Request Traces with execution time, result, scope, input and output — logged for blocked requests too, so a denied call is evidence rather than a gap.
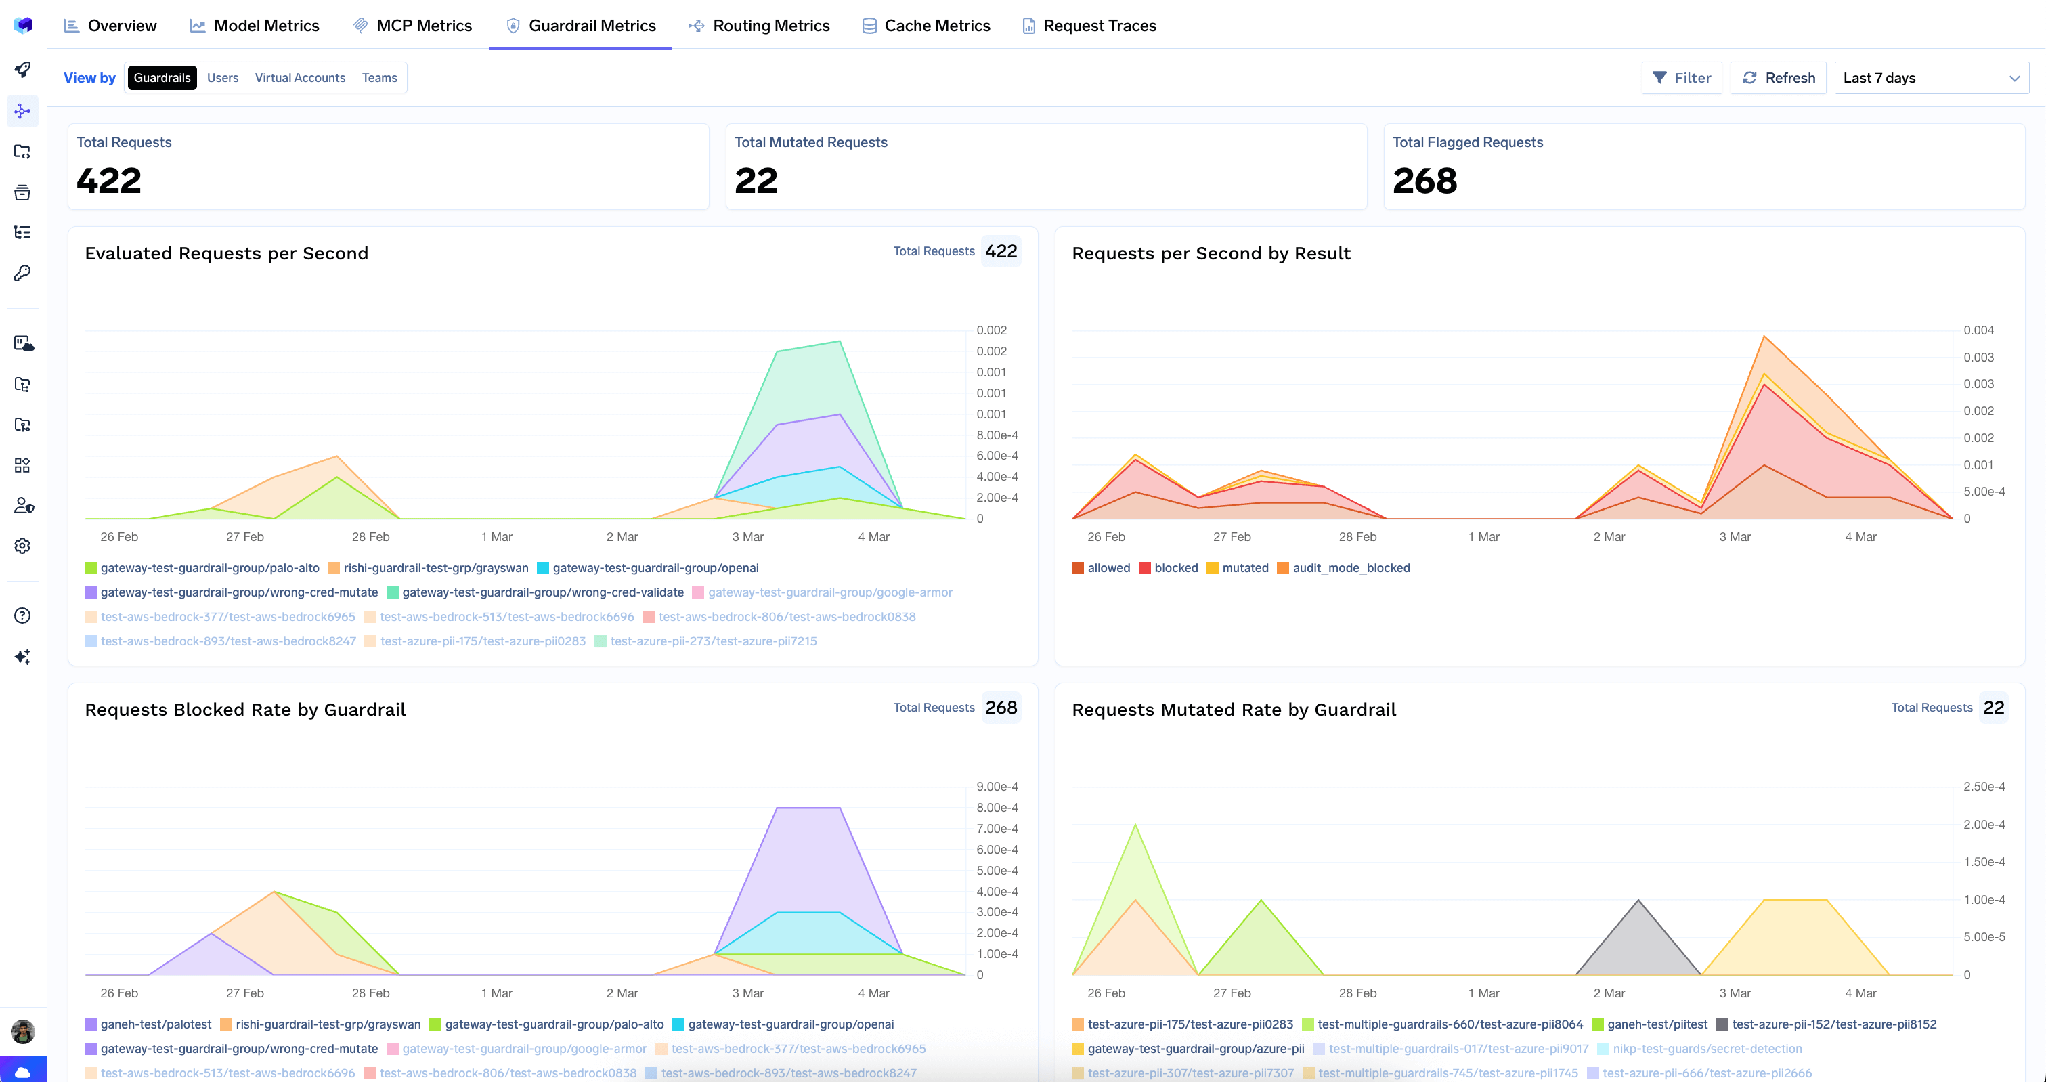
In aggregate, the Metrics Dashboard’s guardrail view splits requests per second across allowed, blocked, mutated and audit_mode_blocked, with block and mutate rates per guardrail and guardrail latency at P50, P75, P90 and P99. That last chart is how you catch a judge whose tail has become your tail.
A judge’s verdict is a claim about quality, and the only way to test it is against a human verdict on the same request. Every AI Gateway response carries an x-tfy-feedback-target-id header. Post it to POST https://{control_plane_url}/api/svc/v1/gateway-feedback with {"target": {"feedbackTargetId": "<base64>"}, "rating": 4, "comment": "...", "metadata": {...}} — rating runs 1 (lowest) to 5 (highest) — and you get back {"data": {"id": "..."}}. Corrections use PUT .../gateway-feedback/{feedback_id}, removals DELETE. Feedback shows next to the span, and the full list sits in Raw Data under tfyGatewayFeedbacks.
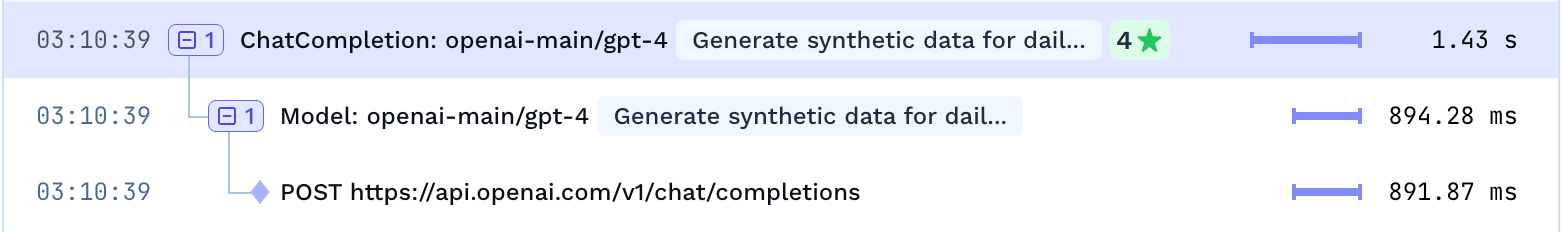
One limit: the target ID addresses the root span only. Feedback lands on the request, not a sub-step.
An internal assistant answers care-coordinator questions. Compliance wants two things: never harmful therapeutic guidance, and clinically appropriate tone. Neither is expressible as a regex, so this is judge territory.
1. Pick the narrowest rubric. Two Patronus judge criteria, not ten — patronus:no-harmful-therapeutic-guidance and patronus:clinically-inappropriate-tone, with target: response. The rest of compliance’s list goes to the cheap detectors.
2. Start in Audit. A policy rule under AI Gateway → Policies → Guardrails scopes it to the assistant’s models and the care-coordinator team, with enforcing strategy Audit: log the verdict, block nothing.
3. Read a week of traces. audit_mode_blocked tells you how many real requests this rule would have blocked; evaluation_metadata.highlighted_words tells you why. Typically the tone criterion is firing on good answers that happen to be terse.
4. Compare against humans. The assistant’s thumbs control is wired to the feedback API via x-tfy-feedback-target-id. If the flagged requests are the ones humans rated 1 or 2, the judge is earning its keep. If not, fix the rubric, not the threshold.
5. Promote, then watch the bill. Move to Enforce But Ignore On Error so a Patronus outage degrades to unguarded rather than to an outage of your own. Patronus reports usage_tokens per evaluation and judge inference routes through the gateway, so the cost of judging is visible rather than inferred — and that number decides your sampling rate.
Output guardrails are skipped on streaming responses. With "stream": true, output rails do not run; input rails always do. If your product streams, your judge guards the prompt and nothing else.
System prompts are never seen by guardrails. The gateway strips them before sending content to any guardrail, with CrowdStrike AIDR the single documented read-only exception. A judge cannot assess whether your instructions were followed.
Output validation still costs you the model call. An input rail failing mid-flight lets the gateway cancel the request. An output rail runs after the response exists, and the docs note model costs are already incurred by then.
LLM as a judge is a good technique with a narrow correct usage. It is the only way to grade subjective text at scale, and it is biased toward long answers, toward its own family’s output, and toward whichever candidate goes first. A team that believes only the first half ships a guardrail that quietly blocks its own users.
The split that makes it tractable is the one this post opened with. Offline scoring is a dataset problem that belongs on an eval platform, with TrueFoundry exporting traces there over OTEL. Online gating is a request-path problem: one tight criterion, a small pinned judge from a different family, audit mode first, precision over recall, and honest visibility into cost.
Write the rule as code where you can. Where you can only write it as a sentence, use a judge — and measure it like the model it is.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.




Using one language model to score another’s output against a written rubric, returning a machine-readable verdict — pass/fail, a score, or a preference between candidates. It exists because open-ended text has no computable correctness metric, and it is best treated as a cheap, noisy proxy for a human rater.
For narrow, binary, tightly worded criteria, often yes; for broad quality rubrics, usually not. Measure precision and recall separately on hand-labelled examples first — a judge that is 90% accurate blocks roughly one in ten legitimate answers the day you enforce it.
At least one extra model call per guarded request, and two if you judge both prompt and response — TrueFoundry’s NeMo docs state that arithmetic explicitly. The only lever is coverage: sample for telemetry, reserve full coverage for the checks that must never miss.
Yes. TrueFoundry runs in your VPC, on-prem, air-gapped, or hybrid, so prompts and responses never leave your domain even as you route across many providers.
Roughly 3-4 ms, sustaining 350+ RPS on a single vCPU across 1,000+ LLMs. Guardrail time is separate and reported at P50, P75, P90 and P99.
Yes. The gateway is OpenTelemetry-compliant and exports traces to external backends, which is how gateway data reaches platforms such as Braintrust, Langfuse or Arize. TrueFoundry does not itself run offline scoring jobs.



The latest news, articles, and resources sent to your inbox