September 29, 2026
|
5 min read

Published: September 29, 2026

Blazingly fast way to build, track and deploy your models!
Anyone comparing Langfuse vs LangSmith in 2026 needs to start with a fact that is only nine months old: ClickHouse acquired Langfuse, announced 16 January 2026, alongside ClickHouse’s $400M Series D led by Dragoneer. The deal value was not disclosed (ClickHouse announcement, 16 January 2026). Langfuse’s own post is blunt about the circumstances: “We didn’t plan to sell the company. Actually, we had Term Sheets for a great Series A” (Langfuse, joining ClickHouse).
The commitments are equally plain — “Langfuse stays open source and self-hostable. There are no planned changes to licensing.” As of September 2026 that holds up: the repo LICENSE now reads “Copyright (c) 2023-2026 ClickHouse, Inc.”, security contacts moved to security@clickhouse.com, and compliance policies live in the ClickHouse Trust Center. One substantive commercial change did land, and it is covered below.
LangSmith is independent and built by LangChain — the company behind LangChain and LangGraph. That single fact explains most of the differences that follow.
Langfuse describes itself as “an open-source AI engineering platform… tracing, prompt management, evaluation, and metrics.” The repository at github.com/langfuse/langfuse carries roughly 35,000 stars as of 25 September 2026.
It is genuine open core, and the boundary is documented rather than vague. Everything outside ee/, web/src/ee/ and worker/src/ee/ is MIT Expat; those directories carry a separate enterprise licence. Langfuse states that “all core Langfuse features and APIs are available in Langfuse OSS (MIT licensed) without any limits” and that “there are no scalability limitations between the different versions.”
The list gated behind LANGFUSE_EE_LICENSE_KEY is published: project-level RBAC roles, protected prompt labels, data retention policies, audit logs, server-side data masking, UI customisation, organisation creators, the Org Management API and SCIM, and the Instance Management API. Notably, Enterprise SSO and organisation-level RBAC are free in the self-hosted OSS build — more generous than Langfuse Cloud, where SSO costs $300/mo.
[SCREENSHOT: Langfuse — the trace detail view with nested observations, token counts and cost per span]
Self-hosting is real but not trivial. The stack is a Web container and a Worker container plus four stores: Postgres, ClickHouse, Redis/Valkey, and S3-compatible blob storage. Docker Compose is documented honestly as “single VM without high availability, scaling, or backups.” It can run fully offline and air-gapped, which matters in regulated environments. Self-reported scale: “90B+ observations per month… trusted by 21 of the Fortune 50.”
What Langfuse is genuinely better at. Licence freedom — MIT core, no scalability gating between OSS and Cloud. Framework neutrality — 100+ integrations across roughly 40 frameworks and 31 model providers, including nine competing gateways (LiteLLM, Portkey, OpenRouter, Kong, TrueFoundry). Data residency breadth — US (us-west-2), EU (eu-west-1) and JP (ap-northeast-1) regions plus a HIPAA-ready region, SOC 2 Type II, ISO 27001 and GDPR, with air-gapped self-host on top. Prompt management depth — versioning, release labels, composability, server- and client-side caching. And price at the low end.
LangSmith is LangChain’s observability, evaluation and agent deployment platform. The platform itself is not open source — only the SDK is, at github.com/langchain-ai/langsmith-sdk, MIT licensed with 1,062 stars as of 25 September 2026. Self-hosted and hybrid deployment are Enterprise-tier only.
That is a real constraint, and it is also the trade LangSmith is making: because it does not ship a self-hostable distribution to everyone, it ships more product.
[SCREENSHOT: LangSmith — a LangGraph run in the trace view, with the agent graph alongside the step timeline]
The pieces Langfuse does not have:
On tracing itself the two are close. LangSmith supports OpenTelemetry natively and maps GenAI semantic conventions plus TraceLoop, OpenInference and Logfire attributes, with Collector fan-out. Its framework list covers AutoGen, Claude Agent SDK, CrewAI, Google ADK, Mastra, Microsoft Agent Framework, OpenAI Agents SDK, PydanticAI, Semantic Kernel, Strands and the Vercel AI SDK. It is not LangChain-only, whatever the branding suggests.
What LangSmith is genuinely better at. LangChain and LangGraph depth, because it is first-party. Being more than observability — deployment, sandboxes and a gateway are three categories Langfuse does not enter. Autonomous failure triage via Engine. A 400-day extended-trace retention ceiling. And operational simplicity: nothing to self-host, no ClickHouse cluster to run.
Both publish list prices. Comparing them directly is a trap, because the billable units differ by roughly an order of magnitude.
Langfuse Cloud (read 25 September 2026):
Volume discounts run to $7/100k (1-10M units), $6.50 (10-50M) and $6 (50M+).
The unit definition decides your bill: “Units = Count of Traces + Count of Observations + Count of Scores.” Langfuse’s own worked example is 20,070 traces + 119,500 observations + 561 scores = 140,131 units per month — roughly seven billable units per trace. The docs also answer the obvious follow-up: “Do units created by Langfuse features count toward billable units? Yes.” That includes LLM-as-a-judge, annotation queues and experiments. Running more evals costs more money.
LangSmith (read 25 September 2026):
A LangSmith trace is “a single execution of your application… It can include many individual steps.” A base trace carries 14-day retention; an extended trace carries 400-day retention “for an additional fee.”
Two things to flag. First, LangSmith does not publish a per-trace overage rate — the page says only “pay as you go thereafter.” Second, the rest of the platform meters in abstract units: 1 LCU (LangChain Compute Unit) = $1.50 and 1 LSU (LangChain Storage Unit) = $1.00. Engine consumes ~5-30 LCUs per run — $7.50-$45 per run, on a 6-hour default schedule. Tuned Evaluators bill 0.01 LCU per run ($0.015). Deployment meters separately again: runtime compute 0.045 LCU/vCPU-hr, runtime memory 0.006 LCU/GiB-hr, database compute 0.177 LSU/vCPU-hr, database memory 0.025 LSU/GiB-hr. Startups can apply for up to $10,000 in credits.
The comparison that matters. One agent run containing 20 LLM calls is 1 LangSmith base trace and roughly 21+ Langfuse units. At Langfuse’s $8/100k that is about $0.0017 per run; LangSmith’s equivalent rate is unpublished. Do not compare $29 to $39 — model your own trace shape first.
One correction, because the opposite is widely repeated and now out of date: Langfuse does ship an LLM gateway. It is a standalone Rust service under ai-gateway/ exposing “native provider APIs under two namespaces: /openai/v1 … /anthropic/v1.” Read the design note before planning around it — “the gateway forwards inference to official provider paths only. It does not retry, follow redirects, or accept client routing overrides.” No load balancing, no failover, no semantic caching, no budget enforcement. It is a two-provider capture relay so traces arrive without SDK instrumentation — not a router, and Langfuse does not claim otherwise.
1. Unit inflation nobody modelled. Langfuse’s ~7-units-per-trace ratio is fine until an agent framework emits 40 observations per run. Then a $29 plan with 100k units covers about 2,500 runs a month. Teams discover this after the first overage invoice, not before.
2. Evals bill twice. On Langfuse, LLM-as-a-judge scores are billable units and cost judge-model tokens. On LangSmith, Engine runs every 6 hours by default at $7.50-$45 a run — roughly $900-$5,400 a month if you never touch the setting. Both are documented. Both surprise people.
3. The self-hosted enterprise path changed after the acquisition. Langfuse’s self-host pricing page now states that supported self-hosted Enterprise is “bundled with ClickHouse Cloud, ClickHouse BYOC, or ClickHouse Private,” and that “Langfuse pricing is additive to your ClickHouse commercial plan.” The MIT build is untouched. But vendor-supported self-hosting is now tied to a ClickHouse contract — the most substantive change the acquisition has produced as of September 2026.
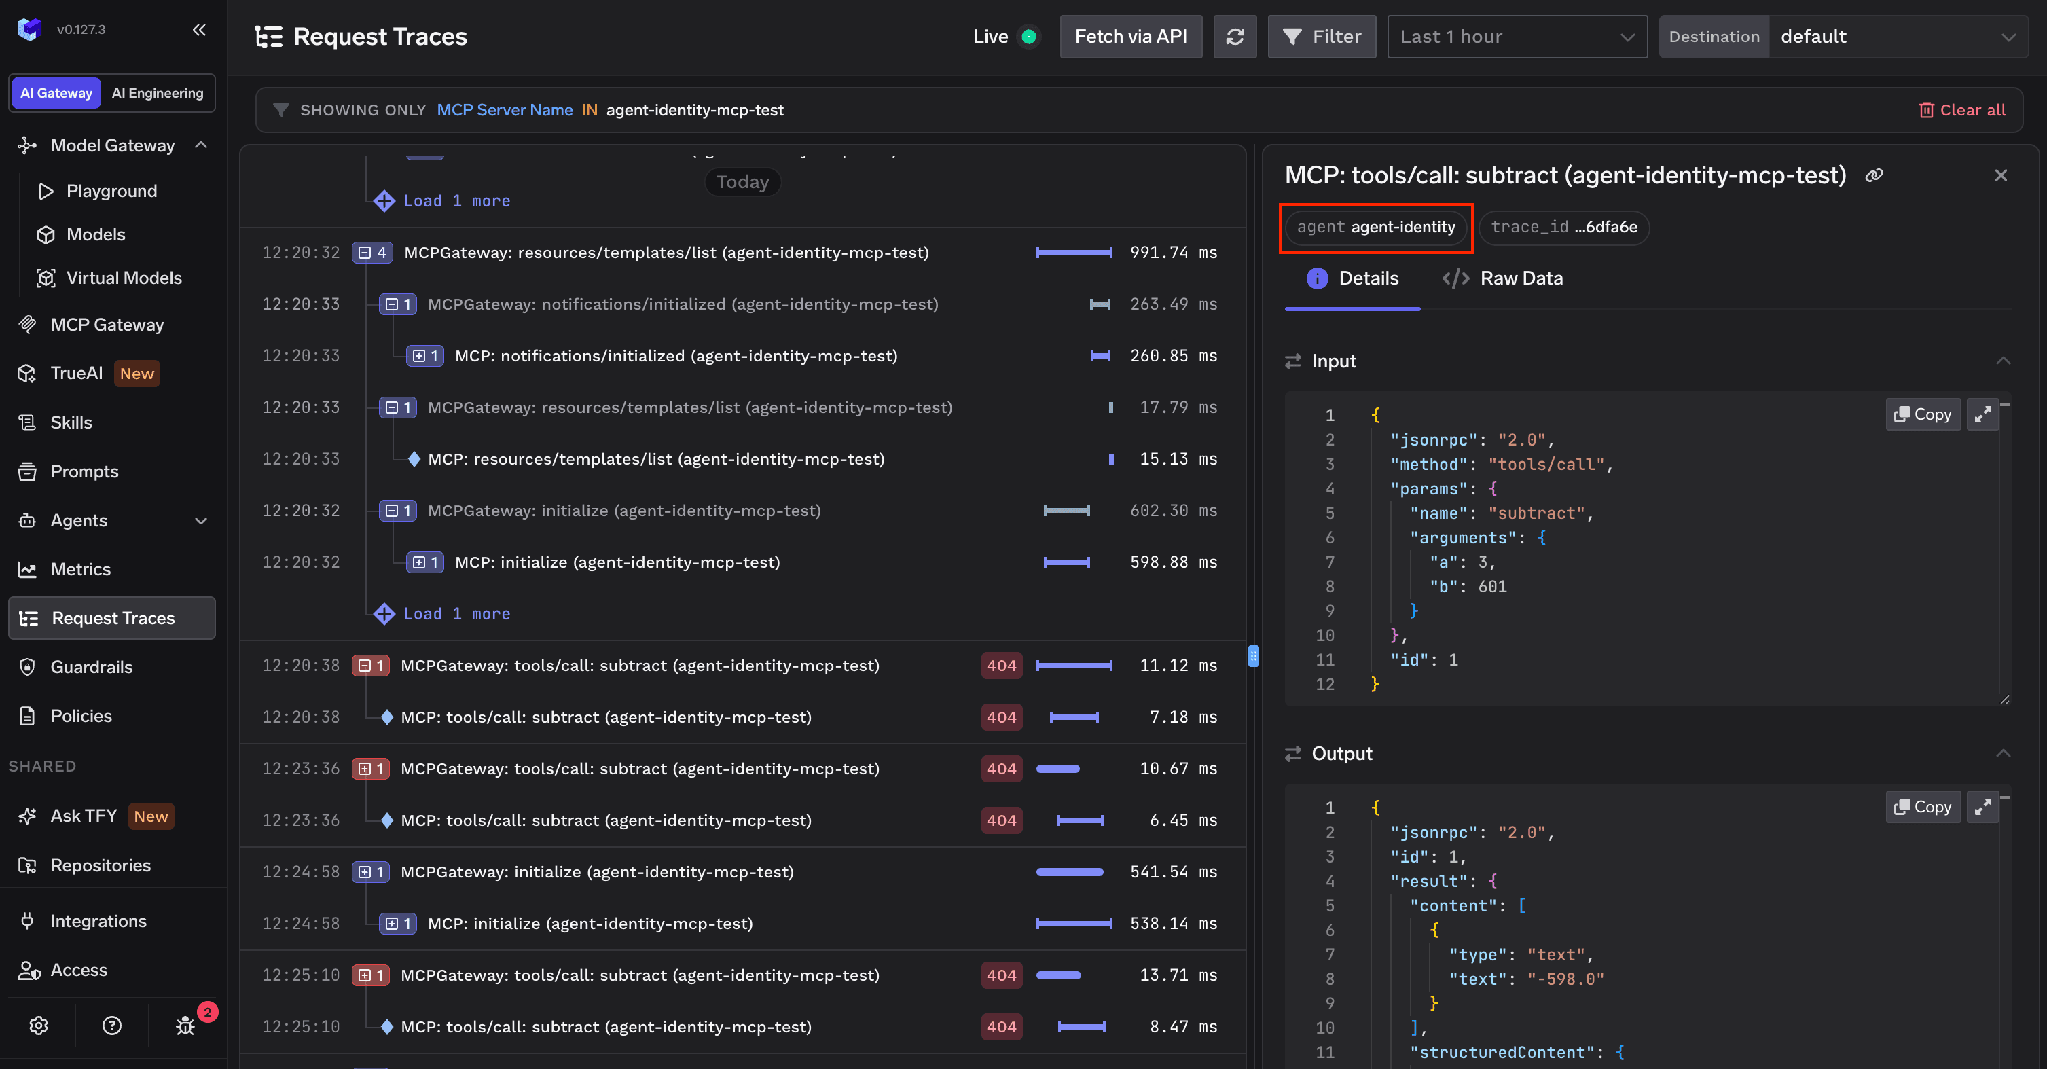
4. Observability is not control. A trace tells you a request cost $0.42 and took 9 seconds — after it happened. It does not stop the request, cap the team’s spend, block the prompt injection, or fail over when the provider returns 503. Tracing is the wrong layer for enforcement, and both vendors would agree.
To be direct: TrueFoundry does not replace Langfuse or LangSmith. They are the observability and evaluation layer. TrueFoundry’s AI Gateway is the control point in front of the models, and exports traces to either over OpenTelemetry. Langfuse already lists TrueFoundry among the nine gateways it integrates with — the clearest signal these are complementary layers, not competing ones.
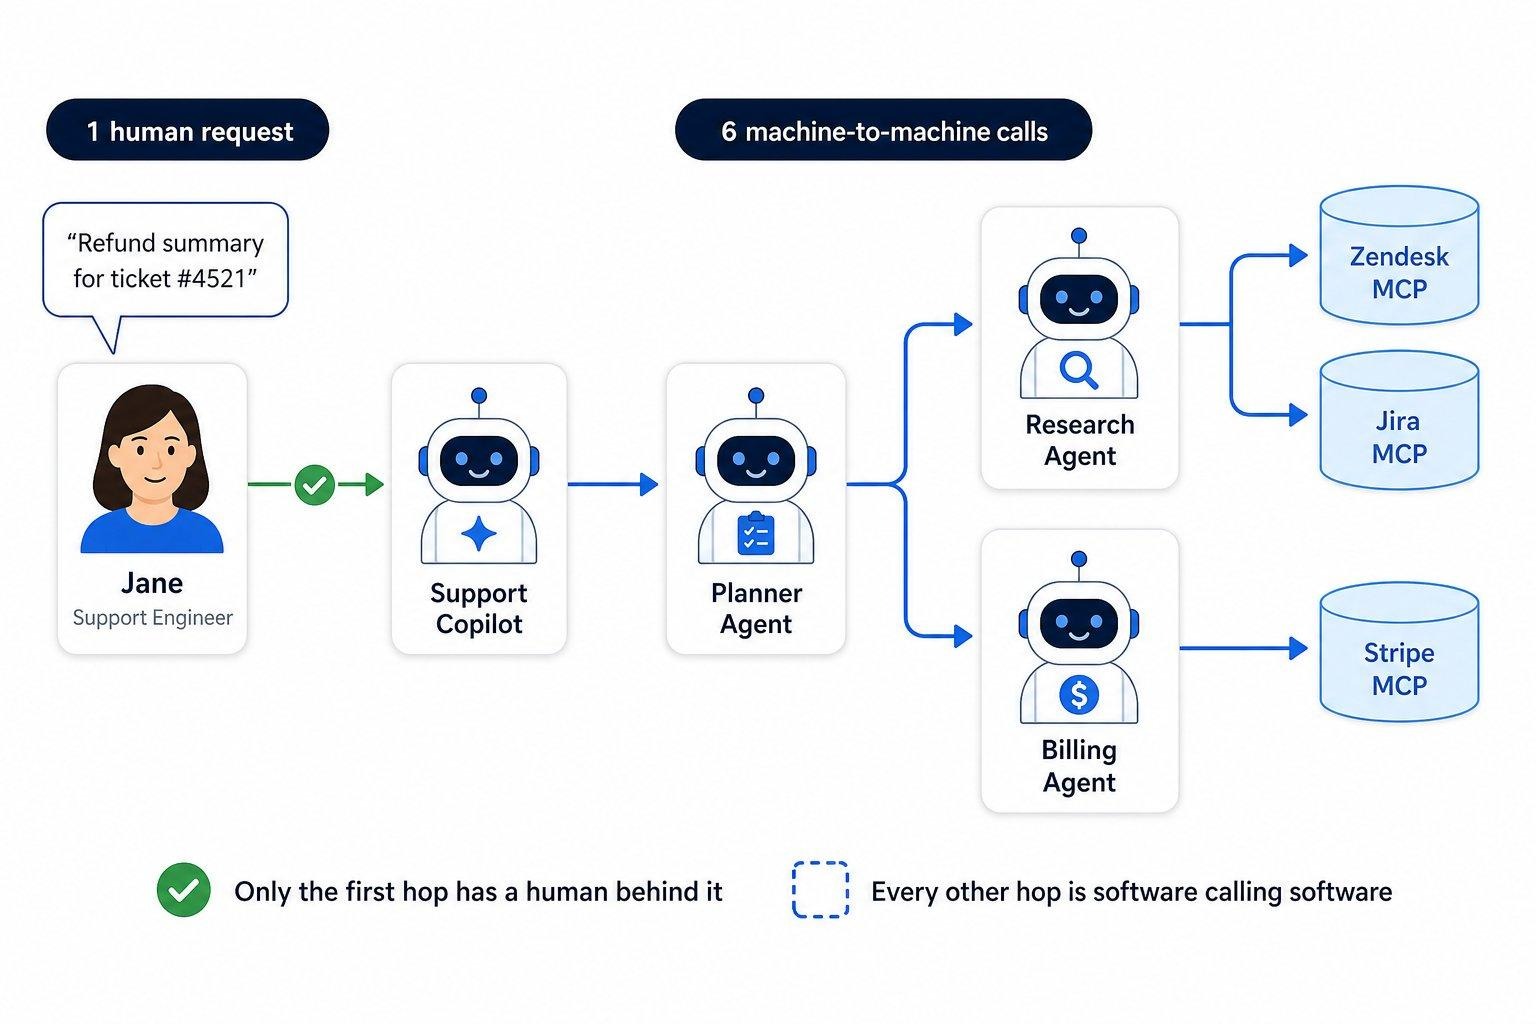
The gateway fronts 1,000+ LLMs behind one OpenAI-compatible API, adds roughly 3-4 ms of latency, and handles 350+ RPS on 1 vCPU. Those numbers make it practical to put in front of every call rather than only the important ones. Budgets, rate limits, guardrails, cost attribution and fallback all become enforceable at that single point.
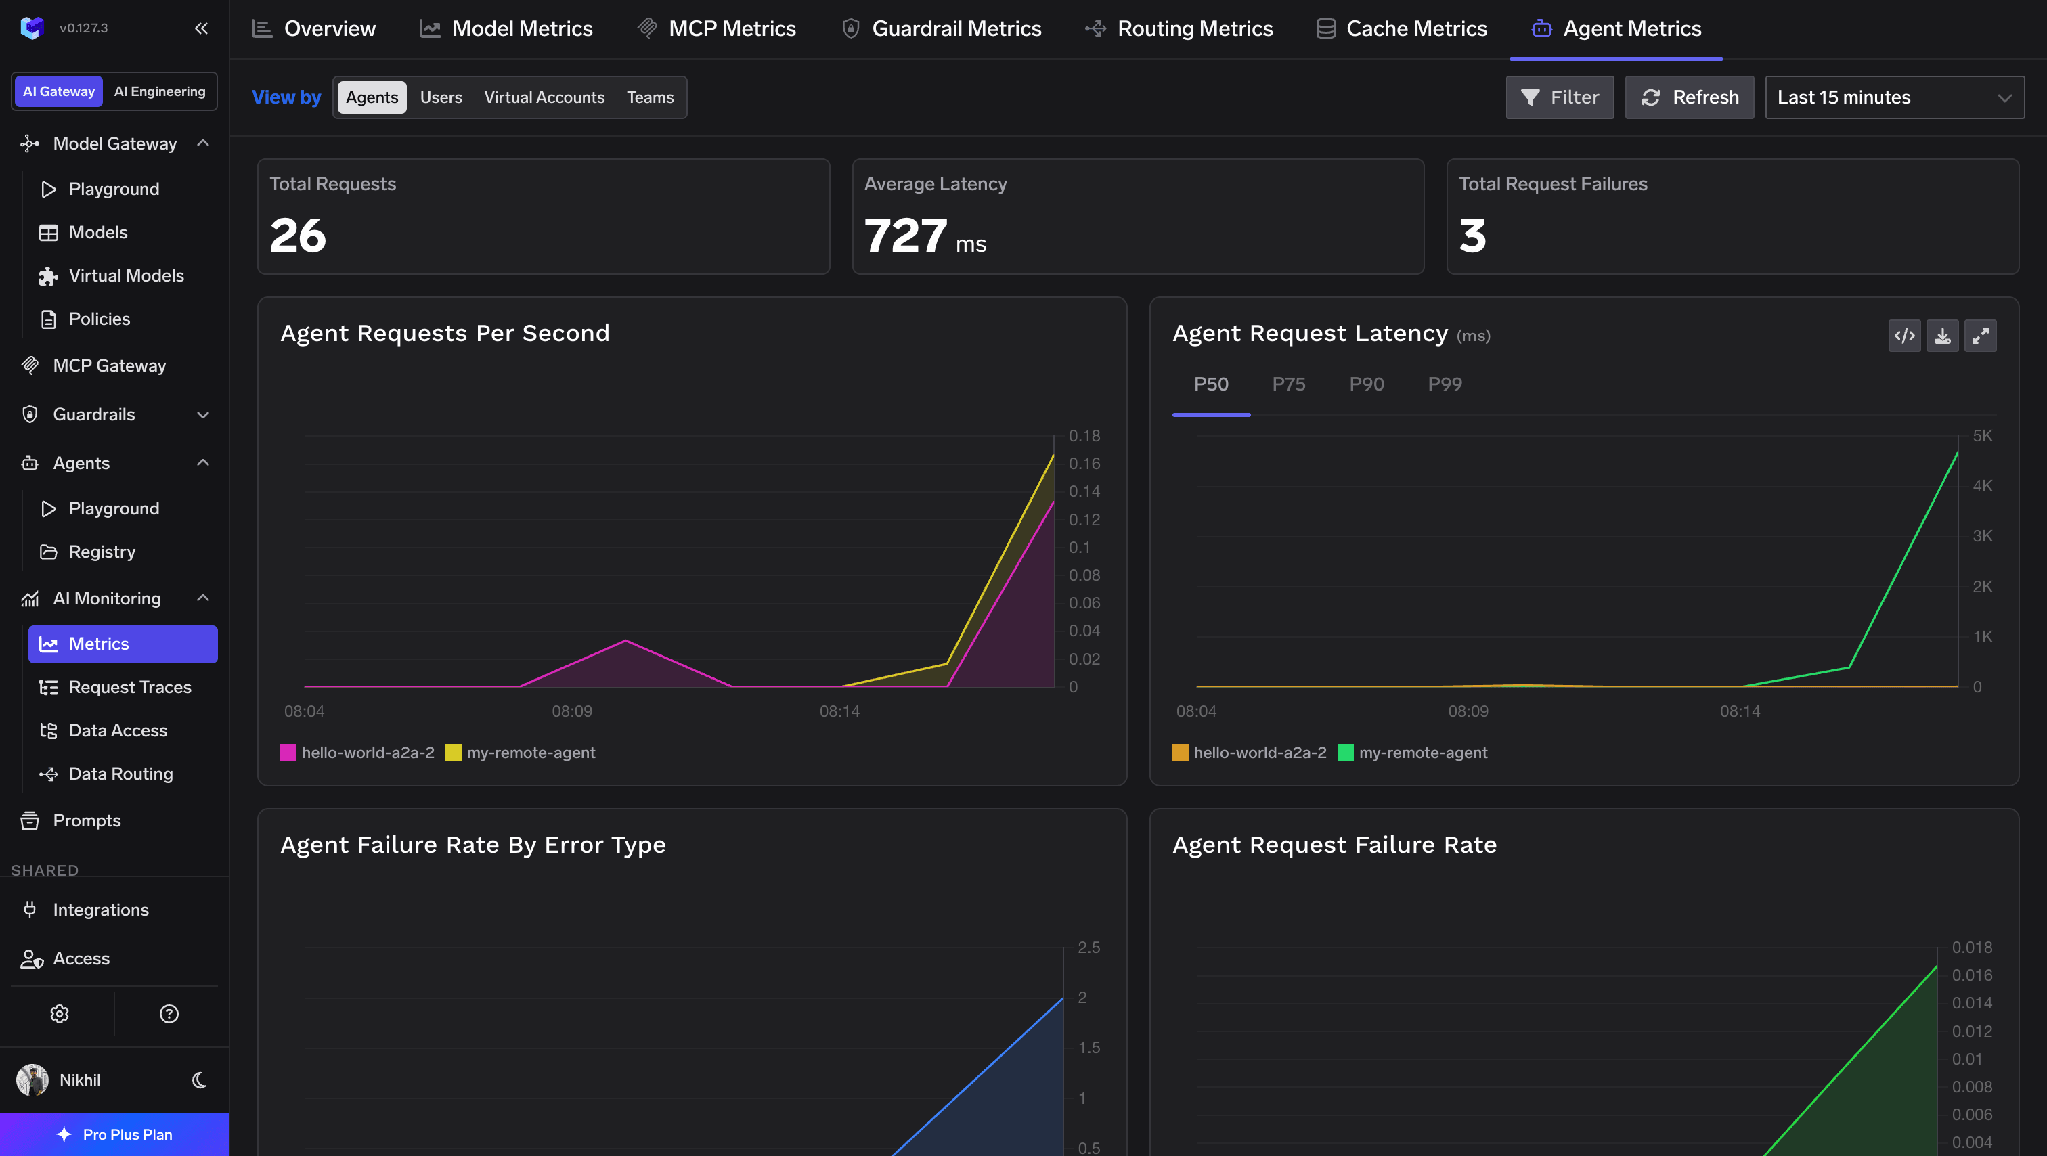
The split most teams land on: enforce policy and attribute cost at the gateway, then send traces to whichever platform your engineers prefer for debugging and evaluation. If that is LangSmith, the integration is documented. If it is Langfuse, the OTLP endpoint works the same way. You are not choosing between governance and observability.
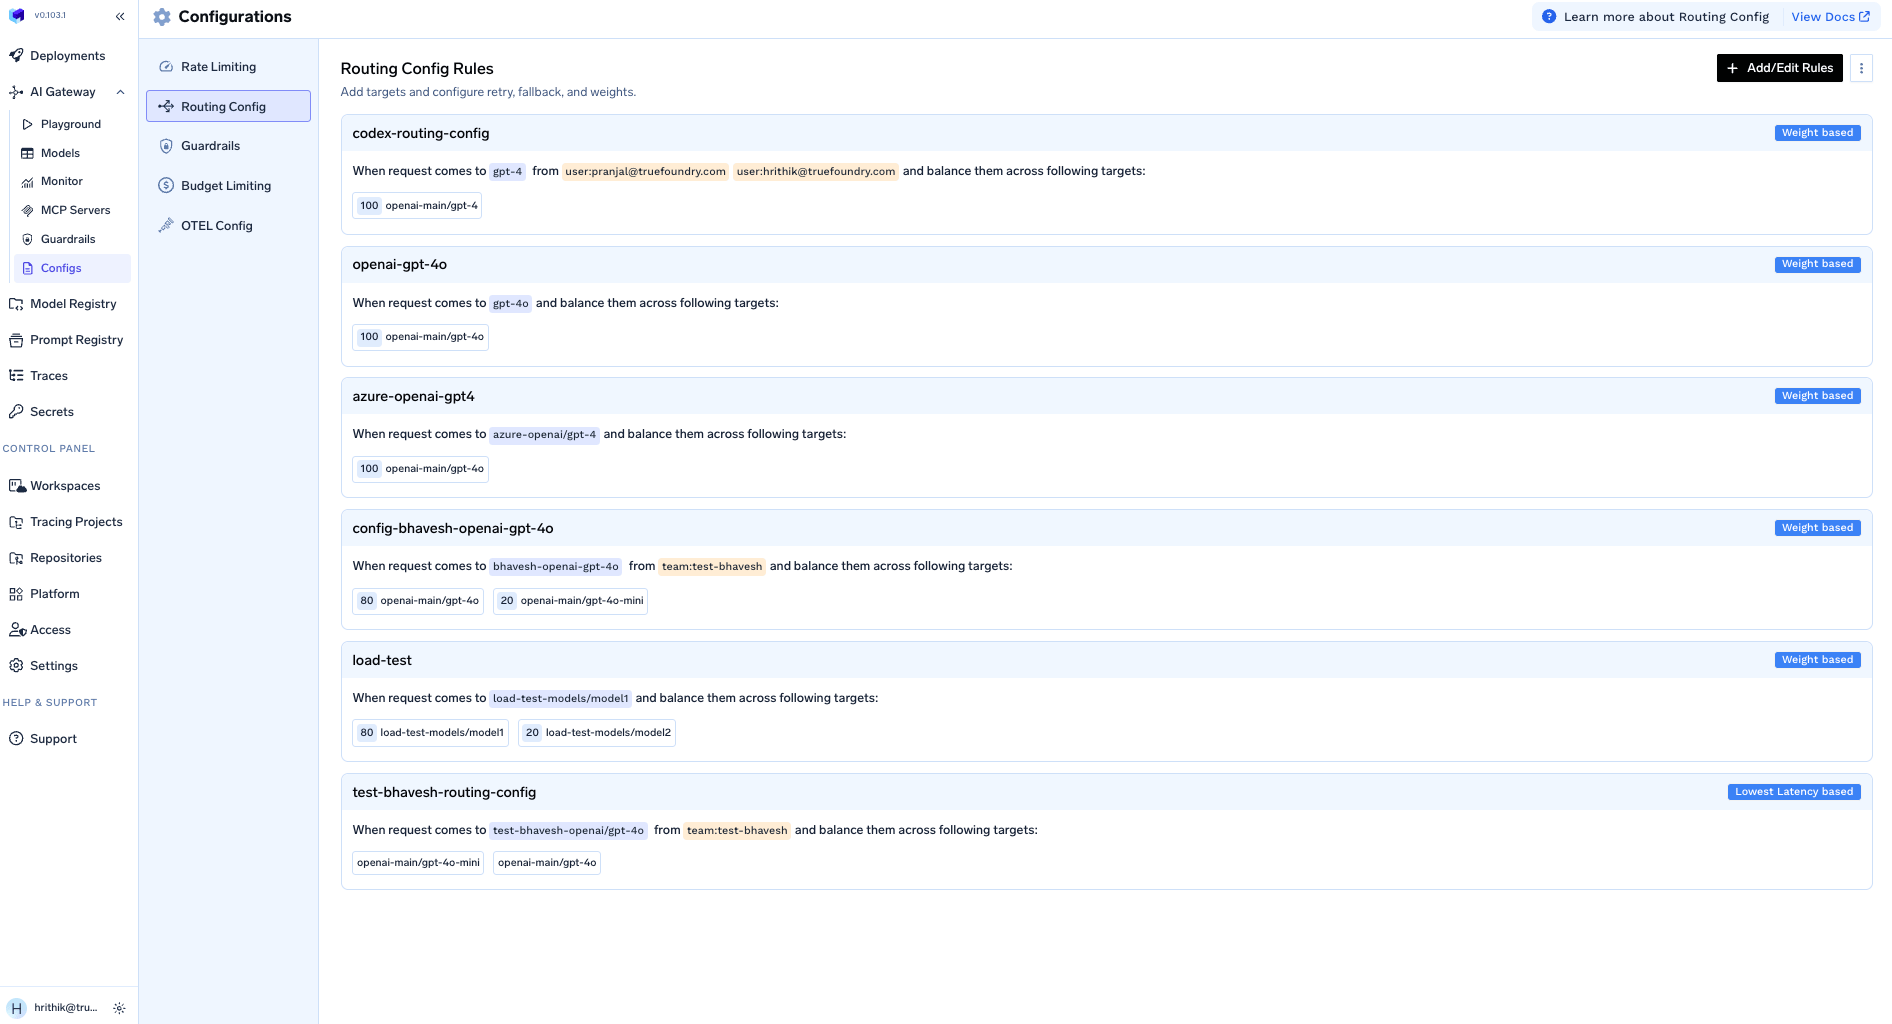
Routing config is the other lever, and it sits upstream of the observability bill: send each request to the right model tier instead of defaulting to the frontier model, and you cut both inference spend and the volume of expensive traces you are paying to store.
Both are good, at different things. Langfuse bet on openness: MIT core, self-host anywhere including air-gapped, three cloud regions, and a deliberate refusal to tie itself to one agent framework. That bet survived the ClickHouse acquisition intact, with one commercial caveat around supported self-hosting. LangSmith bet on depth within an ecosystem it owns, and shipped three categories — deployment, sandboxes, a real gateway — that Langfuse has not entered.
So it comes down to what you want to own. Want the code and the deployment? Langfuse. Want the most product with the least operational surface, on a LangChain stack? LangSmith. Model your actual trace volume either way; the headline prices will mislead you.
What neither is built to do is enforce anything. Both watch what already happened. If you also need one governed entry point in front of every model call — budgets, rate limits, guardrails, cost attribution, failover — that layer sits upstream, and it exports to whichever of these two you chose.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.




Choose Langfuse if you need to self-host, want an MIT-licensed core, care about data residency beyond the US and EU, or want unlimited users at a low flat price. Choose LangSmith if your stack is LangChain or LangGraph, or you want agent deployment, sandboxes and Engine’s failure triage alongside tracing. The deciding question is usually deployment: Langfuse self-hosts on any tier; LangSmith self-hosting requires Enterprise.
Yes, as of September 2026. The acquisition was announced 16 January 2026 and Langfuse stated “there are no planned changes to licensing.” The MIT core is unchanged. The change that did land is commercial: supported self-hosted Enterprise is now bundled with a ClickHouse plan, and Langfuse pricing is additive to it.
It depends on your trace shape, and neither headline price answers it. Langfuse bills traces plus observations plus scores — roughly seven units per trace in their own example — at $8 per 100k units over the allowance. LangSmith bills whole traces but publishes no per-trace overage rate, and meters everything else in LCUs at $1.50 and LSUs at $1.00.
It ships one, but it is narrow by design. The Rust ai-gateway/ service relays /openai/v1 and /anthropic/v1 so traces are captured without SDK changes, and the docs state it “does not retry, follow redirects, or accept client routing overrides.” No load balancing, failover, caching or budgets. LangSmith’s is the fuller of the two.
Yes. Both are OTEL-native, so the gateway exports traces to either endpoint, and Langfuse lists TrueFoundry among its gateway integrations. You govern and attribute cost at the gateway; you debug and evaluate in the observability platform.
If you are one developer prototyping, no. Once several teams share provider keys you need budgets, rate limits, per-team attribution and a kill switch — none of which live in a tracing product.