


October 16, 2026
|
Lesedauer: 5 Minuten


Erhalten Sie sofortigen Zugriff auf eine TrueFoundry-Live-Umgebung. Stellen Sie Modelle bereit, leiten Sie den LLM-Verkehr weiter und erkunden Sie die gesamte Plattform — Ihre Sandbox ist in Sekundenschnelle einsatzbereit, ohne dass eine Kreditkarte erforderlich ist.


Published: October 16, 2026
Unglaublich schnelle Methode zum Erstellen, Verfolgen und Bereitstellen Ihrer Modelle!
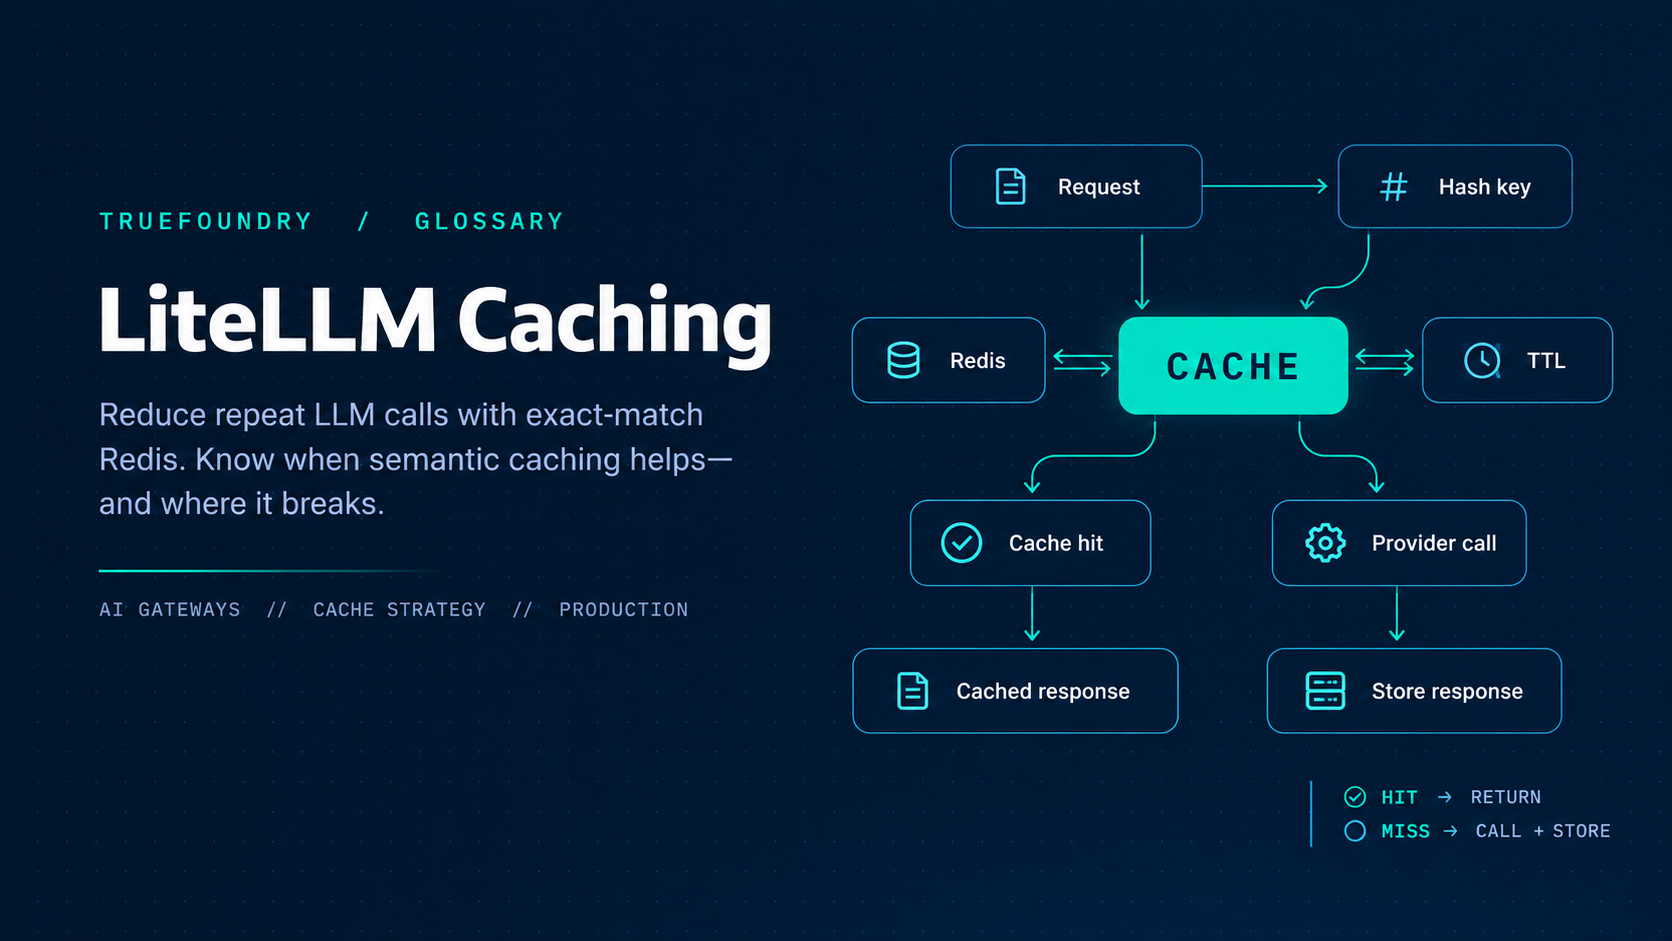
A LiteLLM cache stores LLM responses so a later identical (or, for semantic mode, similar) request can skip the provider call. That cuts latency and provider spend when traffic is repetitive—and creates correctness bugs when it is not. This article covers exact-match caches (in-memory, Redis/Valkey, S3/GCS, disk), semantic caches (Redis, Valkey, Qdrant), TTL and keys, multi-replica requirements, invalidation, and the failure modes platform engineers hit in production. Scope note: this is LiteLLM’s application-level response cache, not OpenAI/Anthropic provider-side prompt caching (a separate feature with its own configuration). Caching is one of several controls an LLM gateway applies on the request path, alongside auth, rate limits, and routing.
Official proxy caching docs list: redis (also Valkey/ElastiCache/Memorystore via Redis protocol), redis-semantic, valkey-semantic, qdrant-semantic, s3, gcs, local (in-memory), and disk. Redis is the right default past a single worker. Exact-match caches key on a hash of the whole request. Semantic caches embed the prompt and serve the closest match above a similarity threshold—suited to single-shot prompts and a poor fit for agentic traffic.
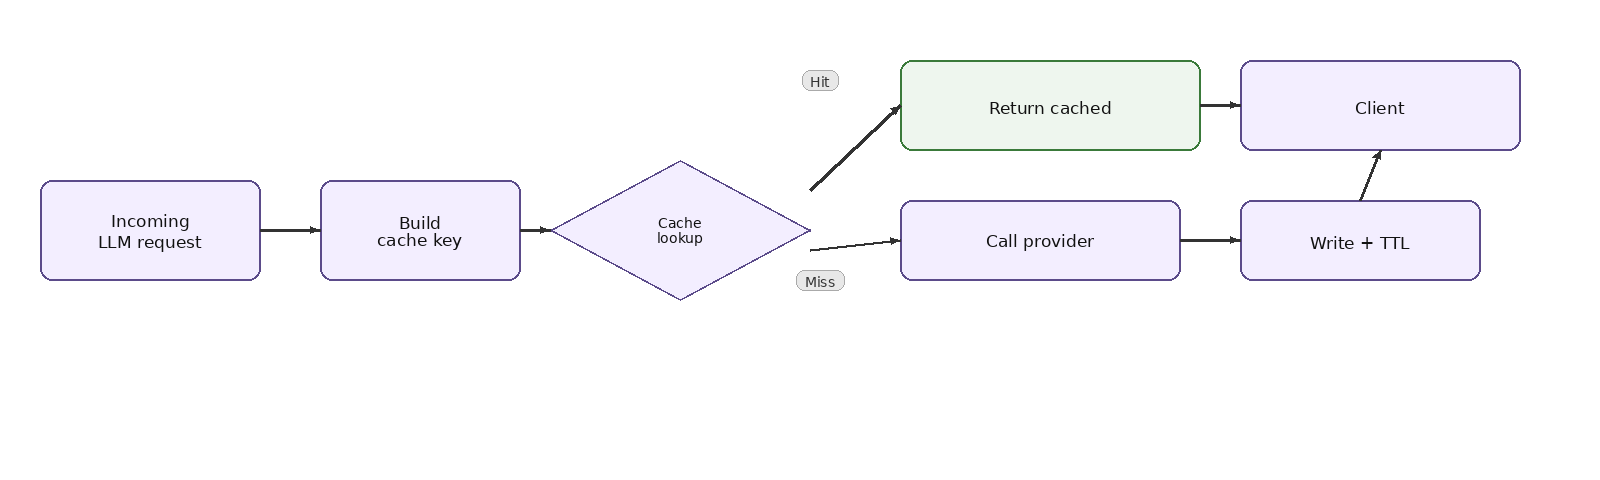
Figure 1. Exact-match flow: hash the request, lookup, hit return or miss → provider → store.
On a hit, responses can carry an x-litellm-cache-key header useful for debugging and for /cache/delete. With cache: True and no supported_call_types override, caching applies to /chat/completions, /completions, /embeddings, /audio/transcriptions, /rerank, /v1/responses, and /v1/messages (confirm on your version). On /v1/responses, exact-match keys on the request body—so previous_response_id versus an inlined conversation are different keys, and each multi-turn step is its own entry.
TrueFoundry AI Gateway bietet eine Latenz von ~3—4 ms, verarbeitet mehr als 350 RPS auf einer vCPU, skaliert problemlos horizontal und ist produktionsbereit, während LiteLM unter einer hohen Latenz leidet, mit moderaten RPS zu kämpfen hat, keine integrierte Skalierung hat und sich am besten für leichte Workloads oder Prototyp-Workloads eignet.




LiteLLM cache is the response cache built into the LiteLLM proxy and SDK: it stores LLM responses so a later identical request—or a similar one in semantic mode—skips the provider call. You enable it with litellm_settings.cache: true and choose a backend in cache_params (local, disk, redis, s3, gcs, or a semantic backend). It cuts latency and provider spend on repetitive traffic, and it is separate from provider-side prompt caching.
Use the in-memory (local) or disk cache only for local development or a single process, because neither is shared between workers or replicas. Use Redis—or a Redis-protocol service such as Valkey, ElastiCache, or Memorystore—as soon as you run more than one worker or pod. Four workers with local caches behave like four separate caches, and hit rates drop roughly by the worker count.
Semantic cache is designed for single-shot prompts; on multi-turn traffic it replays stale responses. Each new turn is the previous conversation plus a small delta, so embeddings stay around 0.99 similar, and assistant tool_calls are not part of the embedded text—agents end up repeating the same tool call. Raising similarity_threshold does not reliably fix it; exclude agent keys with "cache": {"no-cache": true} metadata or use exact-match type: redis.
Yes. The gateway is OpenTelemetry-compliant and plugs into Grafana, Datadog, Prometheus, or your preferred stack. Every request is traced from prompt to model execution, so metrics such as latency, cost, and errors land next to your existing dashboards.



Die neuesten Nachrichten, Artikel und Ressourcen werden in Ihren Posteingang gesendet

















