October 16, 2026
|
5 min de lecture


Accédez instantanément à un environnement TrueFoundry en direct. Déployez des modèles, acheminez le trafic LLM et explorez la plateforme complète : votre sandbox est prête en quelques secondes, aucune carte de crédit n'est requise.



Published: October 16, 2026
Une méthode incroyablement rapide pour créer, suivre et déployer vos modèles !
Nobody means to send a credential to a model provider. It happens anyway, because prompts are assembled from messy, real-world text:
A developer debugging an integration pastes a config snippet — with a live API key in it — and asks the model to find the bug. A coding agent, told to “fix the failing test,” reads the repo’s .env file into its context. A RAG pipeline retrieves a document that happens to contain a database connection string. An agent calls a tool that returns an object with an embedded OAuth token, and that result goes straight back into the model’s context.
In every case the secret has now been transmitted to a third-party provider, logged somewhere, and possibly used in training or retained. The developer did nothing obviously wrong; the system had no checkpoint. That checkpoint is what a secrets-detection guardrail provides — and the right place for it is the gateway every call already passes through.
Credentials come in recognizable shapes, and a good detector knows the patterns.
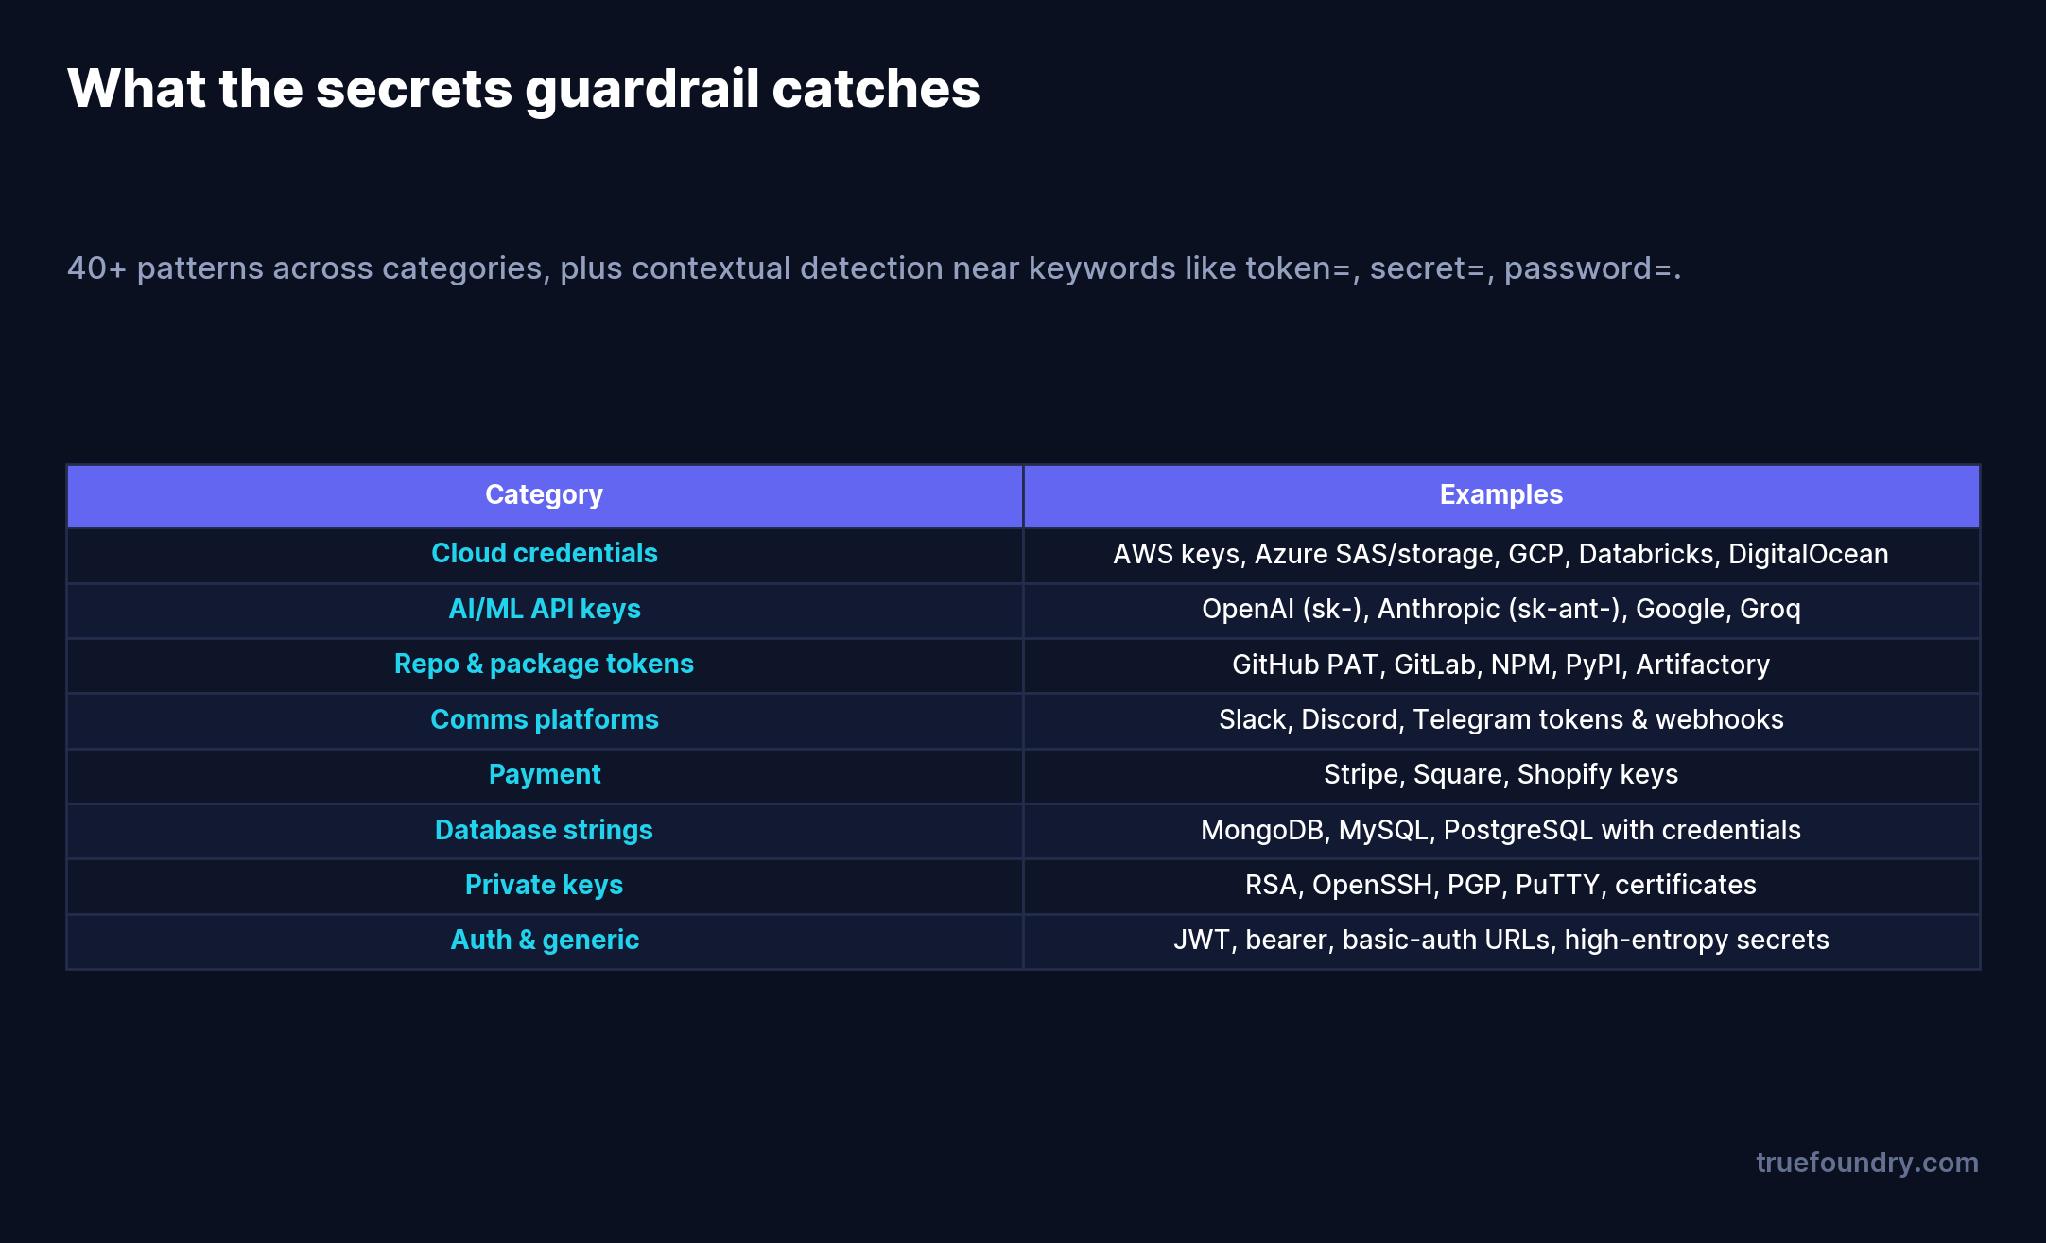
TrueFoundry’s built-in Secrets Detection guardrail recognizes 40-plus credential patterns across cloud providers (AWS, Azure, GCP), AI/ML API keys (OpenAI’s sk-, Anthropic’s sk-ant-), repository and package tokens (GitHub, GitLab, NPM, PyPI), communication platforms (Slack, Discord, Telegram), payment keys (Stripe, Square, Shopify), database connection strings, and private keys and certificates (RSA, OpenSSH, PGP). Beyond fixed patterns, it does contextual detection — flagging high-entropy hex or base64 strings that appear near keywords like token=, secret=, or password=, which catches credentials that don’t follow a standard format.
Because it runs inside the gateway rather than calling an external service, detection is fast and adds no extra per-request cost.
A secret can enter the conversation from three directions — the user, the model, or a tool — so the guardrail runs at four points.
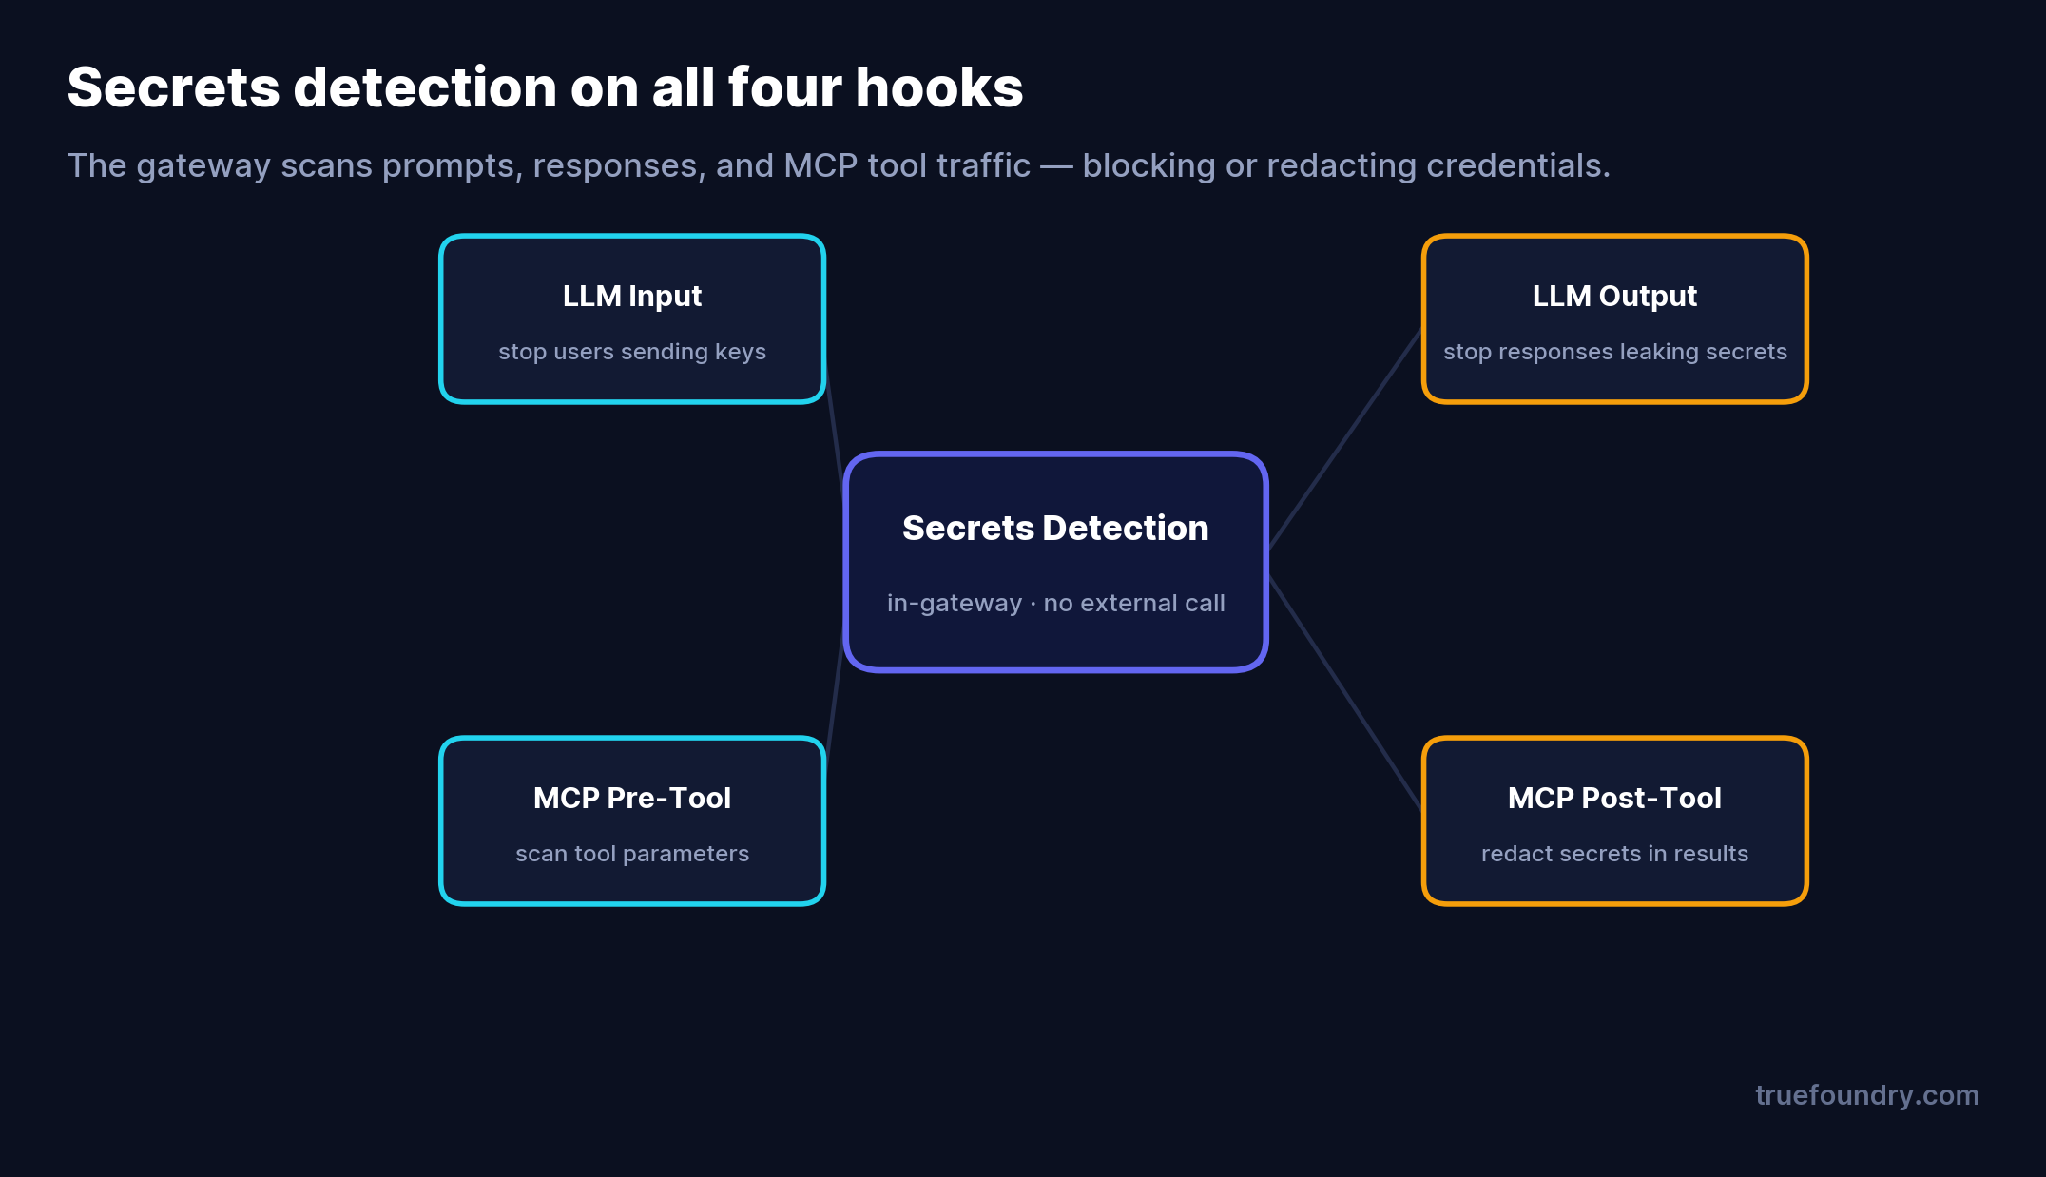
LLM Input stops a user or app from sending credentials to the model in the first place. LLM Output catches a model that generates or echoes a secret (for example, producing a sample config with a real-looking key). MCP Pre-Tool scans tool parameters before a tool runs, and MCP Post-Tool redacts secrets in tool results — the file contents and API responses an agent pulls back into its context. For agentic systems, the MCP hooks matter as much as the LLM ones, because the agent is reading files and calling APIs on its own.
You choose what happens when a secret is found.
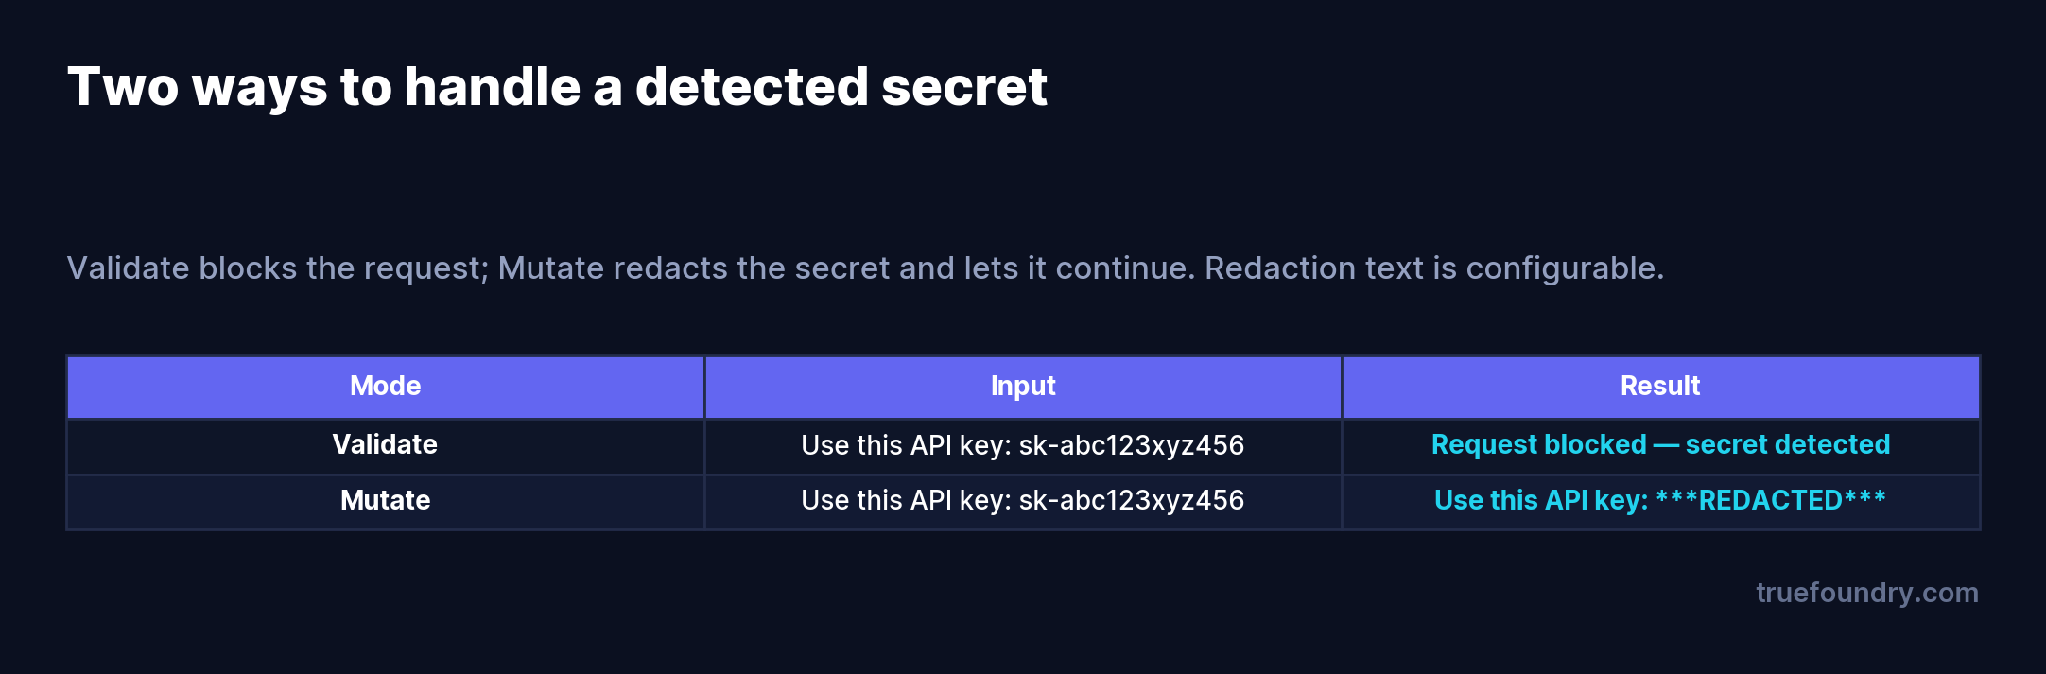
Validate mode blocks the request outright when a secret is detected — the right choice when a credential in the content is a hard policy violation. Mutate mode redacts the secret, replacing it with configurable text (***REDACTED*** by default) and letting the request continue — useful when you want the agent to keep working on the non-sensitive part of the content, and when you want clean text in your logs. Many teams run Mutate on input (so work continues with the secret stripped) and consider Validate where a leak must hard-stop.
They only guard user input. Secrets leak from model output and tool results too. Guard all four hooks, not just the prompt.
They forget output guardrails skip streaming. With stream: true, output scanning doesn’t run — there’s no complete response to check. Use stream: false where output redaction matters.
They rely on developers to be careful. “Don’t paste secrets” is not a control. The whole point of a gateway guardrail is that it doesn’t depend on anyone remembering.
They don’t tune for false positives. High-entropy strings like UUIDs or encoded blobs can trip detection. Test against your real traffic and adjust before enforcing hard blocks.
It’s a built-in guardrail, so there are no external keys to configure. In the AI Gateway, open Guardrails, create or pick a group, and add the Secrets Detection guardrail.
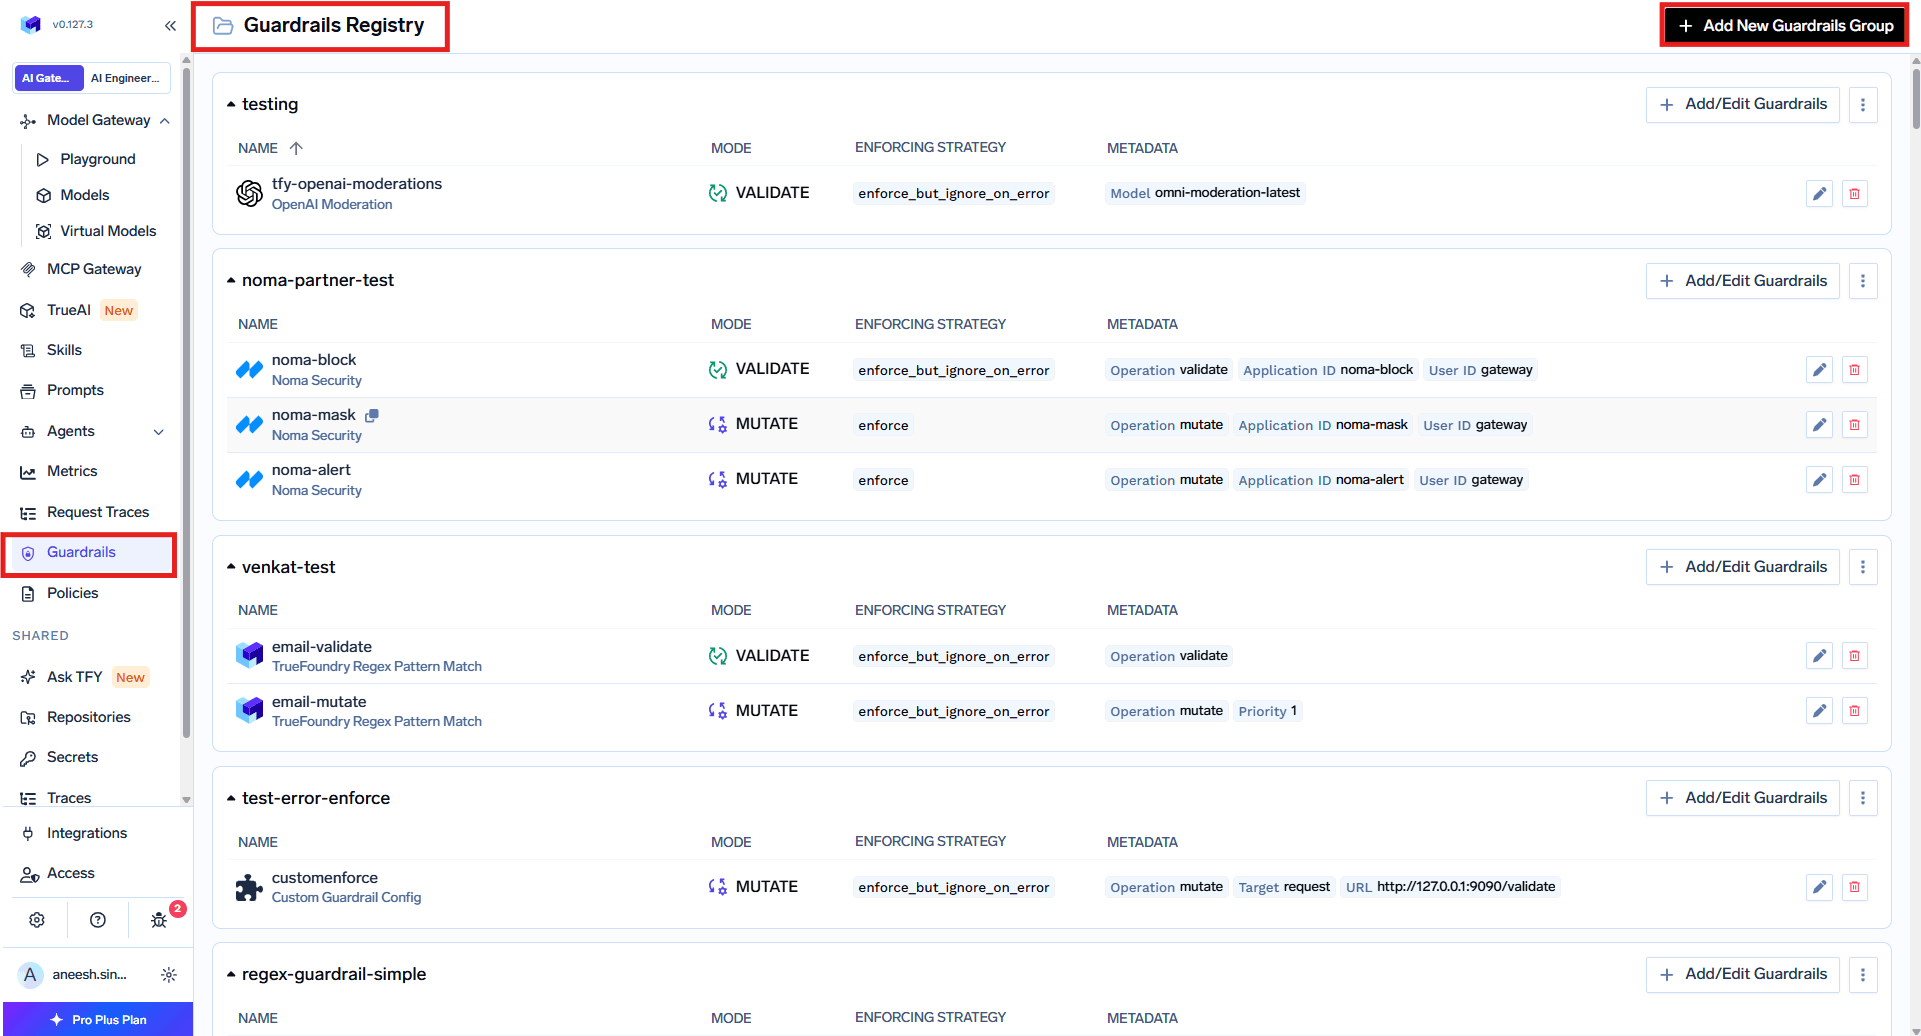
Configure the name, the operation (validate or mutate), the enforcing strategy, and — for mutate — the redaction text. Then apply it per request with the X-TFY-GUARDRAILS header:
{
  "llm_input_guardrails": ["my-group/secrets-detection"],
  "llm_output_guardrails": ["my-group/secrets-detection"]
}
Or enforce it org-wide, including on MCP tools, with a gateway policy:
name: guardrails-control
type: gateway-guardrails-config
rules:
  - id: mcp-secrets-protection
    when:
      target:
        conditions:
          mcpServers: {values: [file-reader], condition: in}
      subjects:
        conditions:
          in: [team:engineering]
    mcp_tool_post_invoke_guardrails:
      - my-group/secrets-detection
For maximum coverage, attach it to all four hooks — input, output, pre-tool, and post-tool.
An engineering team runs a coding agent that can read repository files through an MCP file tool. A developer asks it to “fix the failing database test.” The agent reads config/.env to understand the connection — and that file contains postgresql://admin:S3cr3tP@ss@db.prod:5432/app.
Without a guardrail, that connection string goes into the model’s context and out to the provider. With Secrets Detection on the MCP Post-Tool hook in Mutate mode, the tool result comes back as postgresql://admin:***REDACTED***@db.prod:5432/app before the model ever sees it. The agent still gets the structure it needs to reason about the test; the live credential never leaves the environment. Add the LLM Input hook and the same protection covers the developer pasting the string directly into chat.
Secrets get into prompts the same way they get into logs — not through malice, but through ordinary work hitting a system with no checkpoint. A coding agent reading a config file, a developer pasting a stack trace, a tool returning a token: each is a credential one hop from a third-party provider.
A secrets-detection guardrail at the gateway is that checkpoint. It scans every hook, recognizes the credentials that matter, and either blocks or redacts them before they leave your perimeter — fast, in-gateway, and not dependent on anyone remembering the rule. It’s one of the cheapest, highest-leverage guardrails you can turn on.
TrueFoundry AI Gateway offre une latence d'environ 3 à 4 ms, gère plus de 350 RPS sur 1 processeur virtuel, évolue horizontalement facilement et est prête pour la production, tandis que LiteLM souffre d'une latence élevée, peine à dépasser un RPS modéré, ne dispose pas d'une mise à l'échelle intégrée et convient parfaitement aux charges de travail légères ou aux prototypes.




A guardrail that scans prompts, responses, and tool traffic for credentials — API keys, AWS keys, JWTs, private keys, database strings — and blocks the request or redacts the secret before it reaches a model provider.
40-plus patterns across cloud credentials, AI/ML API keys, repository and package tokens, communication-platform tokens, payment keys, database connection strings, and private keys — plus contextual detection of high-entropy strings near keywords like token= or secret=.
Minimal. TrueFoundry’s Secrets Detection runs inside the gateway with no external API call, so it’s fast and adds no per-request charge.
Redact (Mutate) when you want work to continue with the secret stripped and clean logs; block (Validate) when a credential in the content must hard-stop the request. Many teams redact on input and block where policy requires.
Yes. It runs on MCP pre-tool and post-tool hooks as well as LLM input and output, so secrets in tool parameters and tool results are caught — important for agents that read files and call APIs.
Yes. As a built-in, in-gateway guardrail it runs wherever your TrueFoundry data plane runs, including VPC and on-prem, so secrets never leave your environment.



Les dernières nouvelles, articles et ressources envoyés dans votre boîte de réception