



October 15, 2026
|
5 min de lecture


Accédez instantanément à un environnement TrueFoundry en direct. Déployez des modèles, acheminez le trafic LLM et explorez la plateforme complète : votre sandbox est prête en quelques secondes, aucune carte de crédit n'est requise.



Published: October 15, 2026

Une méthode incroyablement rapide pour créer, suivre et déployer vos modèles !
Haiku represents Anthropic’s low-end layer model — the type of model that one calls on for heavy, time-sensitive workload tasks. Classification, extraction, routing, short rewrites, tool-call formatting, first-pass drafts: work where a capable-enough answer returned quickly and cheaply beats a slightly better answer that costs 20× more and takes longer.
Haiku 5.5 shipped on October 7, 2026. The headline is the price cut: Anthropic dropped the per-token rate by up to 90% versus Haiku 4.5 while keeping the frontier-tier plumbing — a 1-million-token context window, 128K maximum output, prompt caching, and the Batch API. The inexpensive version is not the stripped-down version for the very first time.
However, a lot of work is packed into that one word. There is tier break in the rate card, which silently makes your bill go up. The token cost gives little hint as to how much anything actually costs. This review explores both processes.
Here is the full rate card next to Haiku 4.5 and Sonnet 5.5, so the gaps are visible in both directions.
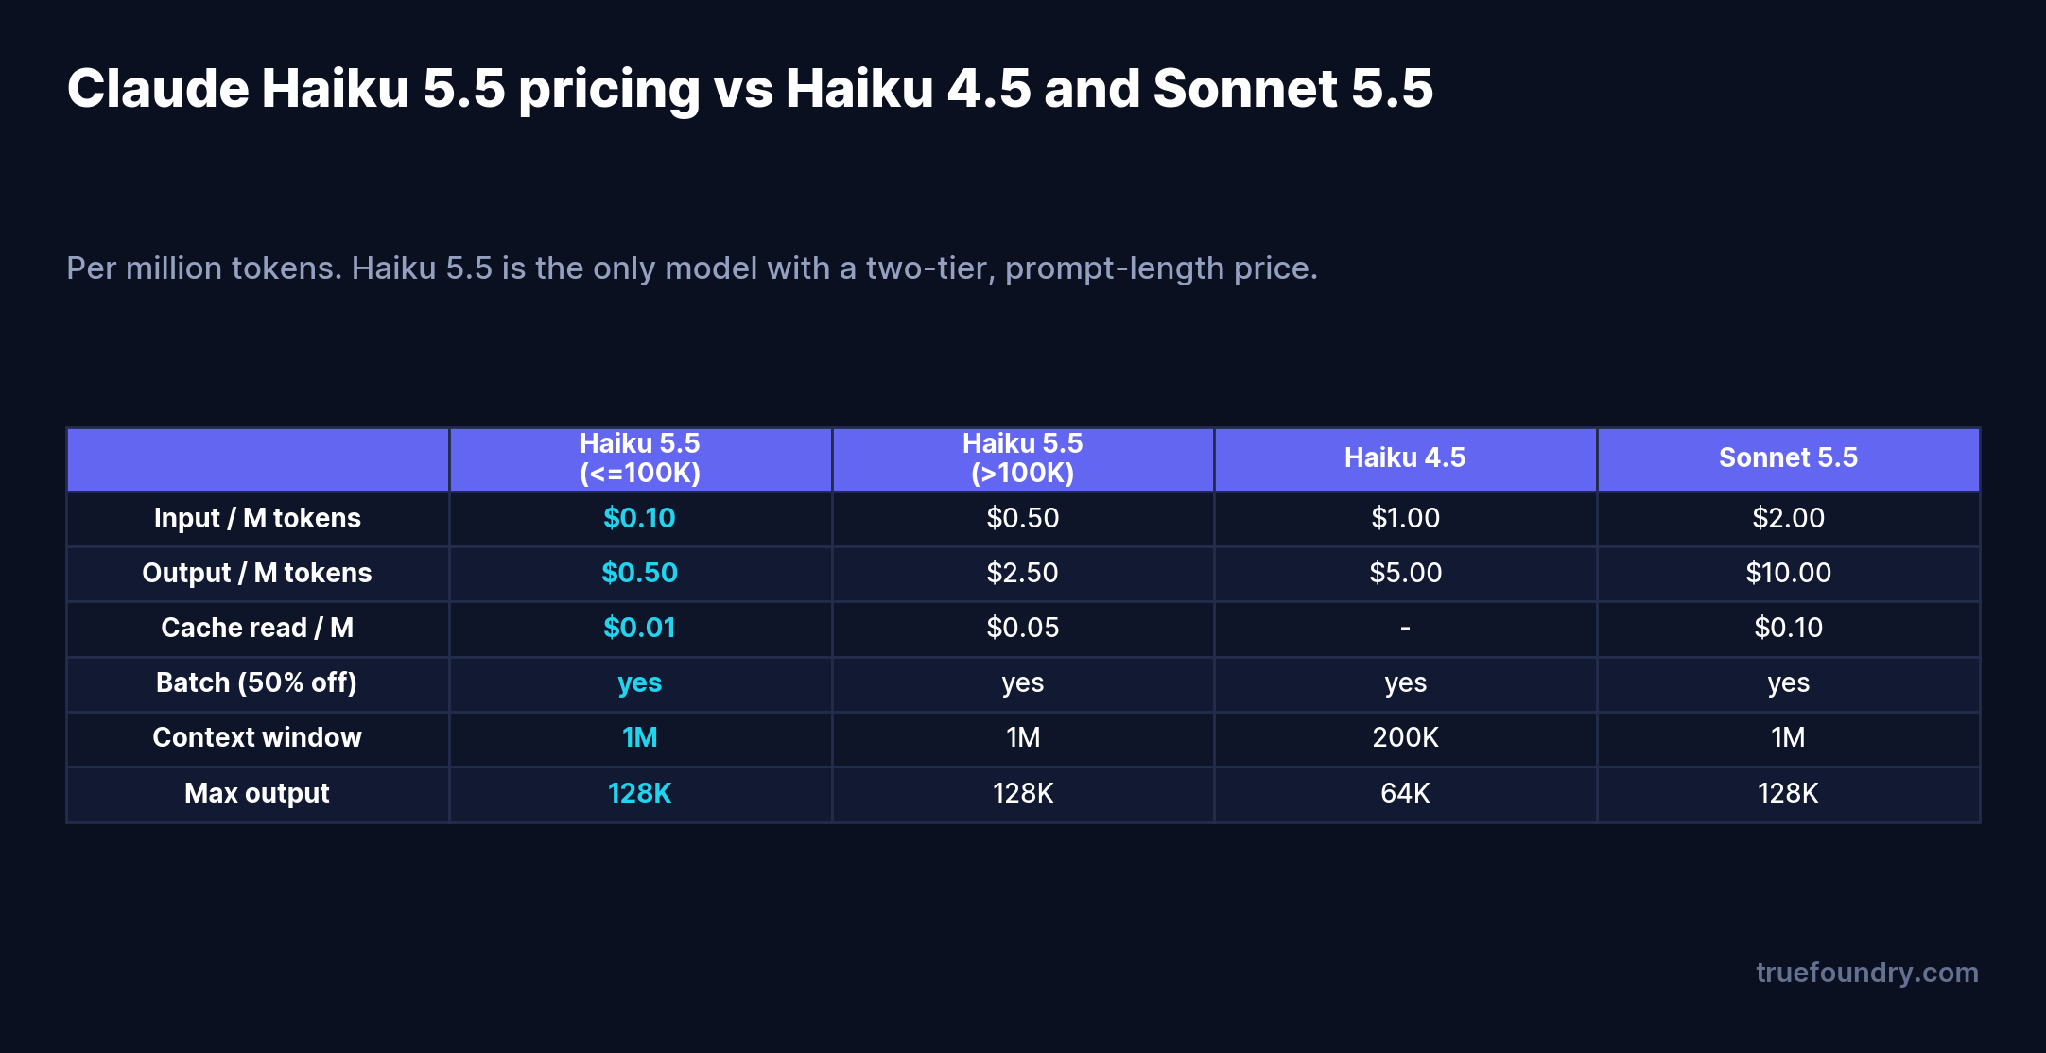
Three things stand out.
The input price is the story. At $0.10 per million input tokens, Haiku 5.5 is a tenth of Haiku 4.5 and a twentieth of Sonnet 5.5. For input-heavy work — RAG, long context, document processing — that is where most of the bill lives, and it is where Haiku 5.5 is most aggressive.
Caching and batching stack on top. Cache reads are $0.01 per million tokens, so a stable system prompt or a reused document is nearly free on repeat calls. The Batch API takes another 50% off for work that tolerates asynchronous turnaround. Neither is unique to Haiku, but both compound the savings.
Everything above 100K tokens is a different model, pricing-wise. That is the catch, and it deserves its own section.
Haiku 5.5 is the only model in the lineup with a two-tier, prompt-length-dependent price. Up to 100K tokens in a single request, you pay $0.10 / $0.50. The moment a prompt crosses 100K, the rate becomes $0.50 / $2.50 — five times the input rate and five times the output rate — and it applies to the whole prompt, not just the tokens above the line.
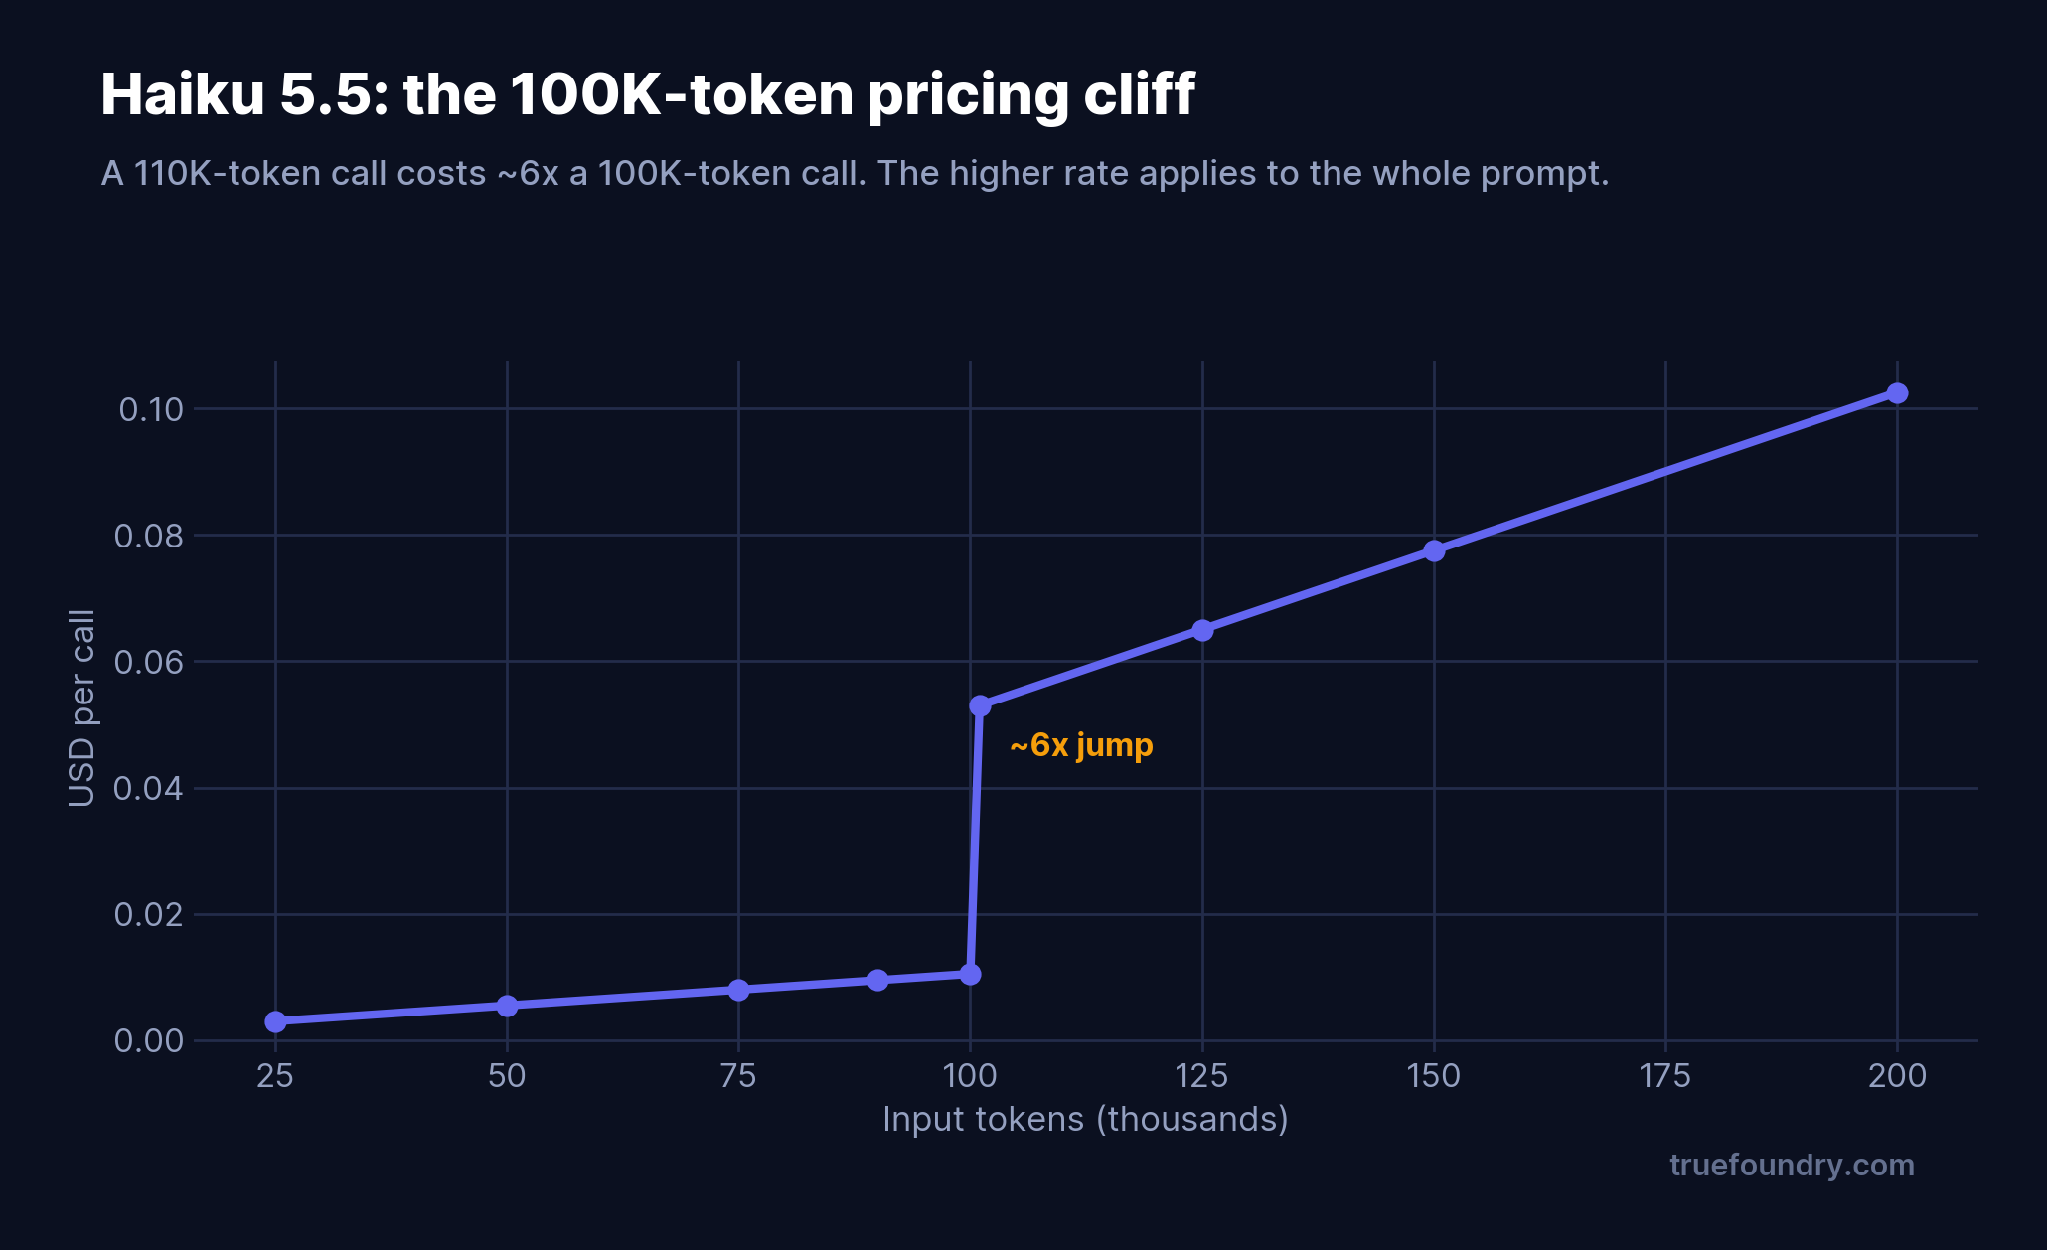
The effect is a step, not a slope. A 90K-token call with 1K of output costs about $0.0095. Push the same call to 110K tokens and it costs about $0.0575 — roughly 6× more for 22% more input. Nothing about the work changed; you just stepped over a pricing boundary.
For most workloads this never bites, because most prompts are far under 100K. But three patterns live right on the edge: RAG pipelines that stuff large retrieved contexts, full-document or full-codebase analysis, and long agentic chains that accumulate history turn after turn. If any of those routinely cross 100K, the 20× advantage over Sonnet narrows to about 4×, and the math for using Haiku at all gets closer. You want to know when your traffic is crossing that line — which, again, is a measurement problem.
Here is the trap in every “it’s $0.10 per million tokens” headline: you do not buy tokens, you run tasks. And tasks have wildly different token shapes.
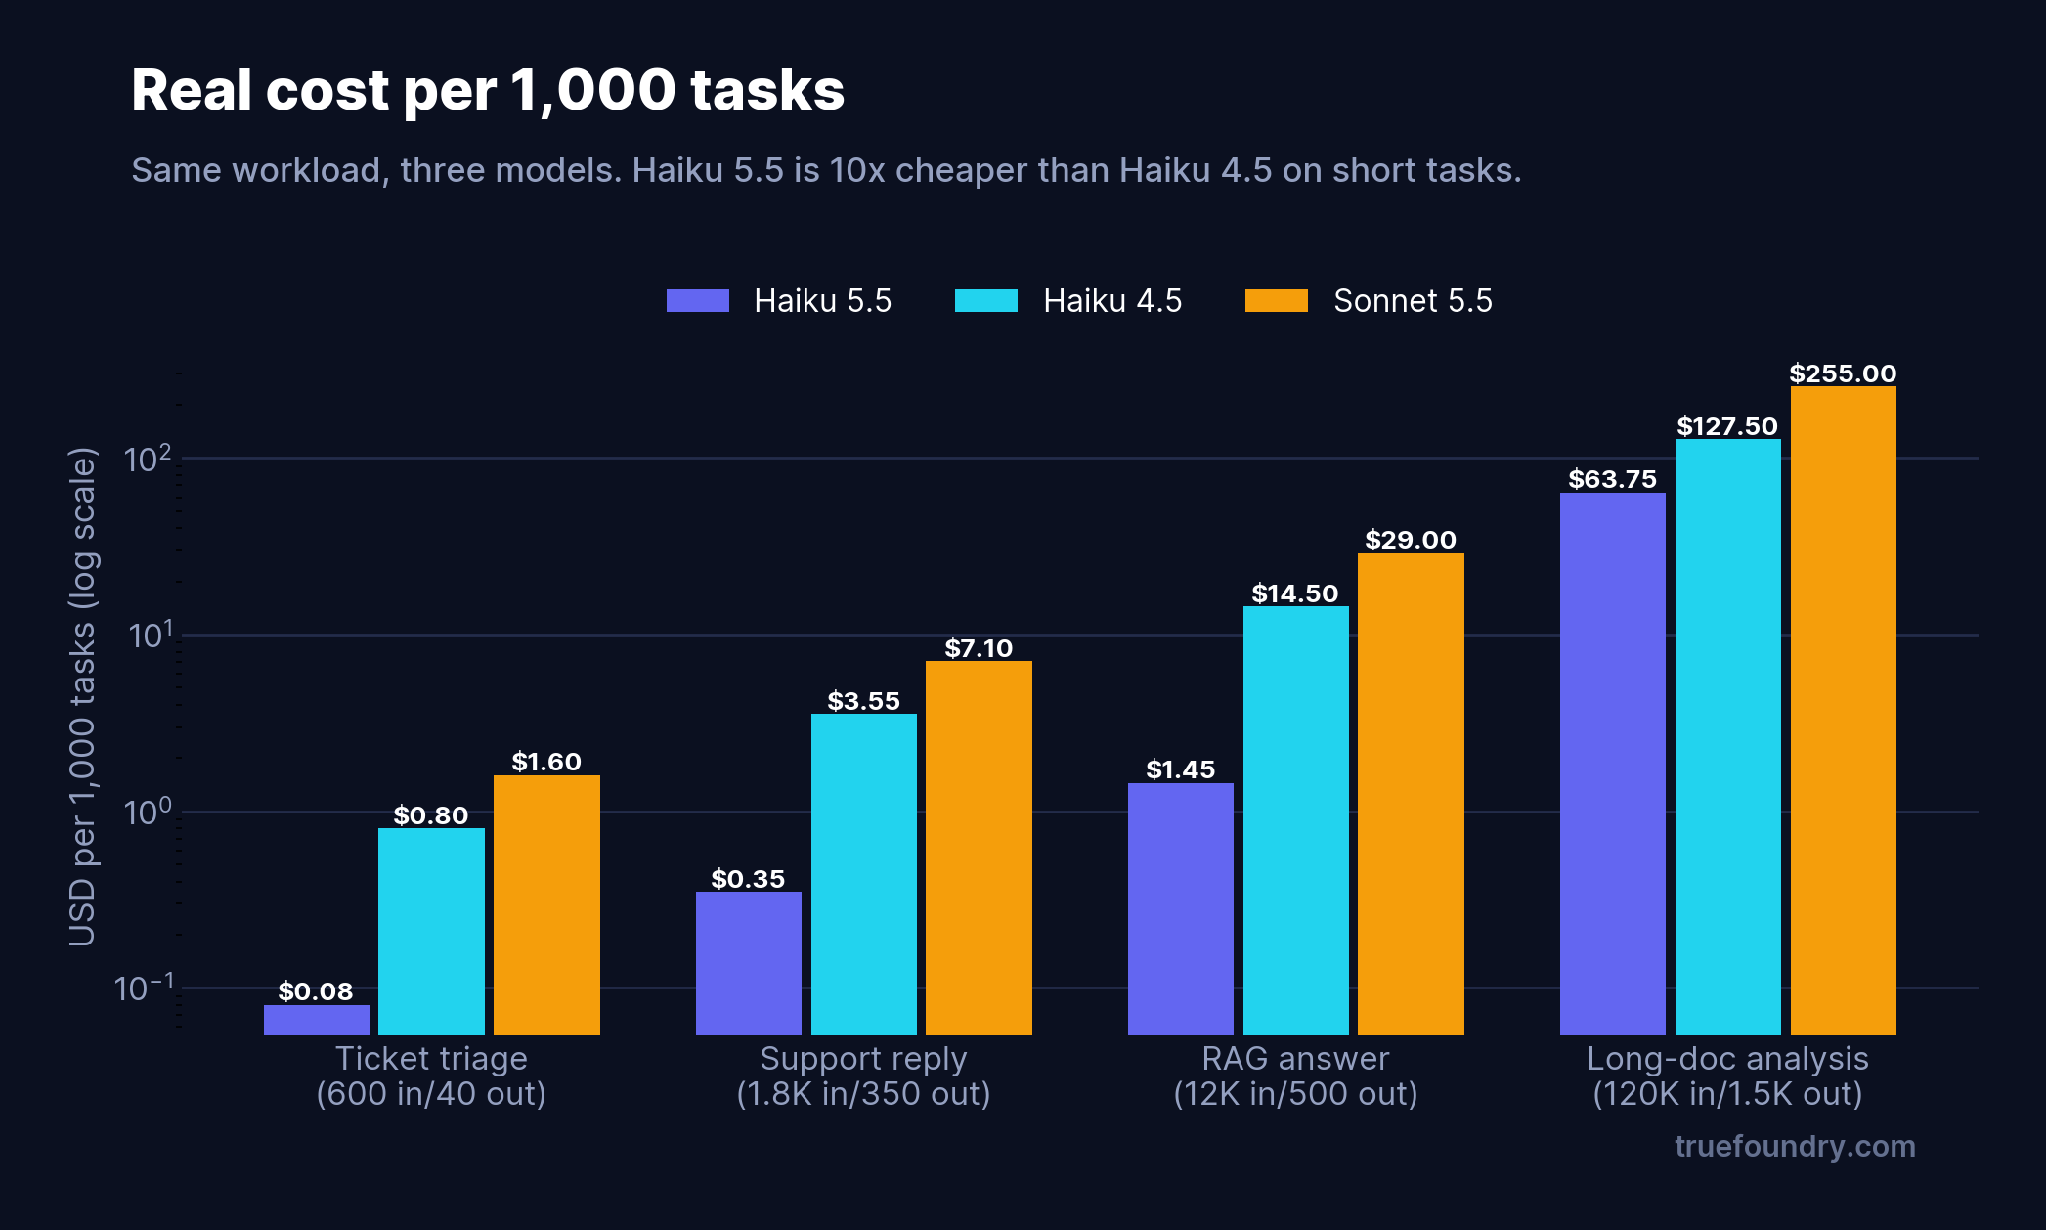
Four representative jobs, priced on Haiku 5.5 at its standard tier (the long-document job uses the >100K rate):
That is an 800× range on a single model, driven entirely by task shape. It is why “which model is cheapest” is the wrong question. The right question is “what does my task cost on this model, at my real input/output ratio and my real volume” — and the answer moves the moment your prompts get longer or your output grows.
Two numbers decide everything: your input-to-output ratio, and whether you cross 100K. A summarizer (huge input, tiny output) behaves completely differently from a content generator (small input, huge output), because output tokens cost 5× input tokens on Haiku. Average rates hide that. Per-task measurement surfaces it.
They budget off the input rate. Output is 5× the input price on Haiku. A chatty agent that emits long responses can cost far more than its input volume suggests. Watch output tokens, not just input.
They ignore the cliff until the invoice. A RAG system that creeps from 80K to 110K average context as the knowledge base grows doesn’t fail — it just quietly gets ~6× more expensive per call. Without per-request visibility, nobody notices until finance asks.
They compare sticker prices instead of blended cost per task. The model that wins on a spec sheet can lose on your actual traffic mix. The only honest comparison is your own tasks, measured.
They leave caching on the table. A stable system prompt re-sent on every call is pure waste at $0.10/M when it could be $0.01/M cached. On high-volume Haiku traffic, cache hit rate is a real line item.
The theme above is the same every time: you cannot manage what you cannot see per task. The TrueFoundry AI Gateway sits in front of every model call and meters it, so “what does Haiku actually cost us” becomes a dashboard rather than a spreadsheet exercise.
When you add a model, the gateway attaches a cost basis. Public Cost pulls provider-published rates from TrueFoundry’s open-source pricing catalog (github.com/truefoundry/models), auto-populated and kept current — including region-specific and tiered rates, which is exactly how Haiku’s 100K tier is handled. Private Cost lets you enter negotiated or custom rates for contracts and fine-tuned models.
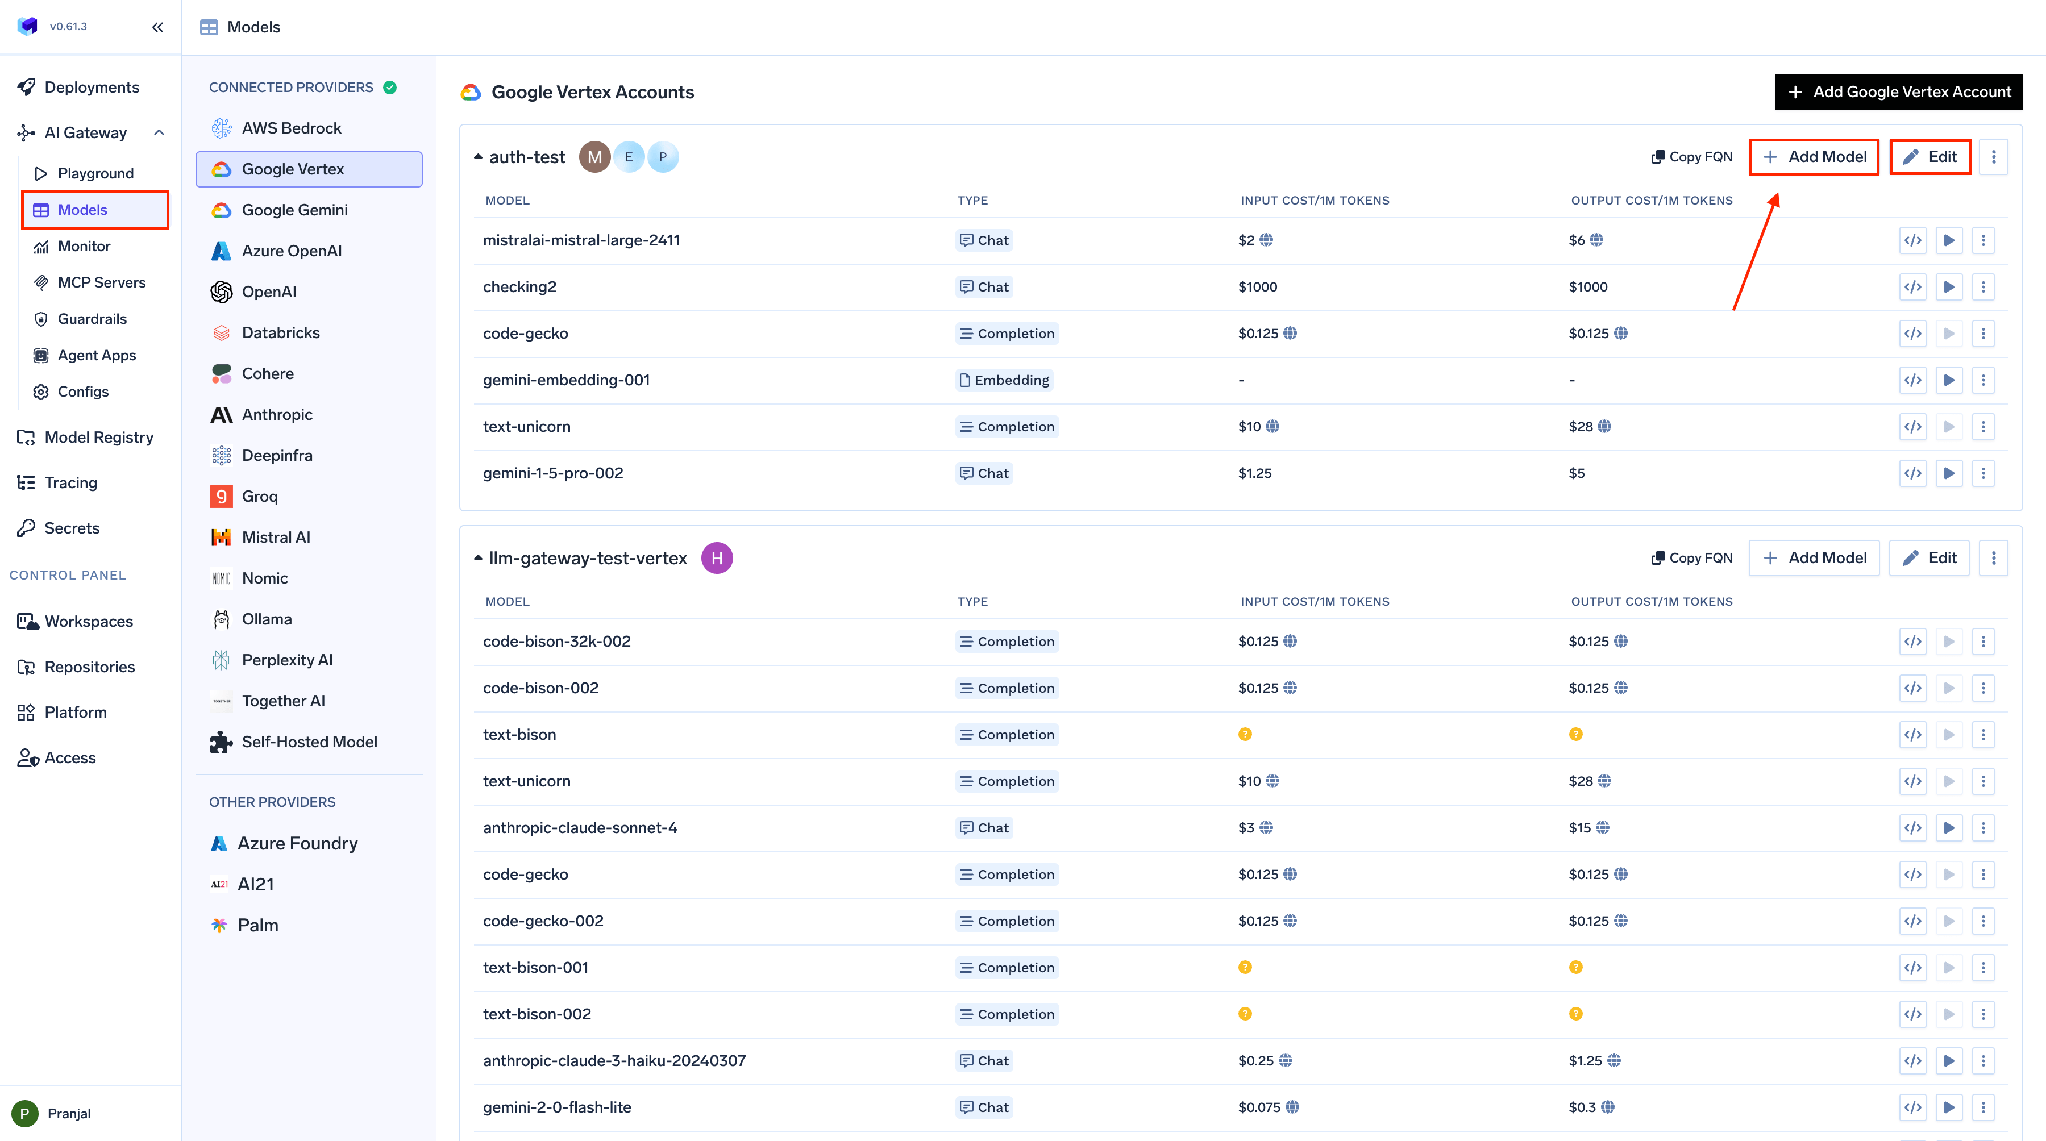
Because the catalog models tiered pricing, Haiku’s jump from the $0.10 tier to the $0.50 tier above 100K tokens is tracked correctly per request, rather than billed at a flat average that would understate your long-context calls.
Once calls are flowing, the Metrics dashboard shows total spend, a Cost of Inference trend, and one-click breakdowns by model, by user, and by team.
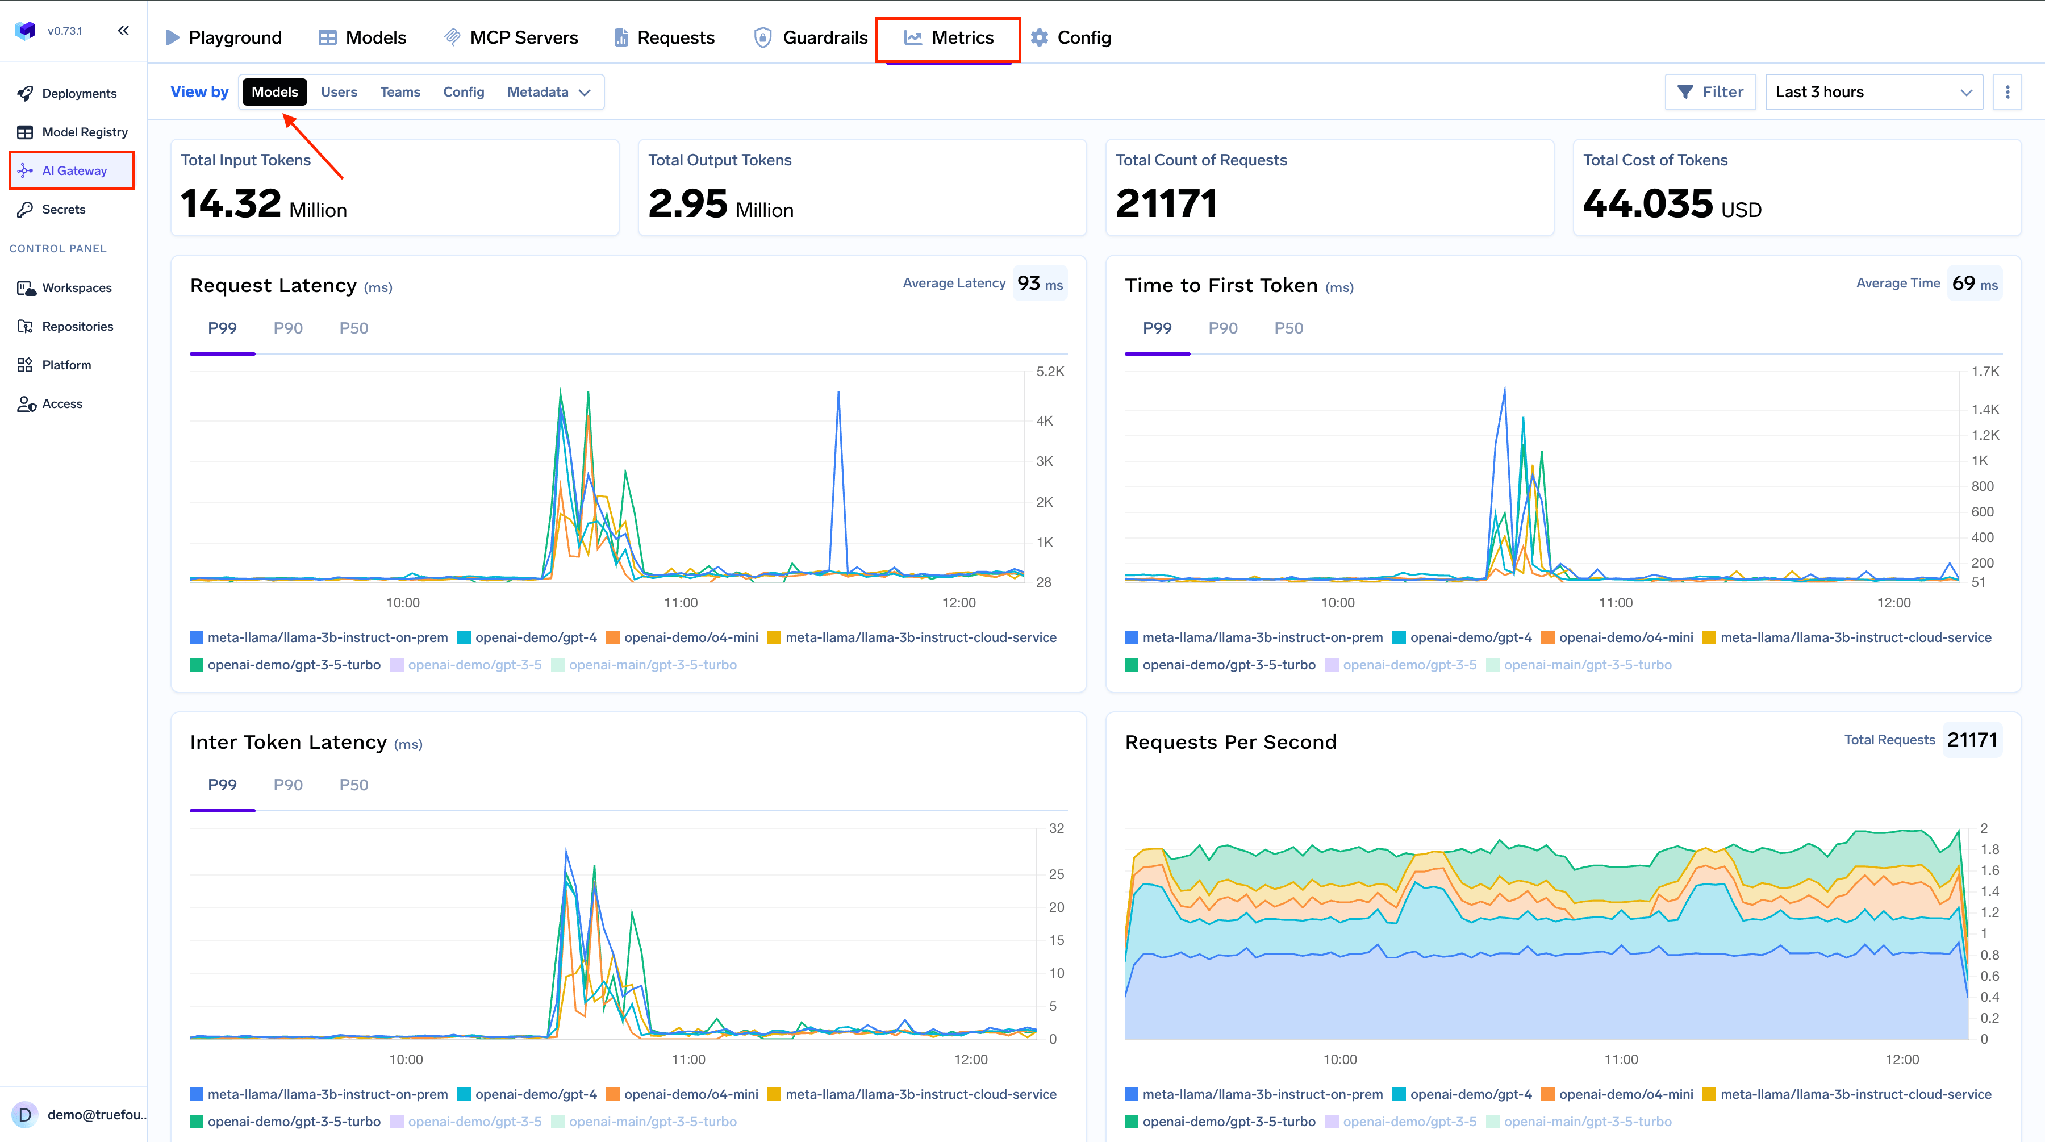
The model view answers “how much is Haiku costing us versus Sonnet this month”; the team view supports chargeback; the user view surfaces the one power user driving a third of the bill.
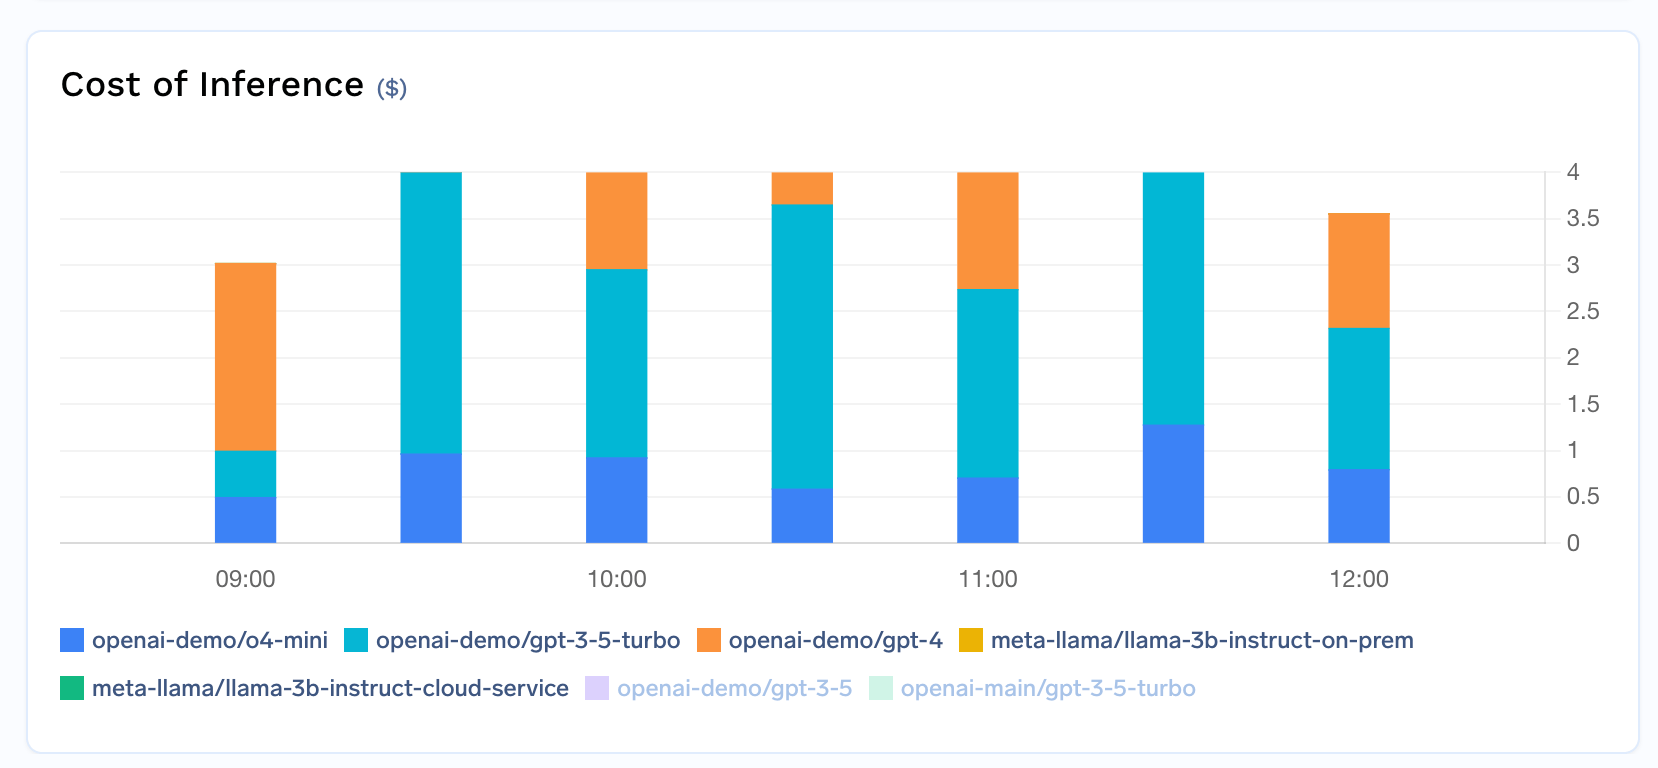
Cost-by-model breakdown. Source: TrueFoundry docs.
Beyond the built-in views, you can attach custom metadata — application, environment, customer_id, cost_center — and group cost by it. Virtual-account tags and team-associated tokens inject that metadata automatically, so you get per-application and per-customer cost attribution without changing a line of client code. You can enforce it with a metadata-validation guardrail that rejects requests missing a required key, and export the raw data grouped however you need for finance.
For the token-level mechanics behind these numbers — cached text versus cached image rates, audio billing, and how cancelled streams are costed — the cost-tracking documentation has the full formulas.
A SaaS company runs a customer-support assistant: 50,000 conversations a day, averaging 1,800 input tokens (system prompt + retrieved context + history) and 350 output tokens per reply.
On Haiku 5.5 at the standard tier, that is about $0.355 per 1,000 replies, or roughly $17.75 a day — call it $533 a month. The same traffic on Sonnet 5.5 would be about $7.10 per 1,000, or $355 a day — $10,650 a month. The model choice is a 20× swing on an identical workload.
Now add caching. The system prompt and tool definitions are ~1,200 of those 1,800 input tokens and never change. Cached at $0.01/M instead of $0.10/M, the input cost on repeat calls drops substantially — the gateway’s cache metrics show the exact dollar savings and hit rate, so you can prove the optimization paid off rather than assume it did.
The point is not the specific figures; it is that each lever — model tier, caching, the 100K boundary — is measurable per task, which means it is manageable.
TrueFoundry AI Gateway offre une latence d'environ 3 à 4 ms, gère plus de 350 RPS sur 1 processeur virtuel, évolue horizontalement facilement et est prête pour la production, tandis que LiteLM souffre d'une latence élevée, peine à dépasser un RPS modéré, ne dispose pas d'une mise à l'échelle intégrée et convient parfaitement aux charges de travail légères ou aux prototypes.




$0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100K tokens. Above 100K, it is $0.50 input and $2.50 output, applied to the whole prompt. Cache reads are $0.01/M and the Batch API is 50% off.
Yes — substantially. Haiku 4.5 was $1.00 / $5.00 per million tokens, so Haiku 5.5’s standard tier is about 90% cheaper on the headline rate and roughly 75% cheaper to run on average across typical workloads.
Haiku 5.5 has two price tiers split at 100K tokens per prompt. Crossing 100K moves the entire prompt to the higher rate, so a 110K-token call costs about 6× a 100K-token one. It only affects long-context work.
Meter it at the gateway. TrueFoundry tracks cost per request, model, user, team, and custom metadata, so you see blended cost per task across your actual traffic instead of estimating from the rate card.
Yes. The TrueFoundry AI Gateway normalizes cost across providers, so Haiku, Sonnet, GPT, Gemini, and open models all appear in one dashboard with consistent per-task and per-team attribution.
Yes. TrueFoundry’s data plane runs in your VPC or on-prem, so prompts and usage data stay in your environment while you still get unified cost tracking and governance.



Les dernières nouvelles, articles et ressources envoyés dans votre boîte de réception

















