October 29, 2026
|
5 min read


Blazingly fast way to build, track and deploy your models!
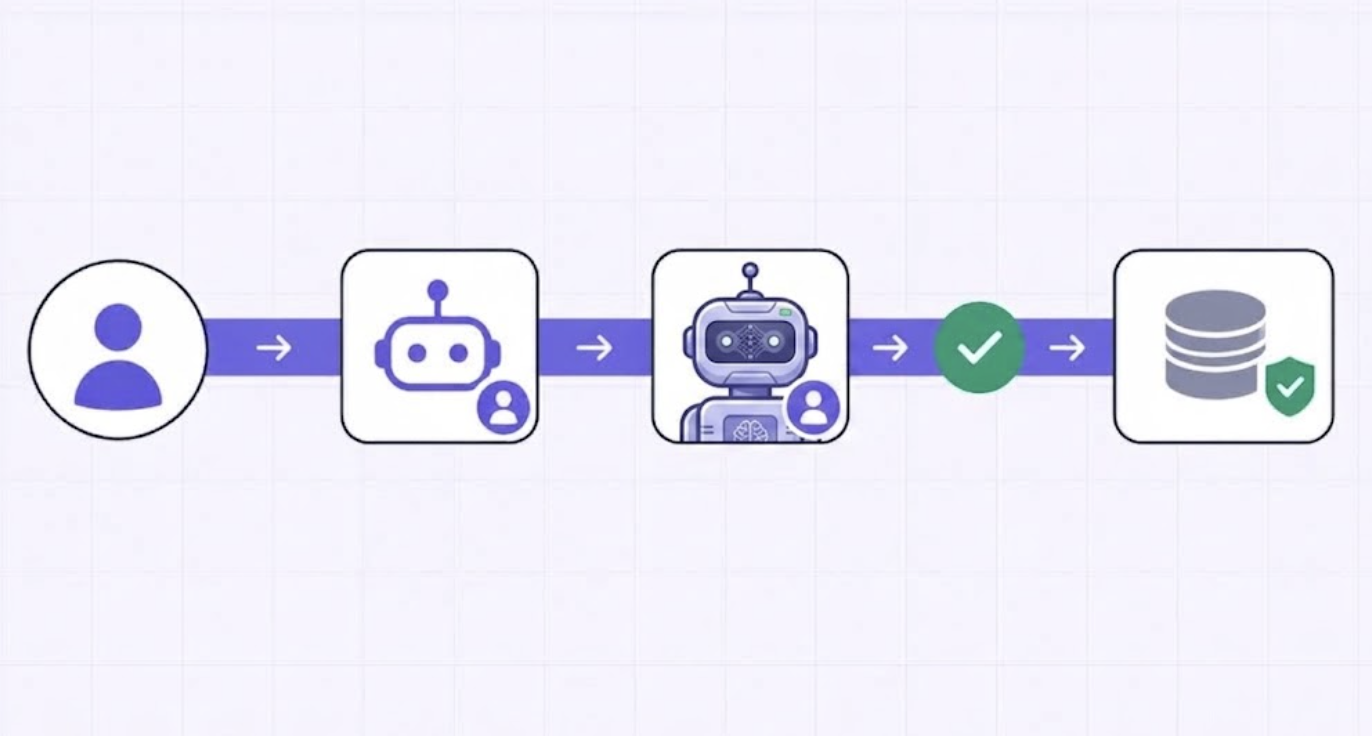
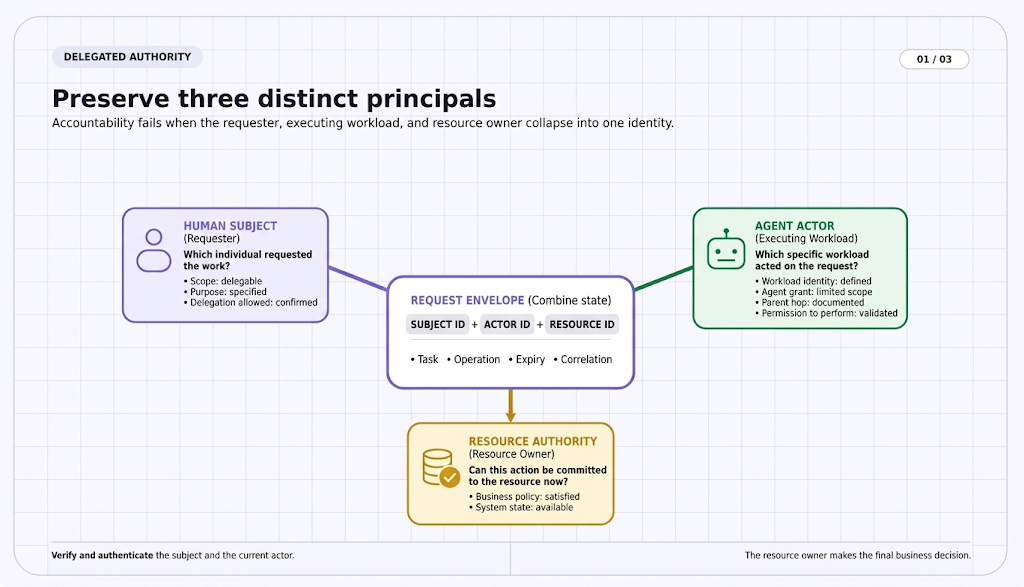
エージェントのアイデンティティは、どのワークロードが呼び出しを行っているかを特定します。本番環境の認可においては、人間である主体、委任の範囲、リソースの対象、タスクの意図、承認、そして現在のビジネス状態を、すべてのホップを通じて保持する必要があります。
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.