



October 14, 2026
|
5 min read


Obtenha acesso instantâneo a um ambiente TrueFoundry ao vivo. Implante modelos, direcione o tráfego de LLM e explore a plataforma completa — seu sandbox estará pronto em segundos, sem necessidade de cartão de crédito.



Published: October 14, 2026

Blazingly fast way to build, track and deploy your models!
Deepgram is a speech-to-text and text-to-speech provider built for real-time, production voice. Its current flagship transcription model, Nova-3, handles both pre-recorded and streaming audio, with smart formatting, diarization, and multilingual support. On the output side, Aura turns text into natural speech for voice agents and IVR.
Within any transaction of the voice app, they occupy opposite sides; the caller says something, then Nova-3 converts the audio signal into text, an LLM infers from that information, and then Aura (or other TTS engine) says the result aloud. With Deepgram being quick and accurate, it is becoming the default tool for both transcription hops and increasingly speech hops.
The problem lies in the practice. Deepgram is yet another vendor, with yet another API key, yet another SDK, yet another expense — and since it is billed based on the time and number of characters transcribed and not by tokens, it is not part of your spending tracking of LLM. But for one design it will be okay. In an enterprise with a team of voice bots, it’s a case of governance failure.
Here is the pay-as-you-go rate card for the models you are most likely to use.
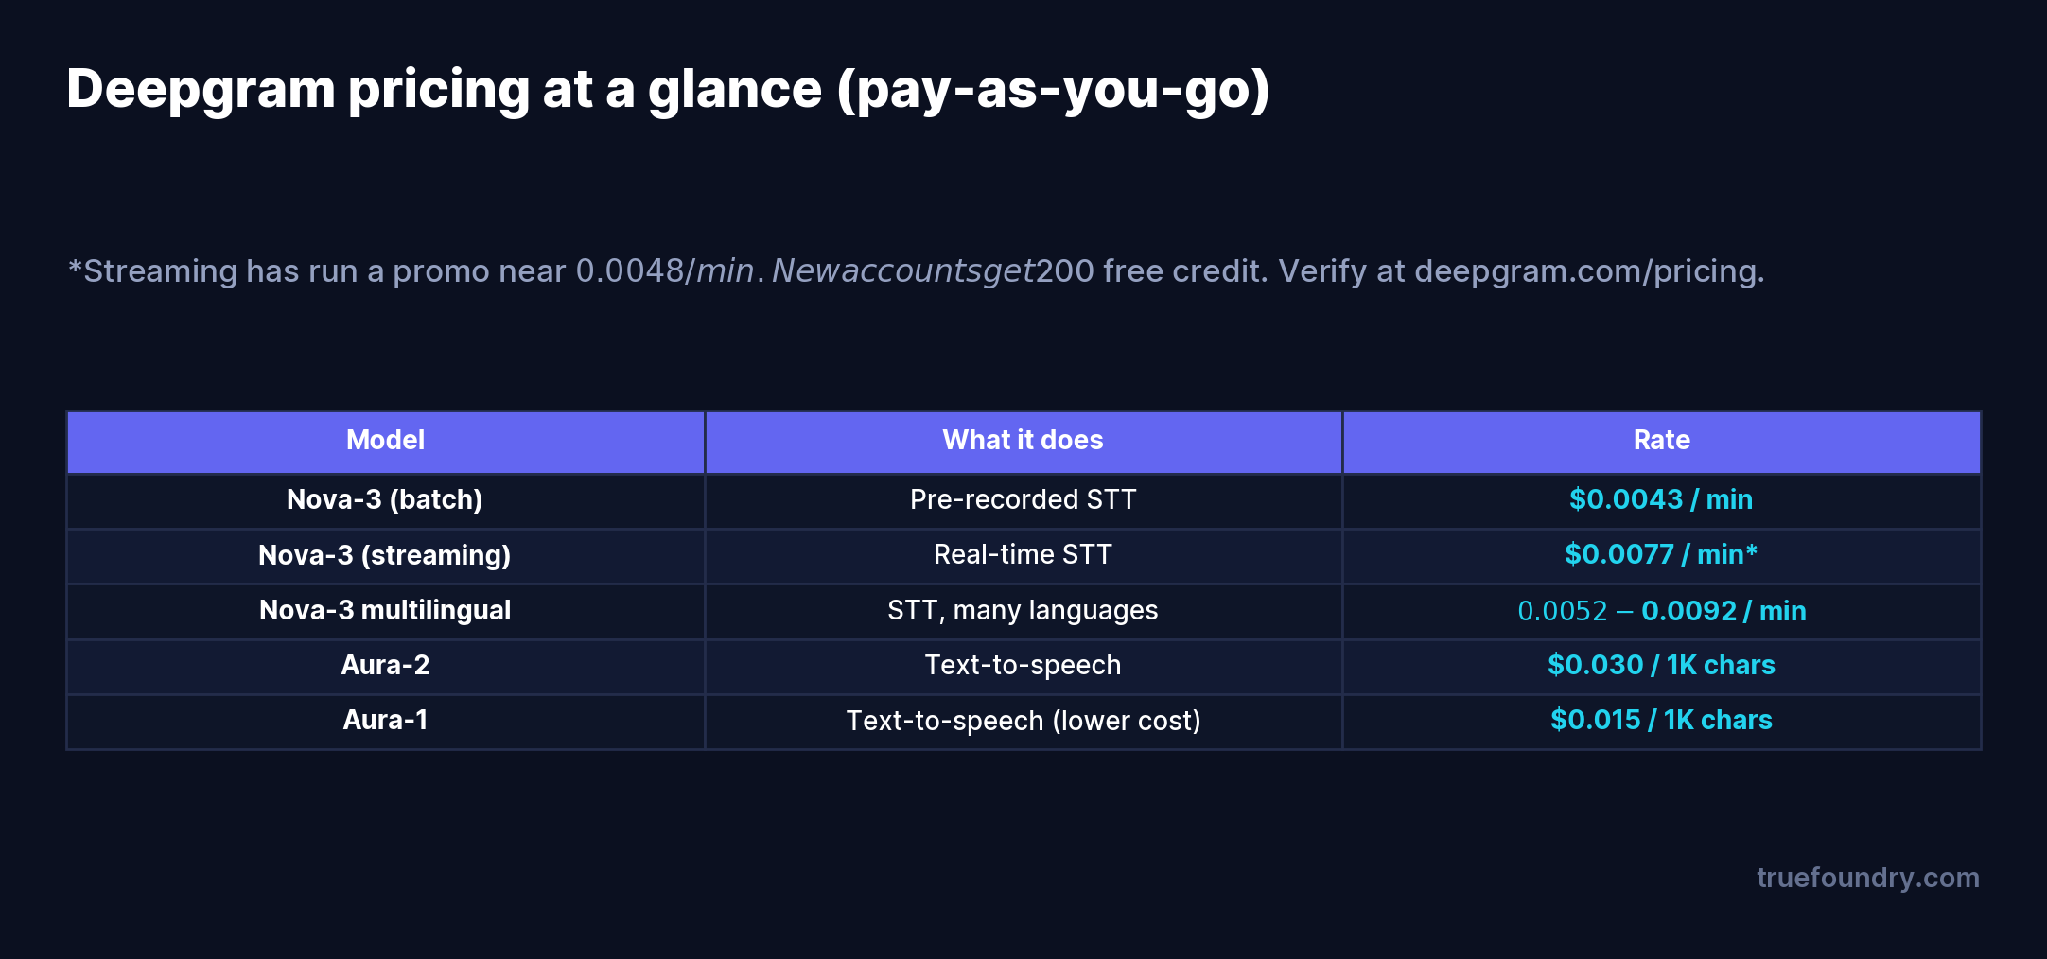
Two things to note. First, the unit is not the token. STT is billed per minute of audio, TTS per 1,000 characters of input text. That mismatch is exactly why voice cost tends to escape token-based dashboards. Second, streaming costs more than batch — real-time transcription runs higher than pre-recorded, so a live voice agent is priced differently from an offline transcription pipeline. New accounts get $200 in free credit to start [VERIFY current rates and credit at deepgram.com/pricing; promotional streaming prices have fluctuated].
A voice agent is not one model call — it is a chain, and every hop is a provider you pay, monitor, and can have fail on you. Putting the whole chain behind one gateway turns that sprawl into a single governed path.
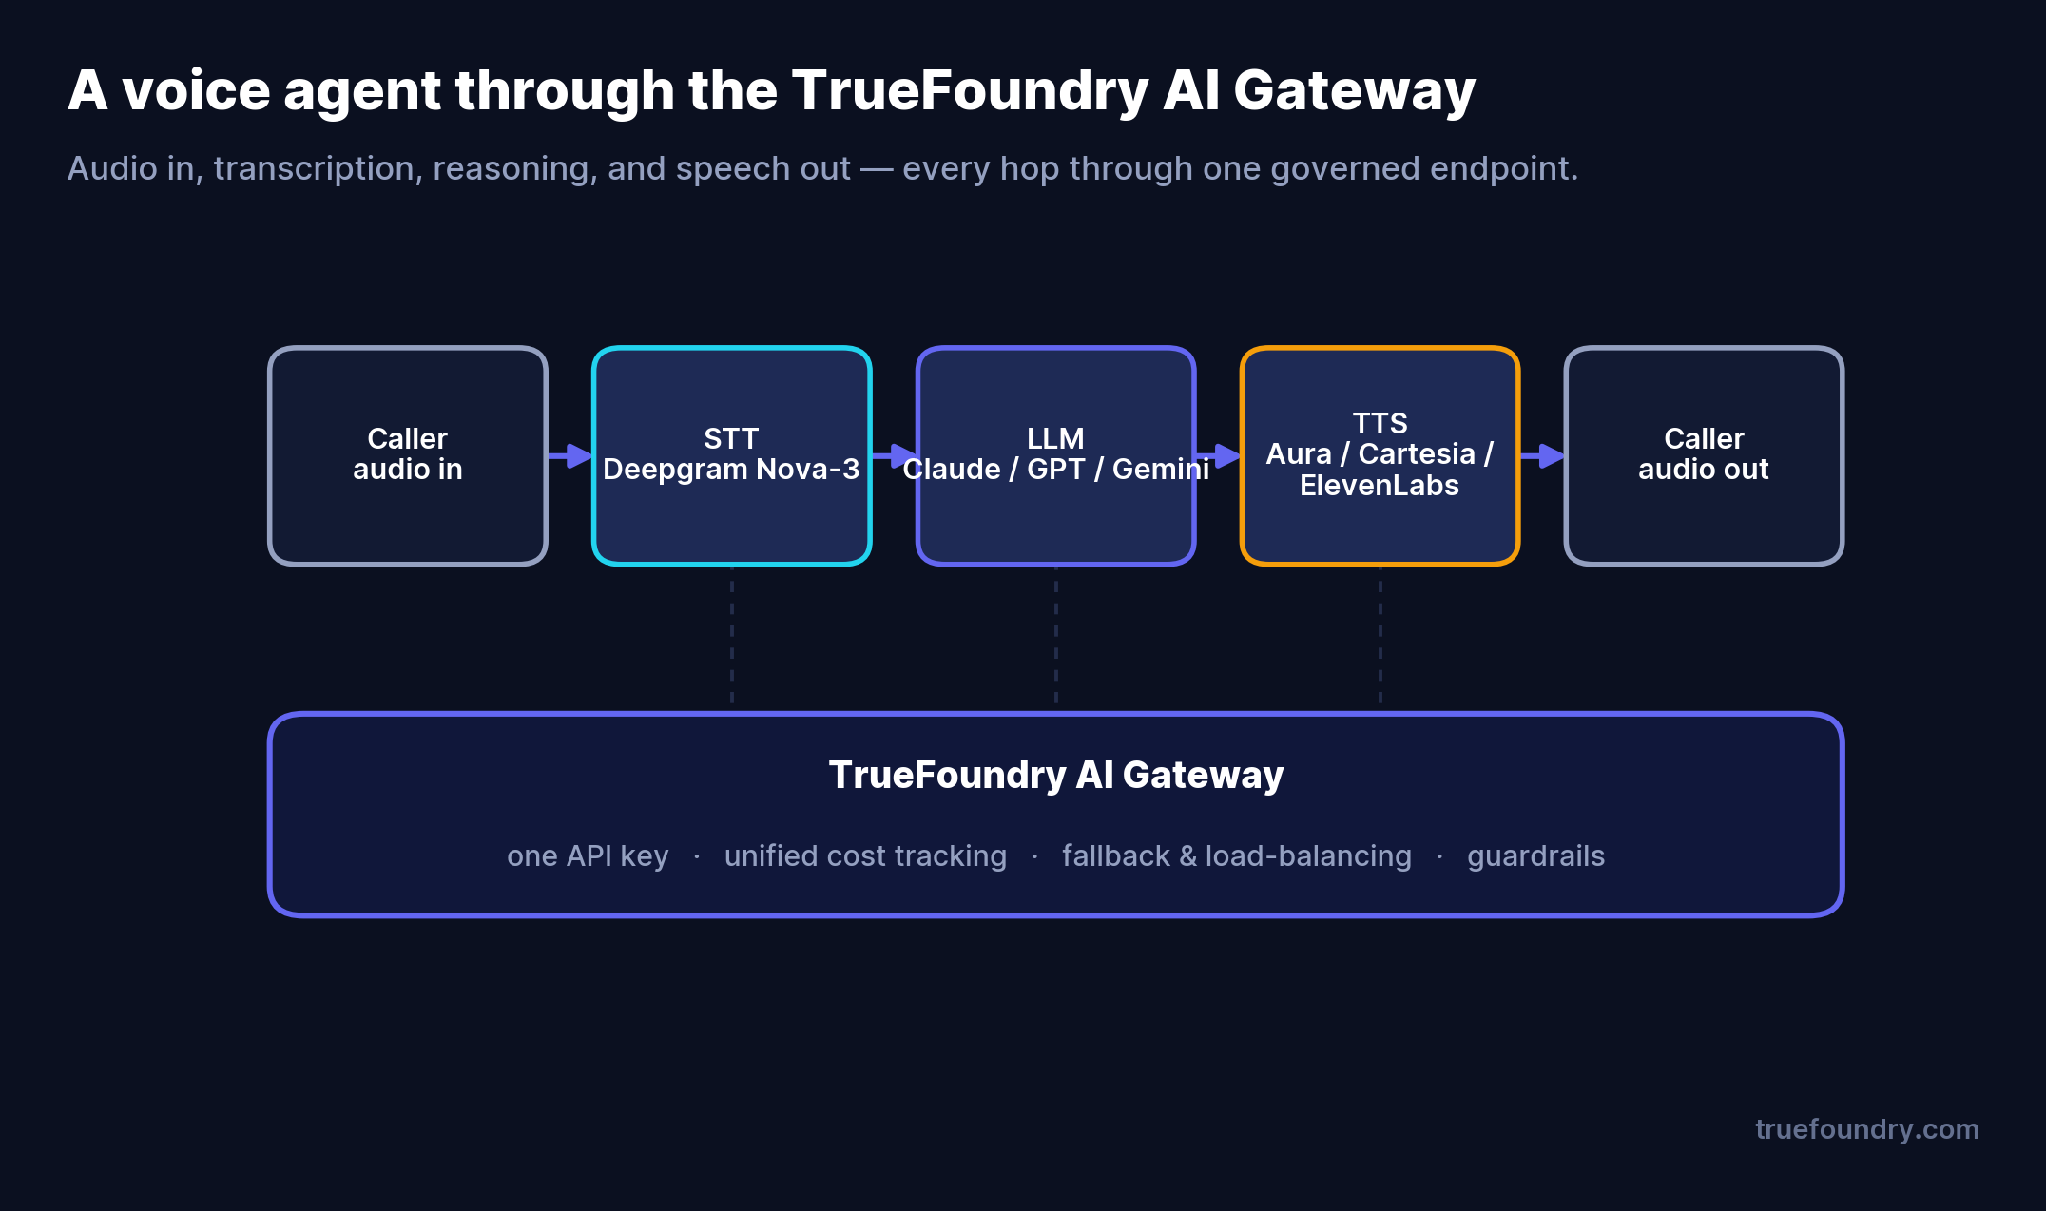
A voice agent through the TrueFoundry AI Gateway
Routing Deepgram through the TrueFoundry AI Gateway gives you four things you do not get calling it directly:
Deepgram is not the only speech provider the gateway supports, which is what makes fallback and comparison possible.
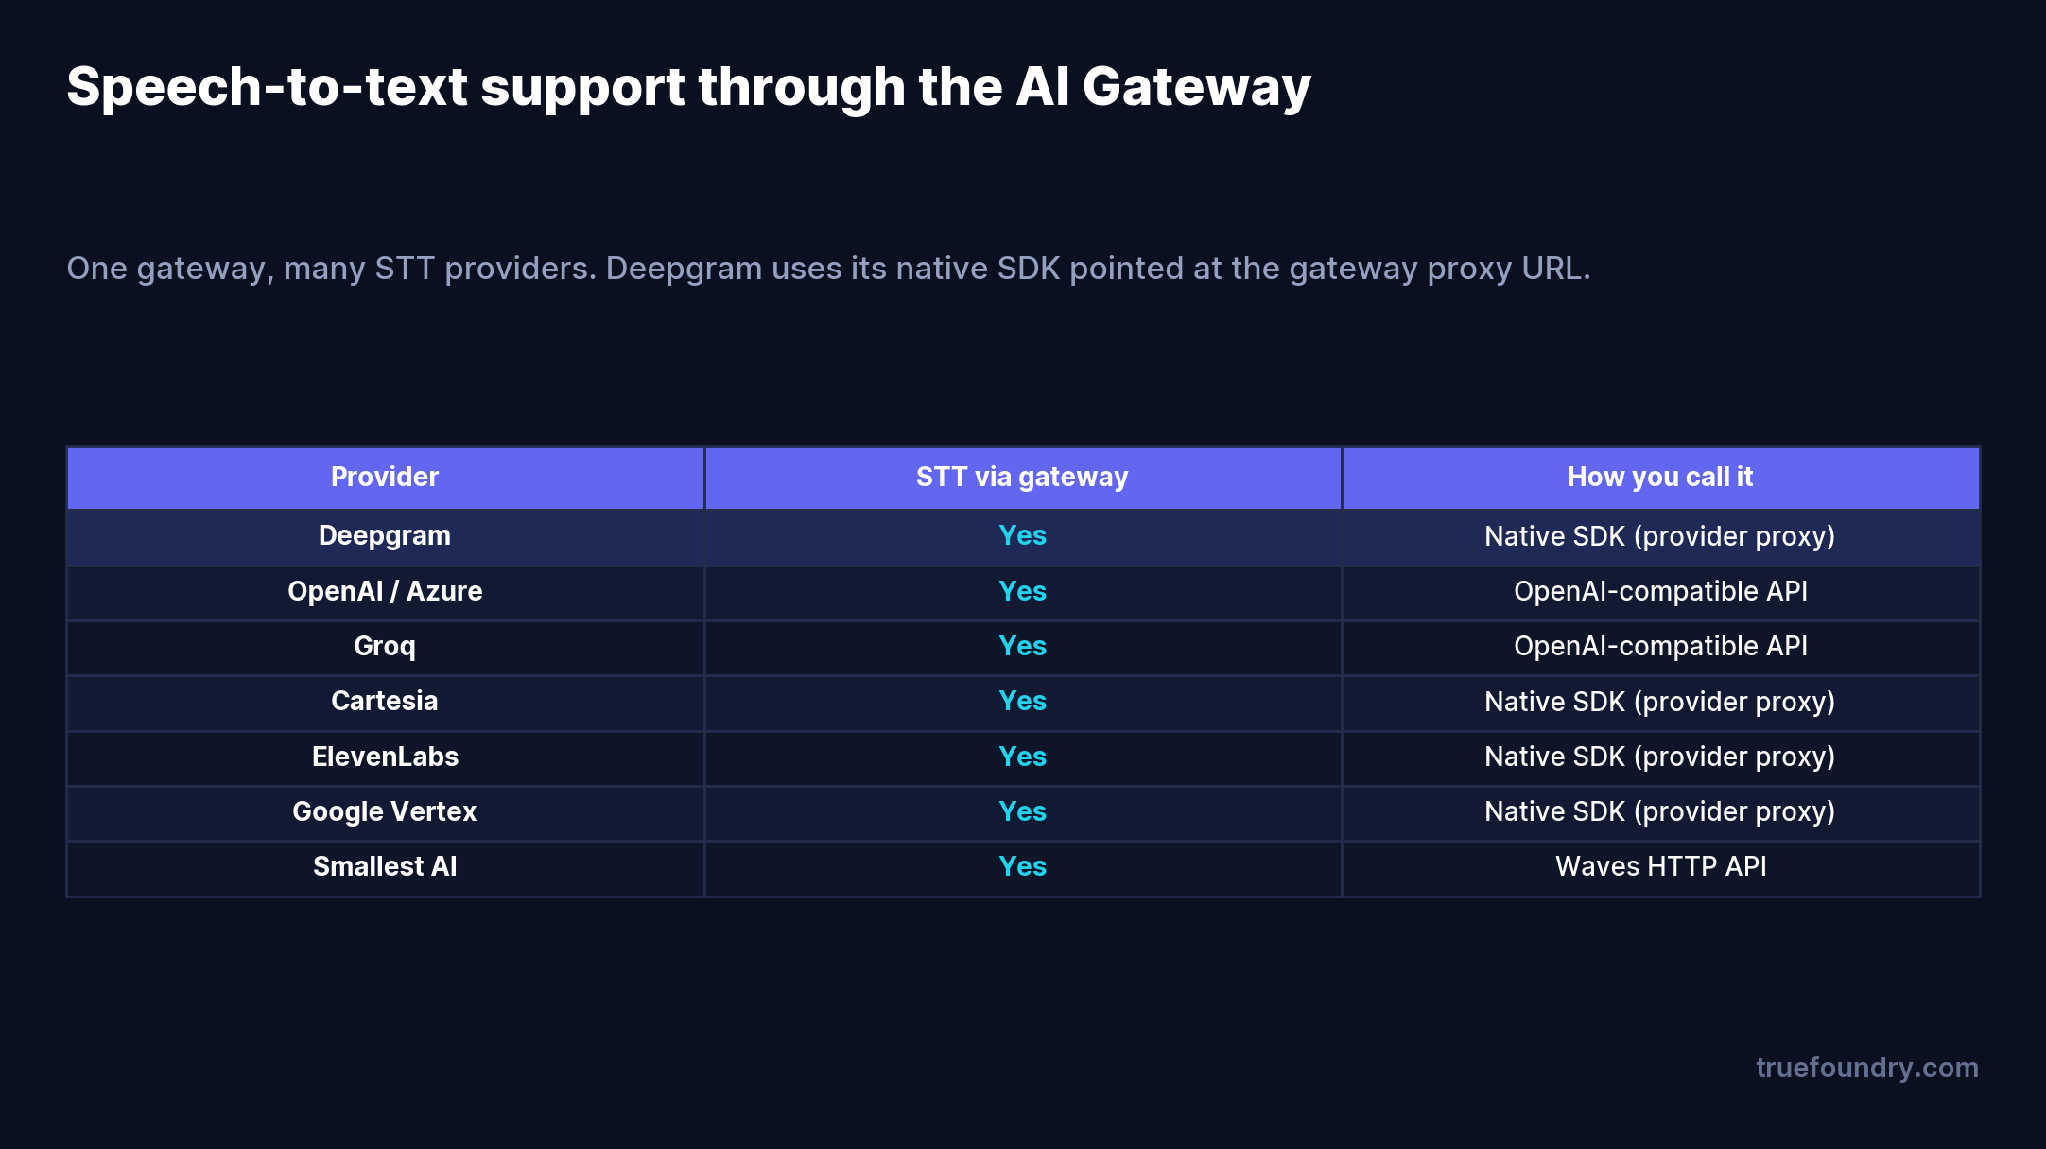
Speech-to-text support across providers in the gateway
Deepgram, Cartesia, ElevenLabs, Google Vertex, and Smallest AI are called through the gateway’s provider proxy using each one’s native SDK, while OpenAI, Azure, and Groq use the OpenAI-compatible API. That means you keep Deepgram’s exact feature set — you are not flattening it to a lowest-common-denominator API — while still getting one key, one bill, and one failover layer.
They track LLM cost and forget audio. Token dashboards miss per-minute and per-character spend entirely. On a busy voice product, transcription and speech can rival the LLM bill — and nobody sees it until finance asks.
They hardcode the Deepgram key in each service. Every voice service holding its own Deepgram credential means rotation is a redeploy and there is no central place to cap or attribute usage.
They have no failover for the voice hops. Teams build LLM fallback and leave STT/TTS as single points of failure. If Deepgram has a bad minute, the whole agent goes mute.
They confuse streaming and batch pricing. Running a real-time agent on the assumption of batch rates understates cost. Streaming is priced higher; model it that way.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.



Deepgram provides speech-to-text (Nova-3) and text-to-speech (Aura) for real-time and pre-recorded audio. It is commonly used for voice agents, call transcription, meeting notes, and IVR, where low latency and accuracy matter.
Pay-as-you-go, Nova-3 transcription is about $0.0043 per minute pre-recorded and $0.0077 per minute streaming; Aura-2 text-to-speech is $0.030 per 1,000 characters (Aura-1 is $0.015). Audio is billed per minute and per character, not per token.
Yes. Add Deepgram as a model account, then call it with Deepgram’s native SDK pointed at the gateway’s provider-proxy URL. You keep Deepgram’s full feature set while gaining one key, unified cost tracking, and fallback.
Yes. The gateway meters STT per minute of audio and TTS per character, and shows that spend alongside LLM cost, attributed by model, team, user, and request.
Yes. Create a virtual model with the Audio Transcription type spanning multiple providers; the gateway load-balances and fails over across them without a code change.
Yes. TrueFoundry’s data plane runs in your VPC or on-prem, so audio and usage data stay in your environment.



As últimas notícias, artigos e recursos enviados para sua caixa de entrada
















