August 26, 2026
|
5 min read


Published: September 18, 2026
Blazingly fast way to build, track and deploy your models!
TypeSafe AI is an AI lab founded by Diogo Almeida — previously at OpenAI, where he worked on the instruction-following research that became ChatGPT — along with Erik Gafni and Sasha Sheng. After roughly two years in stealth, the company published its launch post on September 15, 2026, alongside a $40M seed round led by DCVC. DataCamp and several trade outlets covered it over the following days.
The framing in the launch post is a question rather than a benchmark: models have been superhuman at chat for years, so where is all the automation? TypeSafe's answer is that the bottleneck was never raw intelligence — it's that a model which replies in prose is an awkward component to build software on top of. Its company manifesto puts it more bluntly: today's AI was trained on the assumption that a human sits on the other side of it.
Jev is the first model built on that premise. The name comes from William Stanley Jevons, whose paradox holds that falling cost drives rising consumption; System One is a nod to Daniel Kahneman's fast, intuitive System 1 thinking, as distinct from slow, deliberate System 2 reasoning.
Among the types of AI models you'd reach for in production, this one is defined by what it gives up. A chat model returns a string, and a string can be anything — an answer, a refusal, a paragraph of reasoning, or something malformed that your parser chokes on. Jev doesn't return strings at all.
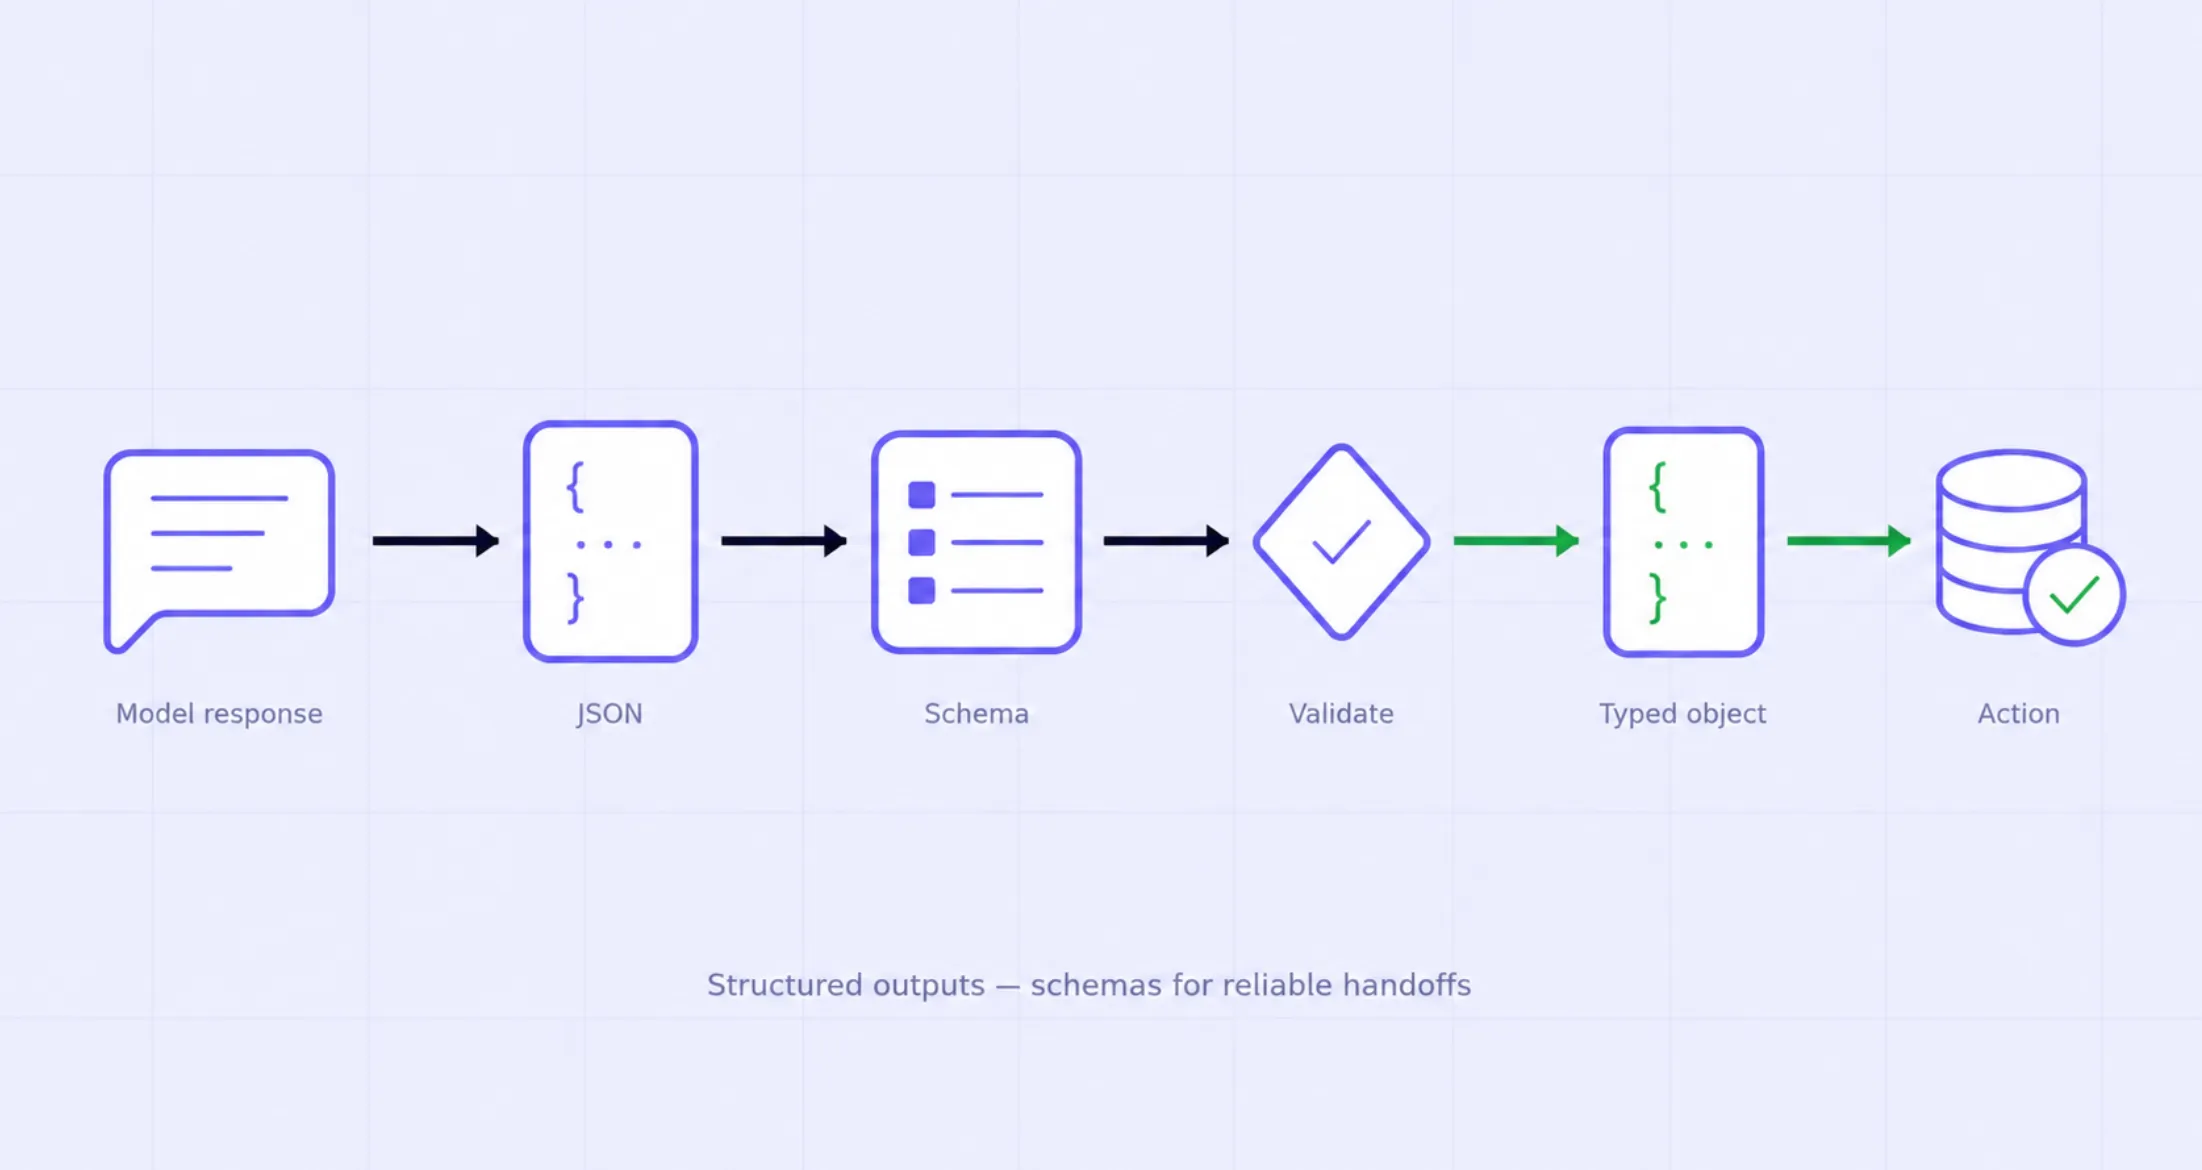
Instead, you declare the shape of the answer up front: which fields you want, and which values each field is allowed to take. The model returns those fields filled in, each with a probability attached. TypeSafe describes the result as a frontier-intelligence function call — unstructured state in, typed probabilistic decisions out. In practice it behaves less like a chatbot and more like an ai decision engine you can call from a line of code.
Three properties follow from that design:
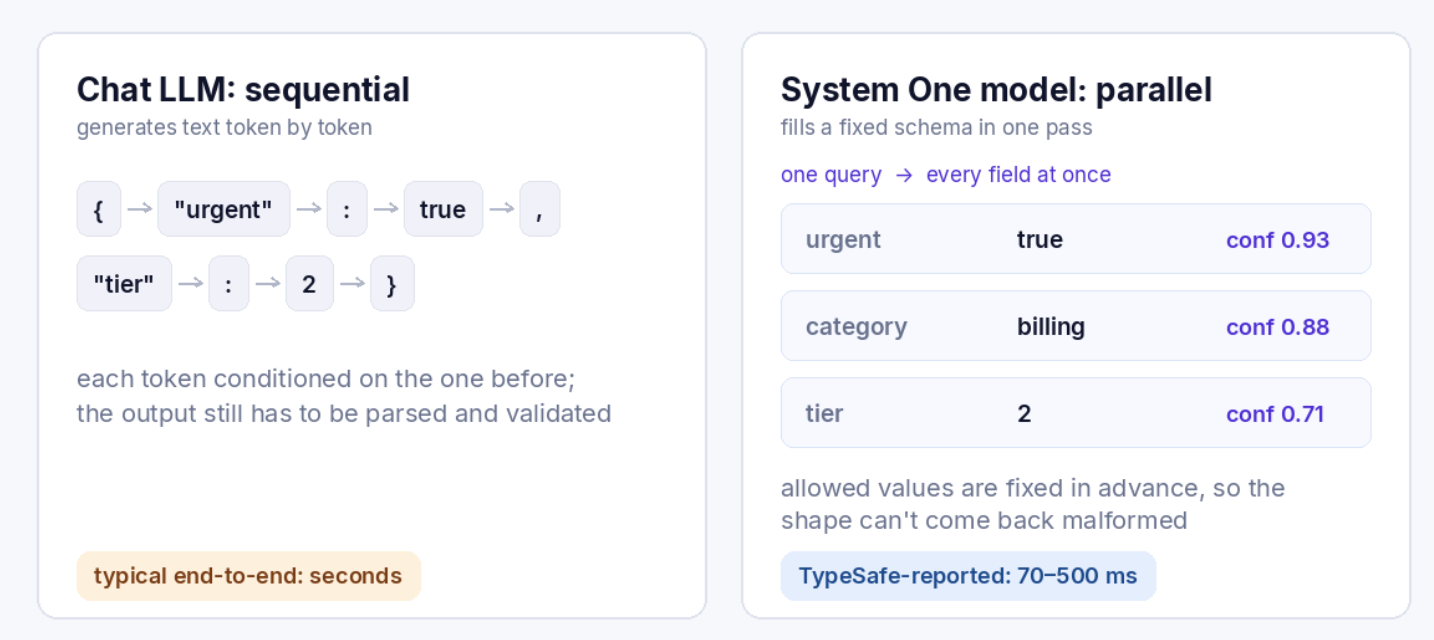
A chat LLM builds its answer token by token; a System One model fills every field of a fixed schema in one pass, each with a confidence score.
That third property is the one most likely to be underrated. A model that's right 95% of the time but can't tell you which calls are in the other 5% can't be automated around. One that reports honest uncertainty can be — you branch on the confidence score and route the low-confidence cases to a human or a bigger model.
One practical limit worth knowing: Jev supports a cardinality of up to 255 options per choice. Above that, TypeSafe uses a two-stage approach — score candidates independently, then make an explicit choice — which it acknowledges is slower.
This is the part worth slowing down on, because the launch numbers are unusually large and the evidence behind them is unusually self-contained. To TypeSafe's credit, its post includes its own "nuance" notes under each result, which is where most of the following comes from.
Independently checkable today:
Self-reported and not yet independently reproduced:
Still unknown: performance on public benchmarks, behaviour on tasks that aren't cleanly decision-shaped, accuracy on domain-specific work in someone else's hands, and anything at all about production reliability at scale. Early access only opened this week.
There's also a wording issue worth being precise about, because it will get flattened in summaries. TypeSafe says Jev can't hallucinate, and in the narrow sense that's fair: a model that never emits free text can't invent a citation or a tool name. But llm hallucination and correctness aren't the same problem. A model constrained to three allowed categories can still confidently pick the wrong one — what's been eliminated is the malformed answer, not the mistaken judgment. Calibration is TypeSafe's answer to that, and calibration is exactly the claim that needs independent testing. Teams already using structured outputs with JSON schema will recognise the distinction: constraining the shape of an answer has never guaranteed the substance of it.
Set the specific launch aside for a moment, because the shape of it is more interesting than the numbers. What TypeSafe is arguing — and what a growing number of teams are arriving at independently — is that one general-purpose model answering every call is a prototyping pattern, not a production one.
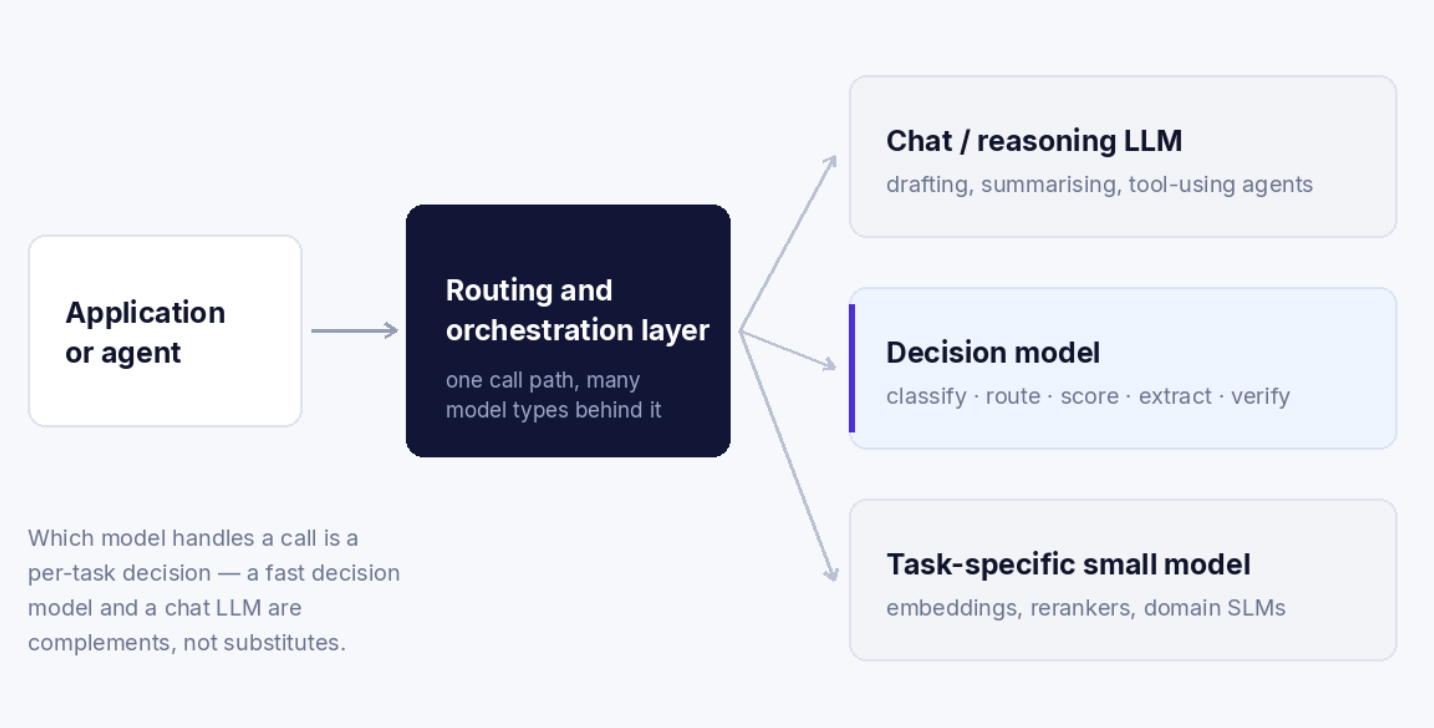
A production stack ends up holding several model types at once, with the routing layer deciding which one serves a given call.
The decisions inside a running system are mostly small and repetitive: is this ticket urgent, which queue does it belong in, does this response violate policy, which of these fields is the invoice number. Sending each of those to a frontier chat model works, and teams do it, but it means paying generation prices and generation latency for something closer to a lookup. That's the same calculus behind choosing when to specialise a small model instead of prompting a large one, and it's why verification-style work — scoring, judging, jailbreak detection, agent guardrails — is the use case TypeSafe leads with. Guardrails have to run on every call, which makes cost and latency the binding constraint rather than raw capability.
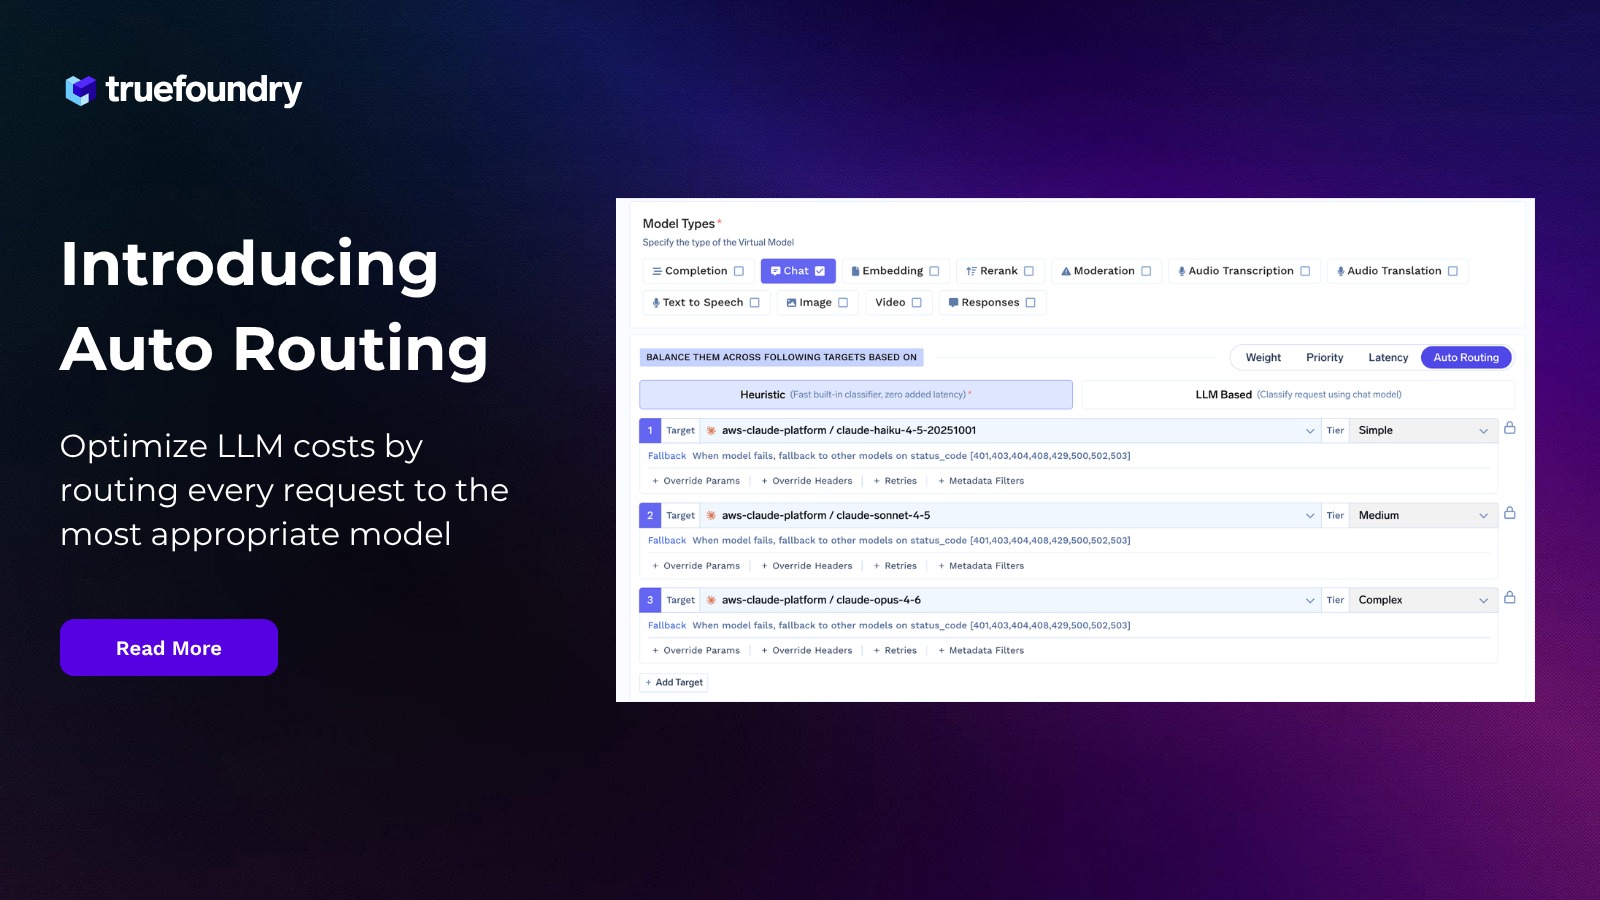
The consequence for anyone running AI in production is an ai orchestration problem rather than a model-selection one. If the right answer is a chat LLM for some calls, a fast decision model for others, and a fine-tuned small model for a third set, then the thing that has to be stable is the layer in front of them — one call path, consistent auth and logging, and the freedom to change which model serves a given task without rewriting the application. That's the premise behind auto-routing on the TrueFoundry AI Gateway, and it's the reason a launch like this one is more interesting as an architectural signal than as a benchmark.
For now, Jev is a closed hosted API in early access, so there's nothing to deploy and no integration to evaluate. That may change. The pattern it represents almost certainly will not.
TypeSafe AI's Jev is a genuinely different bet: that the useful next step isn't a smarter chat model but a dependable one that software can call like any other function. The design is coherent, the founder's track record is real, and the price and latency targets are aggressive enough to change what's worth automating. The benchmark multiples, though, are self-graded on a format the company invented, and the strongest claim in the post — calibration — is the one no outside party has tested yet. Both things can be true.
What the launch does confirm is a direction: production stacks are heading toward a mix of model types chosen per task, not a single model chosen per company. If that's the shape of your system, the layer worth getting right is the one in front of the models.
See how the TrueFoundry AI Gateway routes across model types →
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.




Jev is the first model in a class TypeSafe AI calls System One Models, launched in early access on September 15, 2026. Rather than generating text, it takes unstructured input plus a schema you define in advance and returns typed values with calibrated confidence scores. It's aimed at decisions made inside software — classification, routing, scoring, extraction — rather than at chat.
They're models built to make fast, structured decisions that software consumes directly, named after Daniel Kahneman's fast, intuitive System 1 thinking. The defining trade is giving up free-form text generation in exchange for parallel sampling, guaranteed schema conformance, and a probability attached to every answer.
It can't produce an answer outside the schema you defined, which rules out invented fields, malformed output, and fabricated tool names. It can still select the wrong value from the allowed set — that's an accuracy question, not a format one, and TypeSafe's response to it is calibrated confidence rather than a claim of infallibility.
No. It's a proprietary model served from TypeSafe's own hosted API, currently behind an early-access waitlist. There are no published weights and no on-prem option today.
1,000+ LLMs through a single OpenAI-compatible API. Switching models means changing the model name in the request — same URL, same credentials — which is what makes swapping in a new provider a configuration change rather than an integration project.
Roughly 3–4 ms of overhead, handling 350+ RPS on a single vCPU. That matters more as model calls get faster: a routing layer that adds hundreds of milliseconds would erase the advantage of a sub-second decision model.



The latest news, articles, and resources sent to your inbox