September 26, 2026
|
5 min read

Published: September 23, 2026

Blazingly fast way to build, track and deploy your models!
Choosing a large language model (LLM) has become much more complicated than it was a year or two ago. New models are released frequently, existing ones receive major upgrades, and each claims to offer better reasoning, faster responses, larger context windows, or lower costs. While having more options is a good thing, it also makes selecting the right model far more challenging.
The reality is that there isn't a single LLM that's best at everything. A model that performs exceptionally well at coding may not be the most cost-effective for customer support. Another might excel at reasoning but fall short when it comes to latency or tool calling. That's why relying only on benchmark scores or popularity isn't enough.
This is where LLM capabilities comparison becomes important. Instead of asking, "Which model is the best?" the better question is, "Which model is the best for my use case?"
In this guide, we'll discuss what LLM capabilities are, how you should compare them and why comparing them matters.
LLM capabilities are the individual abilities that determine what a large language model can do and how well it performs a task. While LLMs are designed to understand and generate language, their capabilities differ depending on how they are trained, the data used during training, and their underlying architecture.
An LLM capabilities comparison isn't just a technical exercise, it's a way to reduce risk before your application goes into production. It helps you validate whether a model can meet your functional requirements today and continue to support your application as it grows.
Instead of discovering limitations halfway through development, you can identify them early and make informed trade-offs.
Here's what a capability comparison helps you achieve:
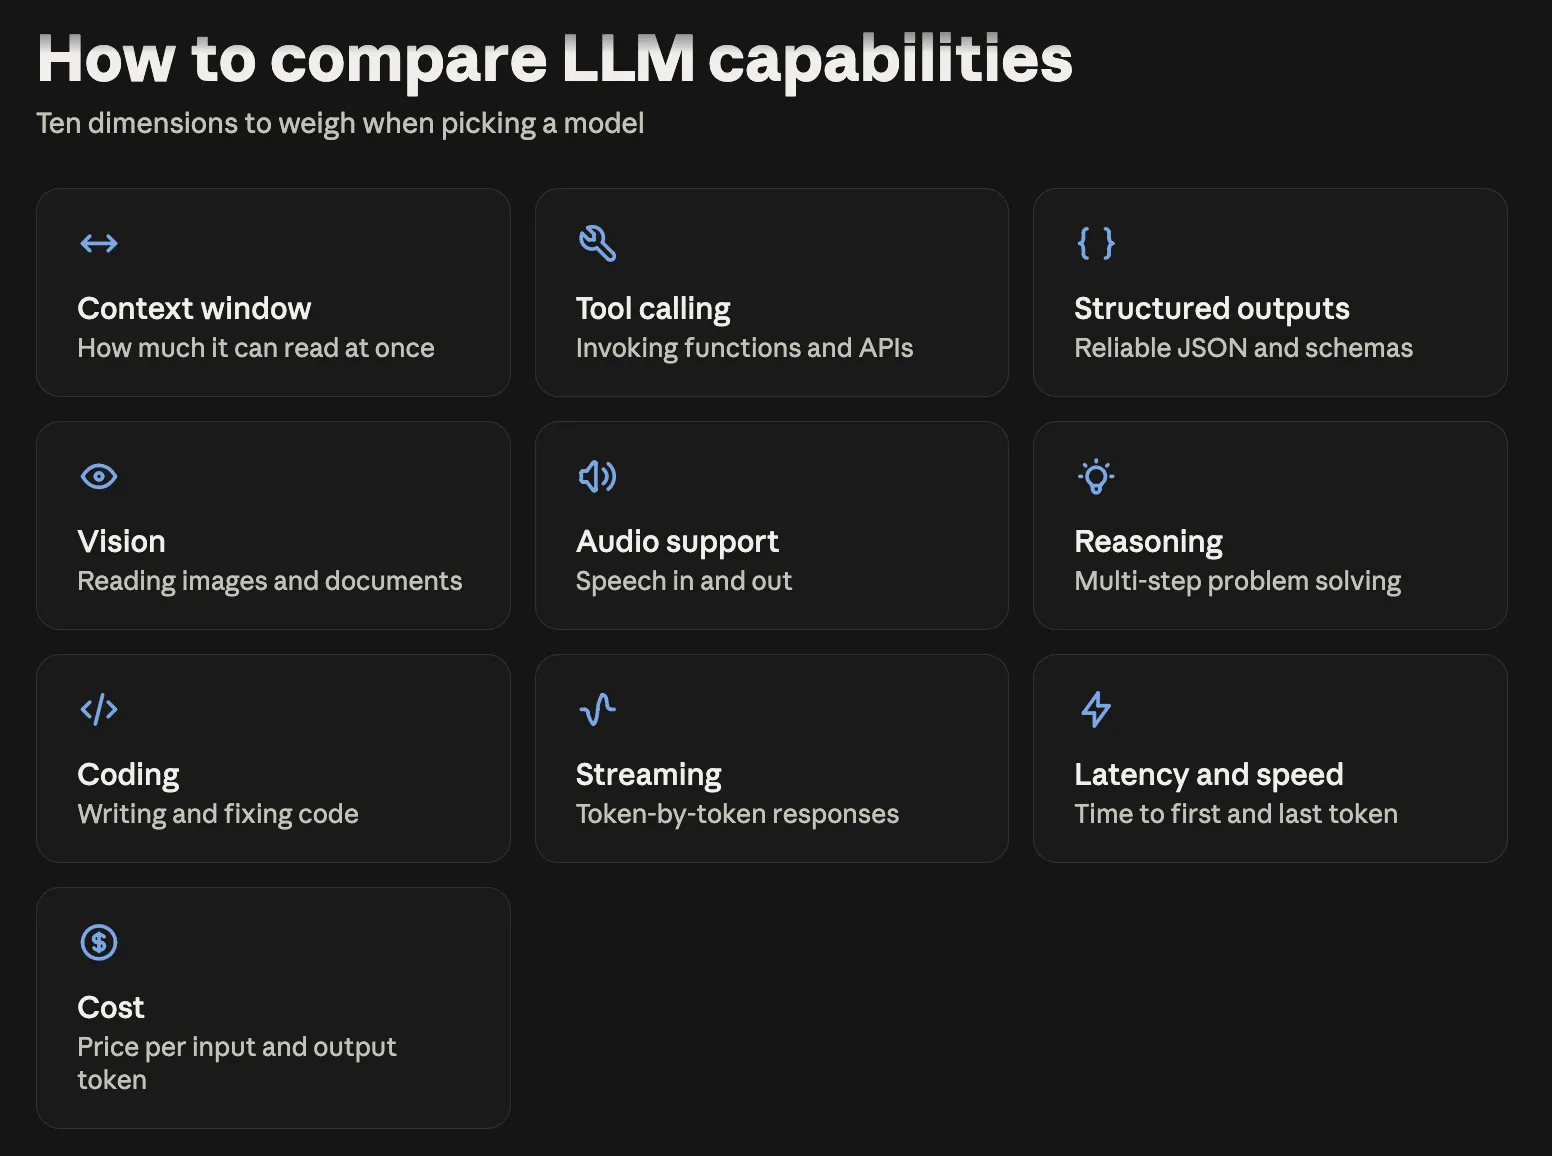
An effective LLM capabilities comparison focuses on the features that directly impact your application. Instead of relying only on benchmark scores, evaluate whether a model supports the capabilities your use case requires.
Compare the following capabilities to understand how well each model fits your application requirements:
A larger context window helps the model process long documents, conversations, or codebases in a single request. Compare both the supported context length and performance with larger inputs.
Tool calling enables LLMs to interact with APIs, databases, and other external systems. Evaluate how reliably a model executes these actions.
If your application depends on formats like JSON, compare how consistently models generate structured, schema-compliant responses.
Vision-enabled models can analyze images, PDFs, charts, and screenshots. Check the supported input types and the quality of visual understanding.
For voice-based applications, compare whether models support speech input, transcription, or audio generation.
Reasoning capability determines how well a model handles multi-step analysis, planning, and problem-solving. Test it using tasks similar to your real-world workflows.
If you're building developer tools, evaluate how well the model generates, explains, and debugs code across different languages.
Streaming returns responses as they're generated, improving responsiveness for chatbots and other real-time applications.
Low latency is essential for interactive experiences. Compare response times under realistic workloads instead of relying only on published numbers.
Consider token pricing alongside performance to determine whether a model is cost-effective for your expected usage.
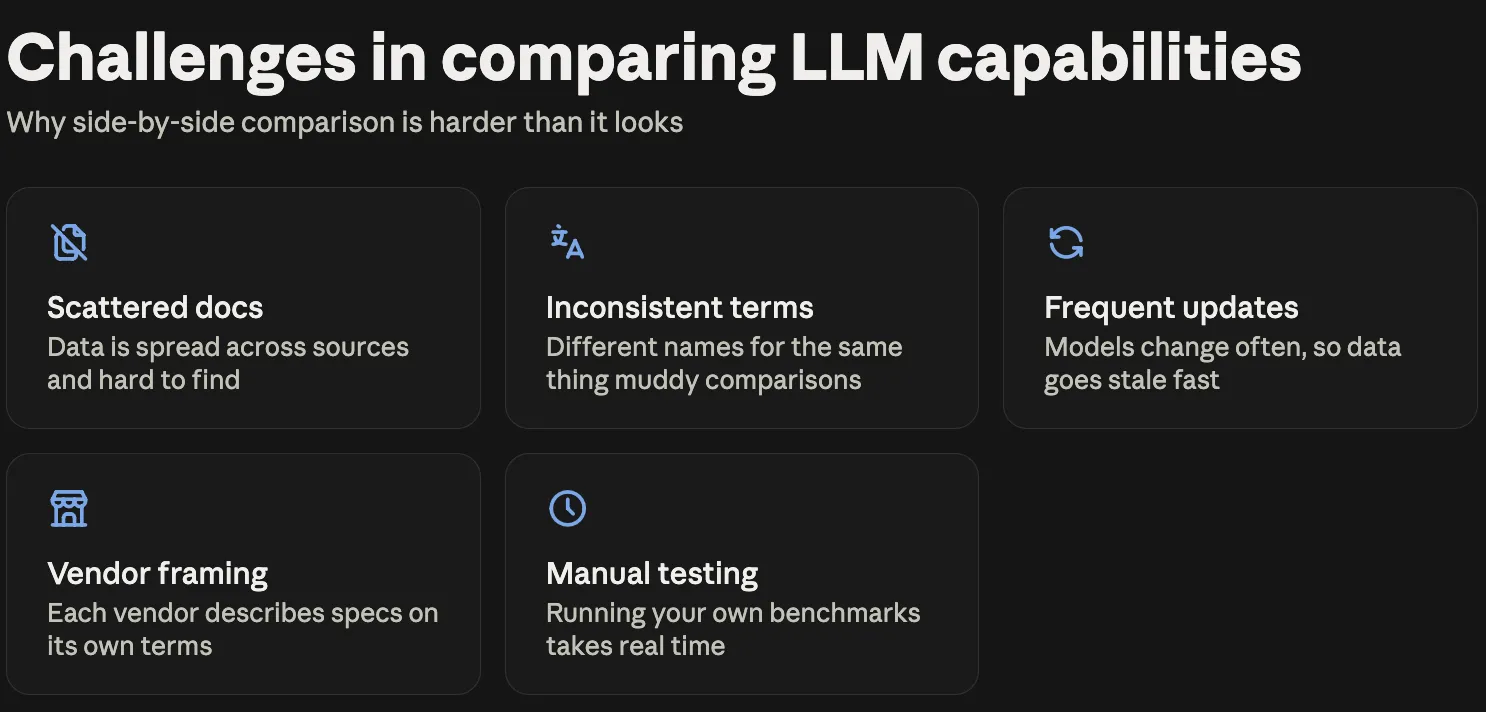
Evaluating LLM capabilities is harder than it seems. Different documentation standards and frequent model updates make accurate comparisons challenging.
Once you know which capabilities matter, you need an easy way to compare them across models. Instead of searching through documentation from different providers, you can use model profiles to get the information in one standardized format.
Think of a model profile as a capability card for an LLM. Instead of digging through documentation or making educated guesses about what a model supports, you can view its capabilities in a standardized format.
Model profiles include information such as context window, tool calling, structured outputs, vision support, audio capabilities, and other key features that matter during an LLM capabilities comparison. Because every model follows the same structure, it's much easier to compare providers side by side.
The data comes from models.dev, an open-source project that tracks capabilities across models from providers like OpenAI, Anthropic, Google, and others. These profiles are available through LangChain packages, giving developers a consistent way to access capability information in their code.
Imagine reading that a model supports vision, then building an image analysis feature around it. A few weeks later, you discover that vision support was only available in a preview release or required a specific API configuration. Suddenly, your implementation stops working, not because of a bug, but because of a capability mismatch.
Or maybe you're comparing five different models for a new project. You open documentation from multiple providers, create a spreadsheet, and try to figure out whether terms like tool calling, function calling, and API integration all refer to the same capability. Before long, comparing models takes more time than evaluating them.
Model profiles help avoid these situations. Instead of translating vendor-specific documentation, you get a standardized view of what each model supports. Your application can even check capabilities programmatically before using a feature, reducing surprises during development and making LLM capabilities comparison faster, more consistent, and more reliable.
Choosing an LLM often involves a lot of back-and-forth between documentation pages. Model profiles simplify this by giving developers a quick view of what each model can do.
Choosing an LLM often starts with a long list of questions: Does it support tool calling? How much context can it handle? Can it process images? Finding these answers across multiple providers can take significant time.
With model profiles, developers can quickly filter models based on the capabilities they need. For example, a team building a customer support bot can check which models support tool calling for order lookups and have enough context capacity for ongoing conversations. This allows them to spend more time testing model performance rather than verifying basic capabilities.
Modern applications often use multiple models for different tasks. One model may handle complex reasoning, while another manages simpler requests at a lower cost.
Model profiles allow applications to check whether a model supports the required capabilities before sending requests. This makes it easier to build systems that can switch between models when needed and handle changes without unexpected failures.
Many teams default to using the most powerful model because it's reliable and familiar. However, not every task requires the highest-capability model.
By comparing model profiles, developers can identify smaller or more cost-efficient models that still support the features their application needs. This helps teams optimize costs while maintaining the performance required for different workloads.
Model profiles are useful not only for developers writing code but also for teams making decisions about AI adoption. By providing a standardized view of model capabilities, they help engineering teams build more reliable applications and help product teams evaluate options faster.
Model profiles make LLM comparison easier, but they are not the final answer. They show what a model supports, but you still need to evaluate performance, cost, and suitability for your specific use case.
Keep the following limitations in mind when using model profiles for comparison:
A structured approach makes LLM comparison more effective. Instead of choosing a model based on popularity or benchmark scores alone, focus on how well it fits your application needs. The following practices can help you evaluate models against those requirements:
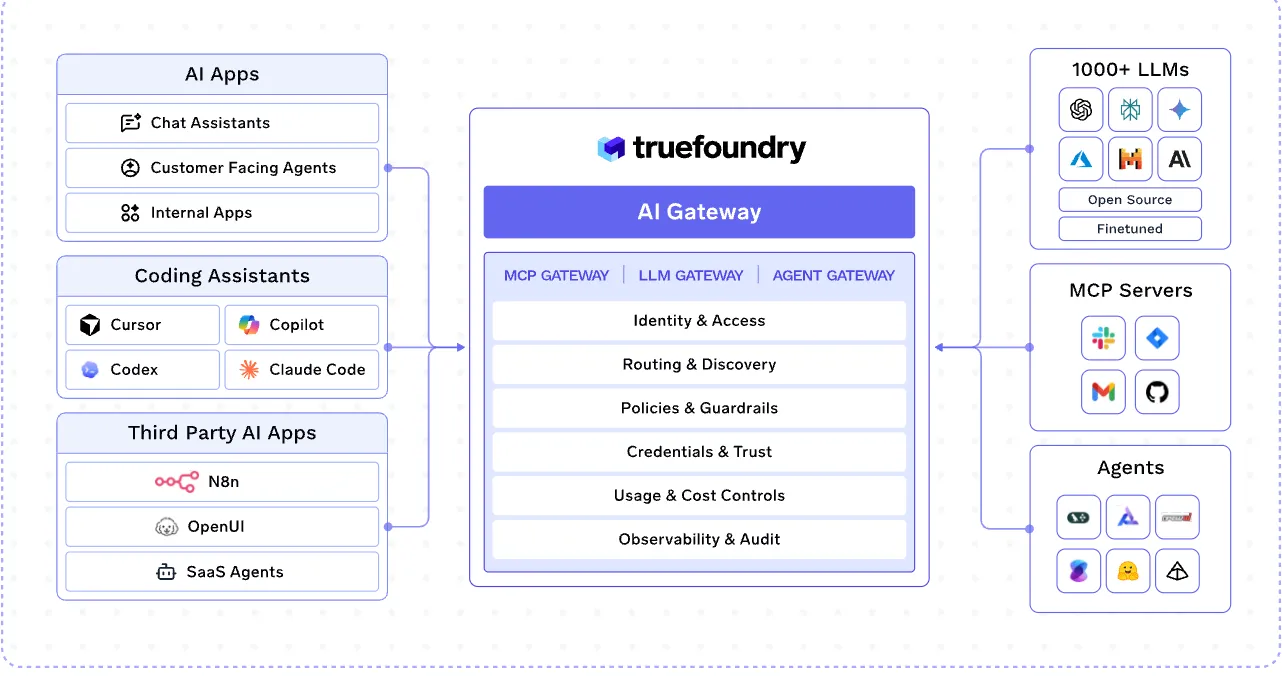
Comparing LLMs manually can quickly turn into a time-consuming process. You have to check different provider websites, understand varying feature descriptions, and create your own comparison framework before making a decision.
TrueFoundry's Model Comparison app simplifies this process by bringing LLM capabilities into one standardized view. Powered by TrueFoundry AI Gateway, it allows you to compare models from providers like OpenAI, Anthropic, and Google across important capabilities such as context window, tool calling, vision support, and structured outputs.
With the tool, you can:
Instead of maintaining your own comparison spreadsheets, use the Model Comparison app to shortlist models by the capabilities your application actually needs.
The LLM landscape is changing faster than ever, and the way we evaluate models needs to evolve with it. A model that works well for one workflow may not deliver the same results for another, which makes flexibility and continuous evaluation important for long-term AI success.
Instead of chasing the latest model release, focus on building AI systems that can adapt as new capabilities, providers, and use cases emerge. The right LLM choice is ultimately the one that supports your goals, fits your operational needs, and delivers consistent value over time.
Ready to narrow down your model options? Try the Model Comparison app to compare LLM capabilities across providers in one standardized view.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.




For enterprises, important LLM capabilities include reasoning, tool calling, structured outputs, security, context handling, multimodal support, scalability, and cost efficiency. These capabilities help organizations build reliable AI applications for automation, customer support, data analysis, and workflow optimization.
LLM capabilities describe what a model supports, such as tool calling, vision, structured outputs, or a particular context window. Benchmarks measure how well a model performs on specific tasks or evaluations. Teams should consider both capability support and real-world performance when comparing models.
Key LLM capabilities include text generation, reasoning, coding, summarization, translation, context understanding, vision support, audio processing, tool calling, and structured outputs. These abilities determine how effectively a model can handle different tasks across various applications.
Organizations measure LLM capabilities using benchmarks, task-specific evaluations, human feedback, accuracy tests, latency measurements, and cost analysis. Many teams also test models with real-world prompts and workflows to understand performance in their specific business scenarios.



The latest news, articles, and resources sent to your inbox