


What Is a Mixture of Experts Model and How Does It Work?


Govern, Deploy and Trace AI in Your Own Infrastructure
Frequently Asked Questions
What is a Mixture of Experts model in simple terms?
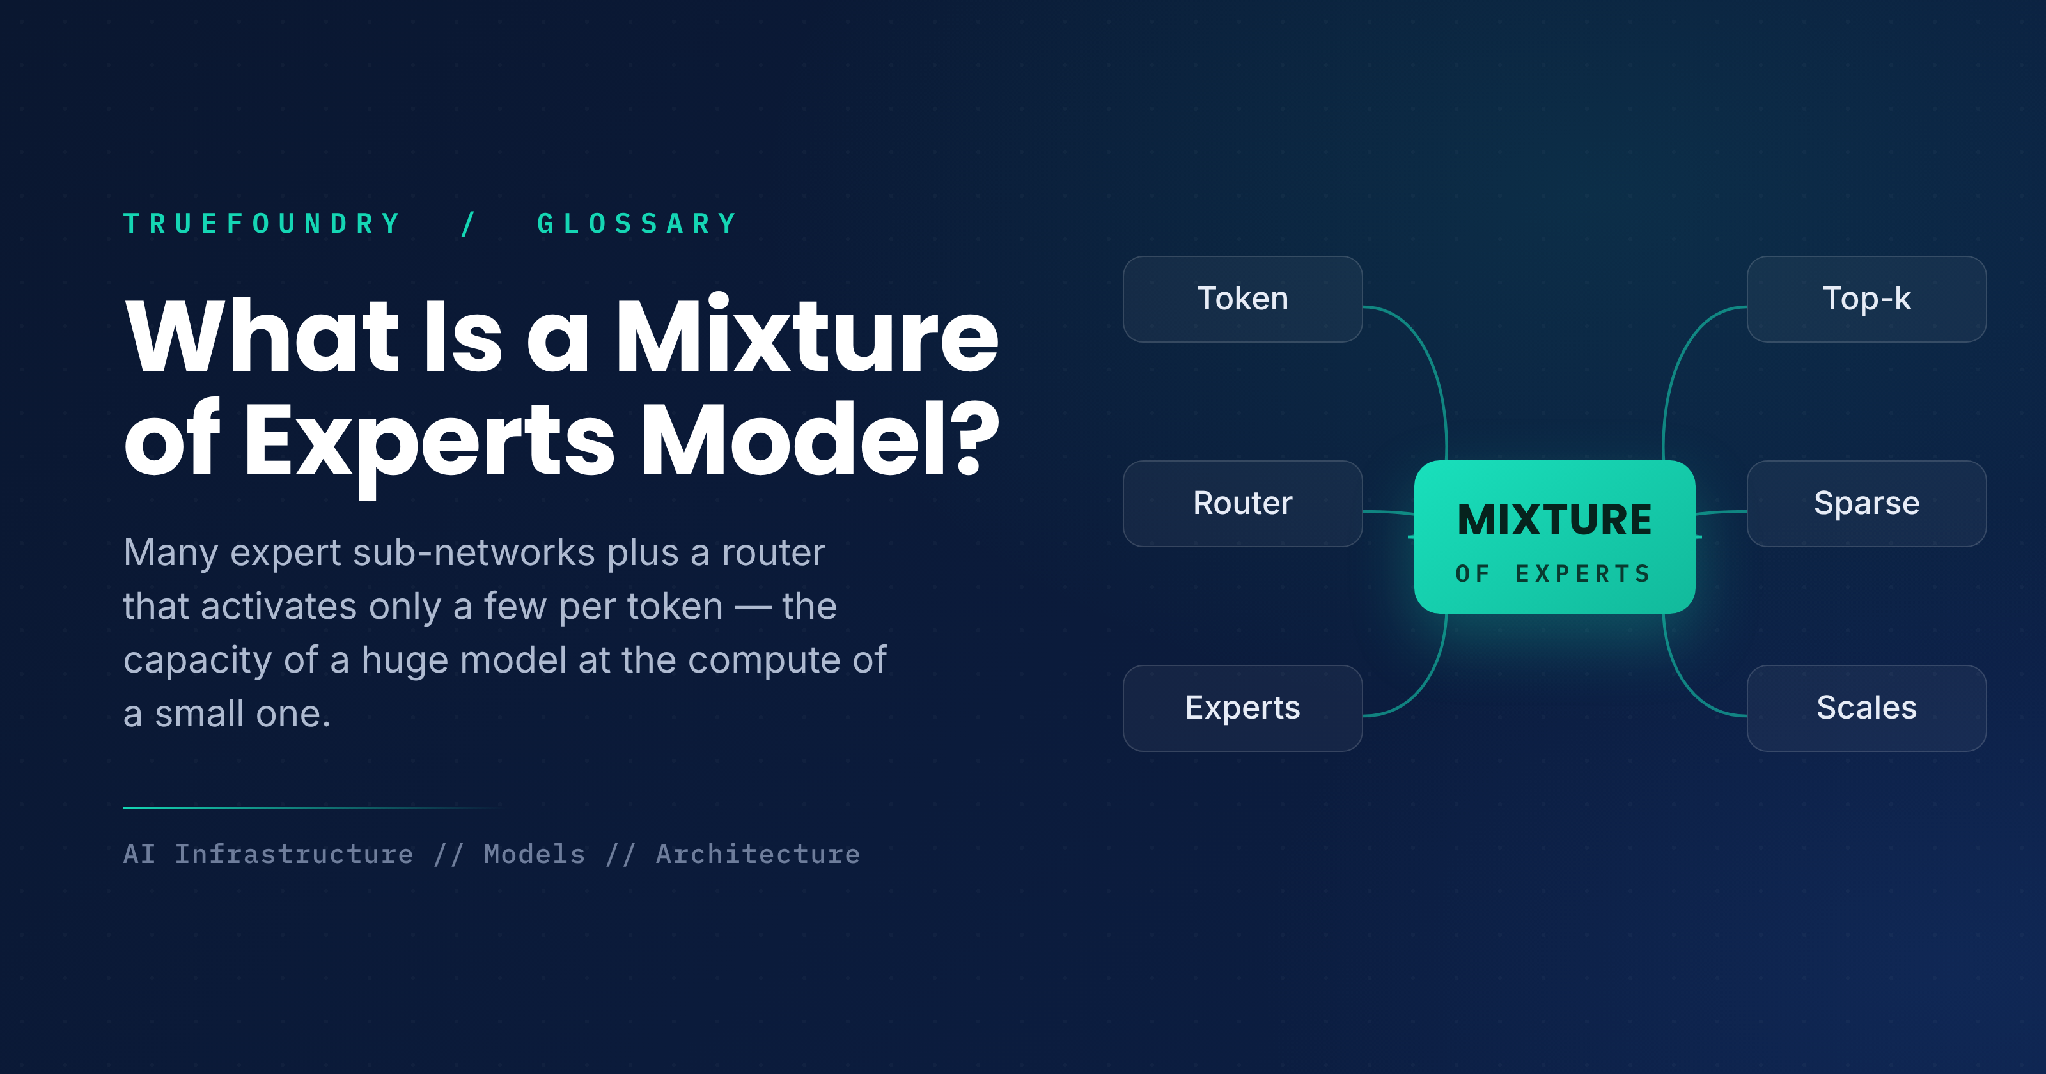
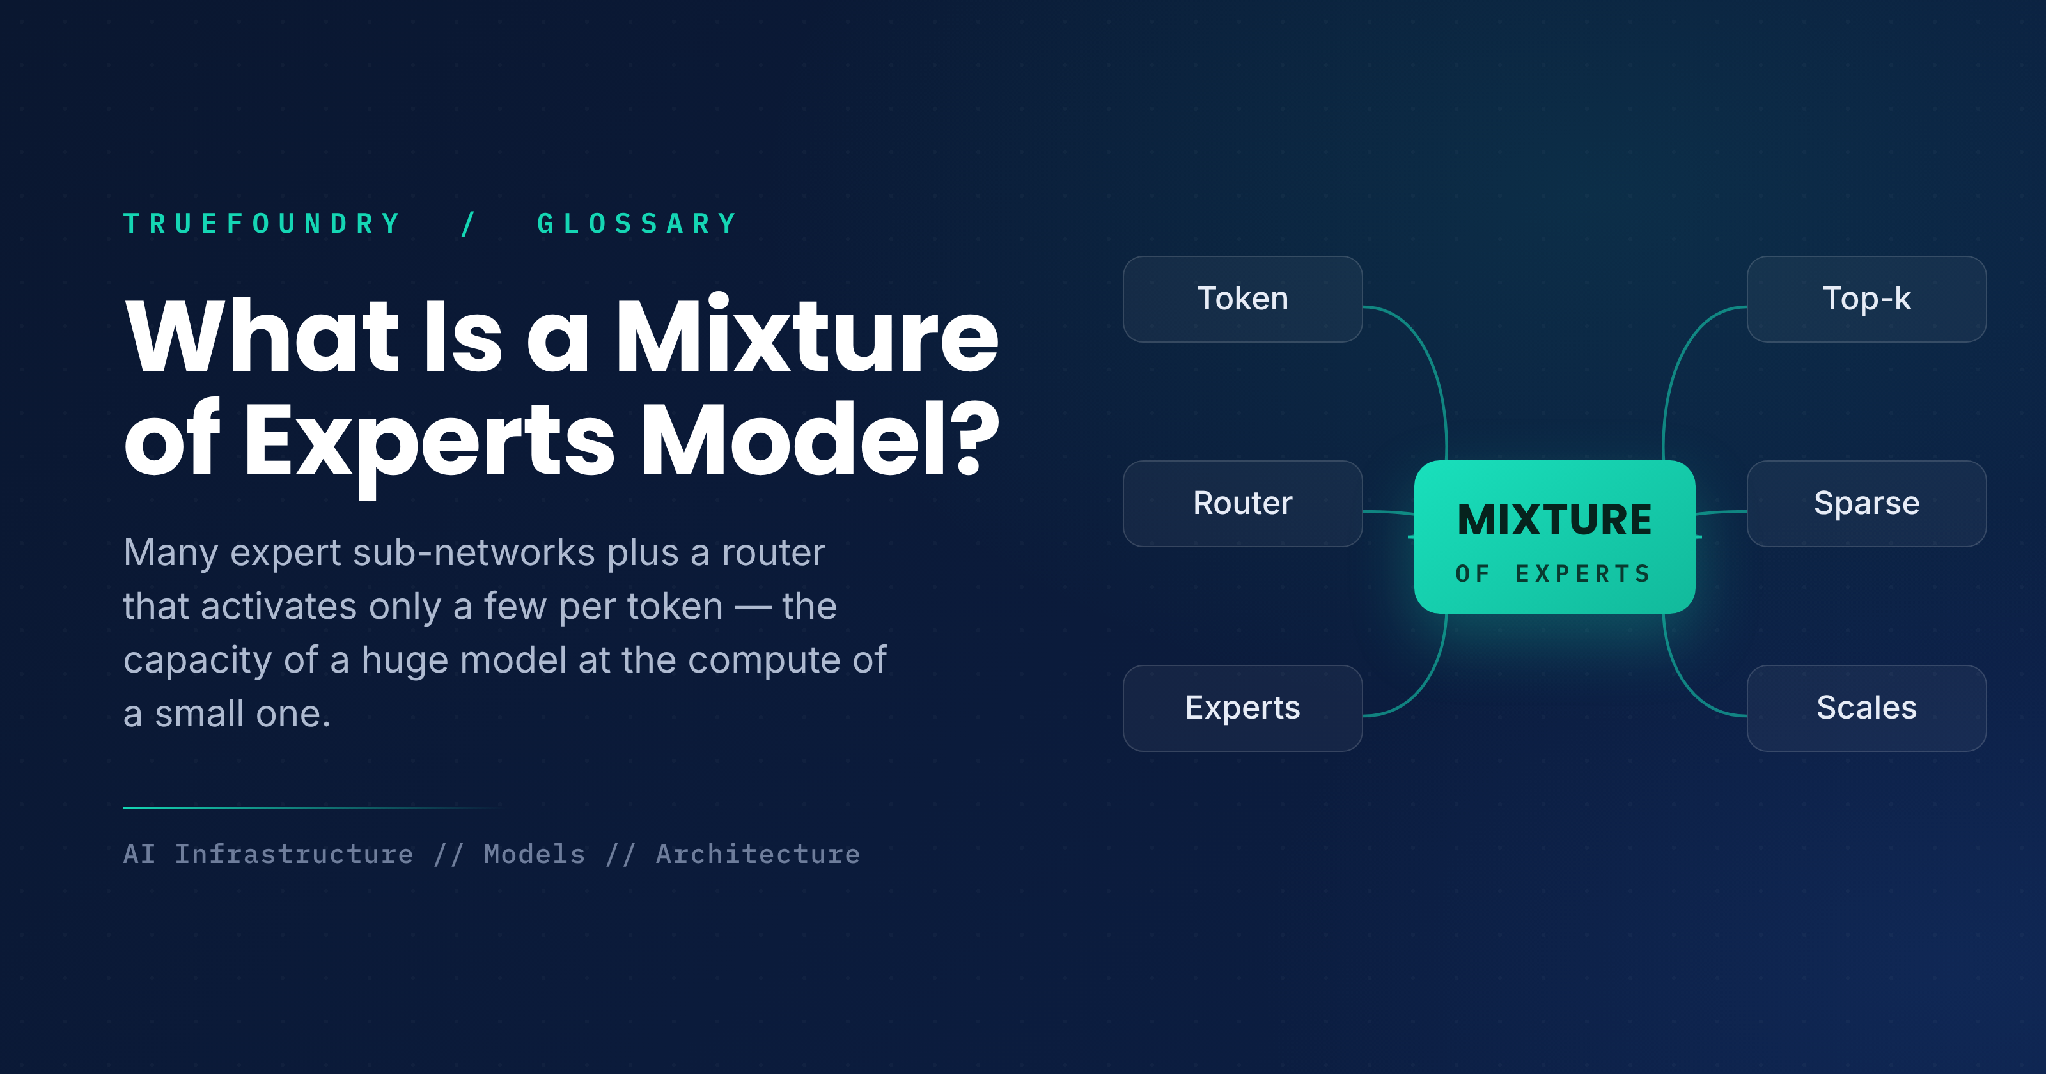
The model is constructed using a number of expert networks and a router. The router selects only a few experts for each token, so while the model has extremely high capacity overall, it actually uses only a fraction of that capacity at any one point.
What does the router do?
The router, or gating network, ranks how well each expert suits a given token and chooses a few of the most suitable ones to run. This is why the model is sparse: tokens are assigned only to the experts best suited to them.
How is MoE different from a dense model?
In a dense setup, each parameter is used for each token. In the MoE architecture, only a couple of experts are used for each token, making it possible to hold far more parameters without much more compute per token.
What is the main downside of MoE?
Memory. While only a small number of experts run per token, all of them have to be loaded, so MoE models require a huge amount of memory for their size. Routing also adds complexity to training and serving.
Why do frontier models use MoE?
Because it allows them to scale quality and parameters without a matching increase in compute per token. That makes very large models feasible to serve, which is why many leading models use this architecture.





