



October 10, 2026
|
5 min read


احصل على وصول فوري إلى بيئة TrueFoundry مباشرة. انشر النماذج، ووجّه حركة مرور LLM، واستكشف المنصة بالكامل — بيئة الاختبار الخاصة بك جاهزة في ثوانٍ، ولا يلزم وجود بطاقة ائتمان.



Published: October 10, 2026
Blazingly fast way to build, track and deploy your models!
Prompt engineering techniques help teams write better instructions for language models, improve output quality, and reduce avoidable errors. OpenAI describes prompt engineering as writing effective instructions so models produce content that meets requirements. Anthropic notes that prompt engineering works best when success criteria are controllable through prompting.
For enterprise teams, prompt engineering is no longer a personal productivity skill. It now affects model cost, latency, reliability, compliance, and user experience. A prompt that adds three sentences of reasoning can double token spend across a million-request month. A prompt that grants an agent unsafe access to tools can constitute an access control incident.
This guide explains the most useful prompt engineering methods, when to apply each, and where prompt-level discipline must connect with AI gateway governance. It also explains how TrueFoundry helps teams govern prompts, models, MCP tools, budgets, and agents in production.
Prompt engineering is the practice of designing LLM prompts to produce reliable, accurate, and appropriately formatted AI outputs. It is the main interface between human intent and AI model behavior. The quality of that interface directly affects application reliability, cost, safety, and usefulness across different tasks.
The discipline has expanded from writing concise instructions for a simple question to building prompt architectures for agentic workflows. A modern prompt may include input variables, structured output rules, additional context, model settings, guardrails, and policy requirements for production use.
The practical implication is clear. Teams that treat prompts as disposable text often ship lower-quality AI applications. Teams that apply systematic prompt engineering techniques with versioning, evaluation, and governance have a stronger path to accurate responses and better results.
TrueFoundry’s Prompt Management reflects that shift. A saved prompt stores the system message, user message, input variables, guardrails, and structured output configuration in one versioned object. Applications can reference it by a fully qualified name instead of embedding the prompt text.
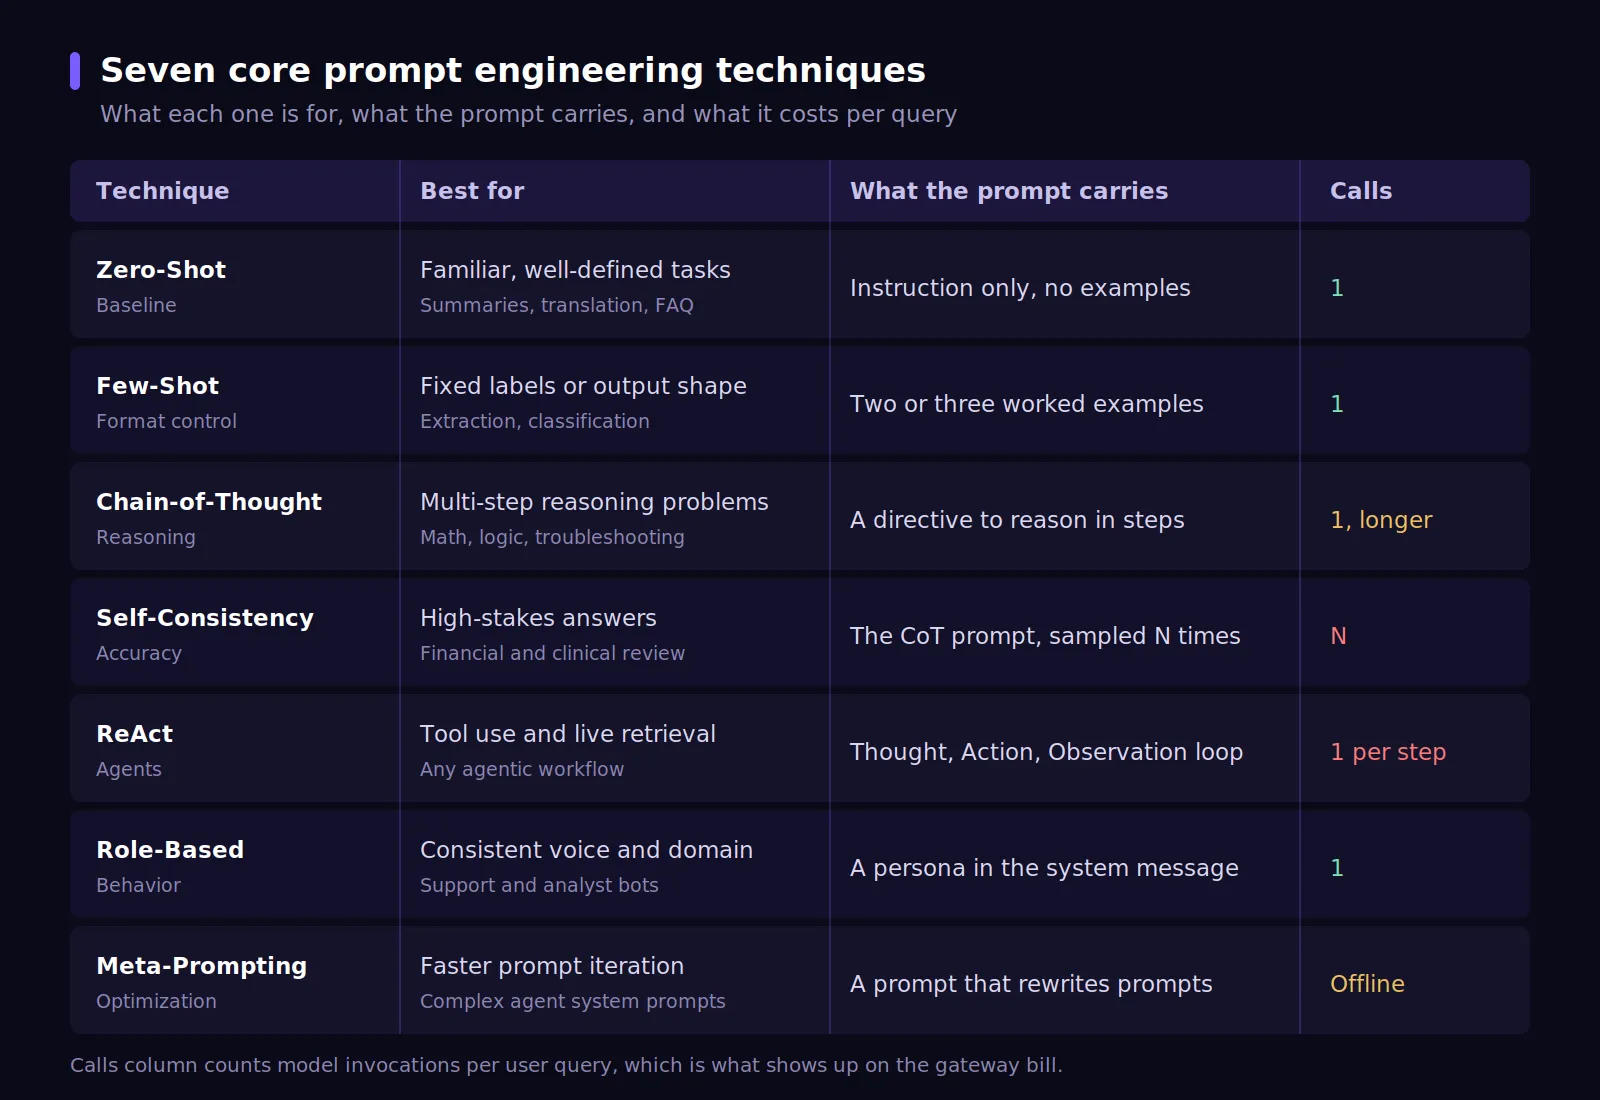
Seven core prompt engineering techniques cover most production work. Read them as a progression. Each one buys accuracy, structure, or control. Each one also charges teams in terms of tokens, latency, maintenance effort, or governance complexity.
Zero-shot prompting asks the large language model to complete a specific task without examples. The model relies on training data and common sense to infer the correct response format, content, and tone from the instruction alone.
Best for: Well-defined tasks where the model already understands the pattern. Examples include summarization, translation, simple classification, FAQ answering, and extracting relevant facts from short inputs.
Limitation: Zero-shot reliability drops when the desired task requires strict formatting or domain-specific behavior. The failure is often quiet. A zero-shot classifier returns a plausible label rather than an error, so the defect appears later as poor analytics or reduced user satisfaction.
Few-shot prompting provides one or more input-output examples before the actual request. These detailed examples give the model a concrete pattern to follow, especially when the desired output requires a specific tone, schema, label set, or writing structure.
Best for: Tasks where output shape matters. Use it for classification with fixed labels, structured data extraction, style matching, domain-specific tone, and repeatable format requirements.
How many examples: Two or three examples often perform well for many production tasks. More examples can improve prompt quality, although every request pays for those tokens. Teams should measure the tradeoff before using longer prompts on high-volume endpoints.
Chain-of-thought prompting asks the model to reason through intermediate steps before producing the final answer. It can improve performance on a math problem, a logic task, a troubleshooting workflow, or a coding problem where intermediate reasoning affects the result.
Best for: Complex reasoning, decision trees, technical diagnosis, financial analysis, and complex reasoning tasks. It works best when the prompt asks for deliberate problem solving rather than a short response.
Zero-shot CoT: Adding a step-by-step reasoning instruction can activate chain of thought behavior without providing example reasoning chains. This remains a low-effort way to improve reasoning on complex tasks.
Combining with few-shot: Few-shot examples that include reasoning paths can improve performance for domain-specific workflows. Teams should keep the displayed answer concise when users only need the final answer.
One operational caveat matters here. Chain-of-thought output is long, and long output is exactly what teams stream to keep perceived latency low. TrueFoundry's guardrails documentation states that output guardrails are skipped when a request sets `stream: true`, because there is no complete response to evaluate. Reasoning you stream is reasoning no output policy inspects.
Self-consistency extends chain-of-thought prompting by generating multiple independent reasoning chains for the same question. The system then selects the most consistent final answer across the samples.
Best for: High-stakes reasoning where answer accuracy matters more than inference cost. Examples include risk reviews, legal reasoning support, financial analysis, case studies, and safety-sensitive recommendations.
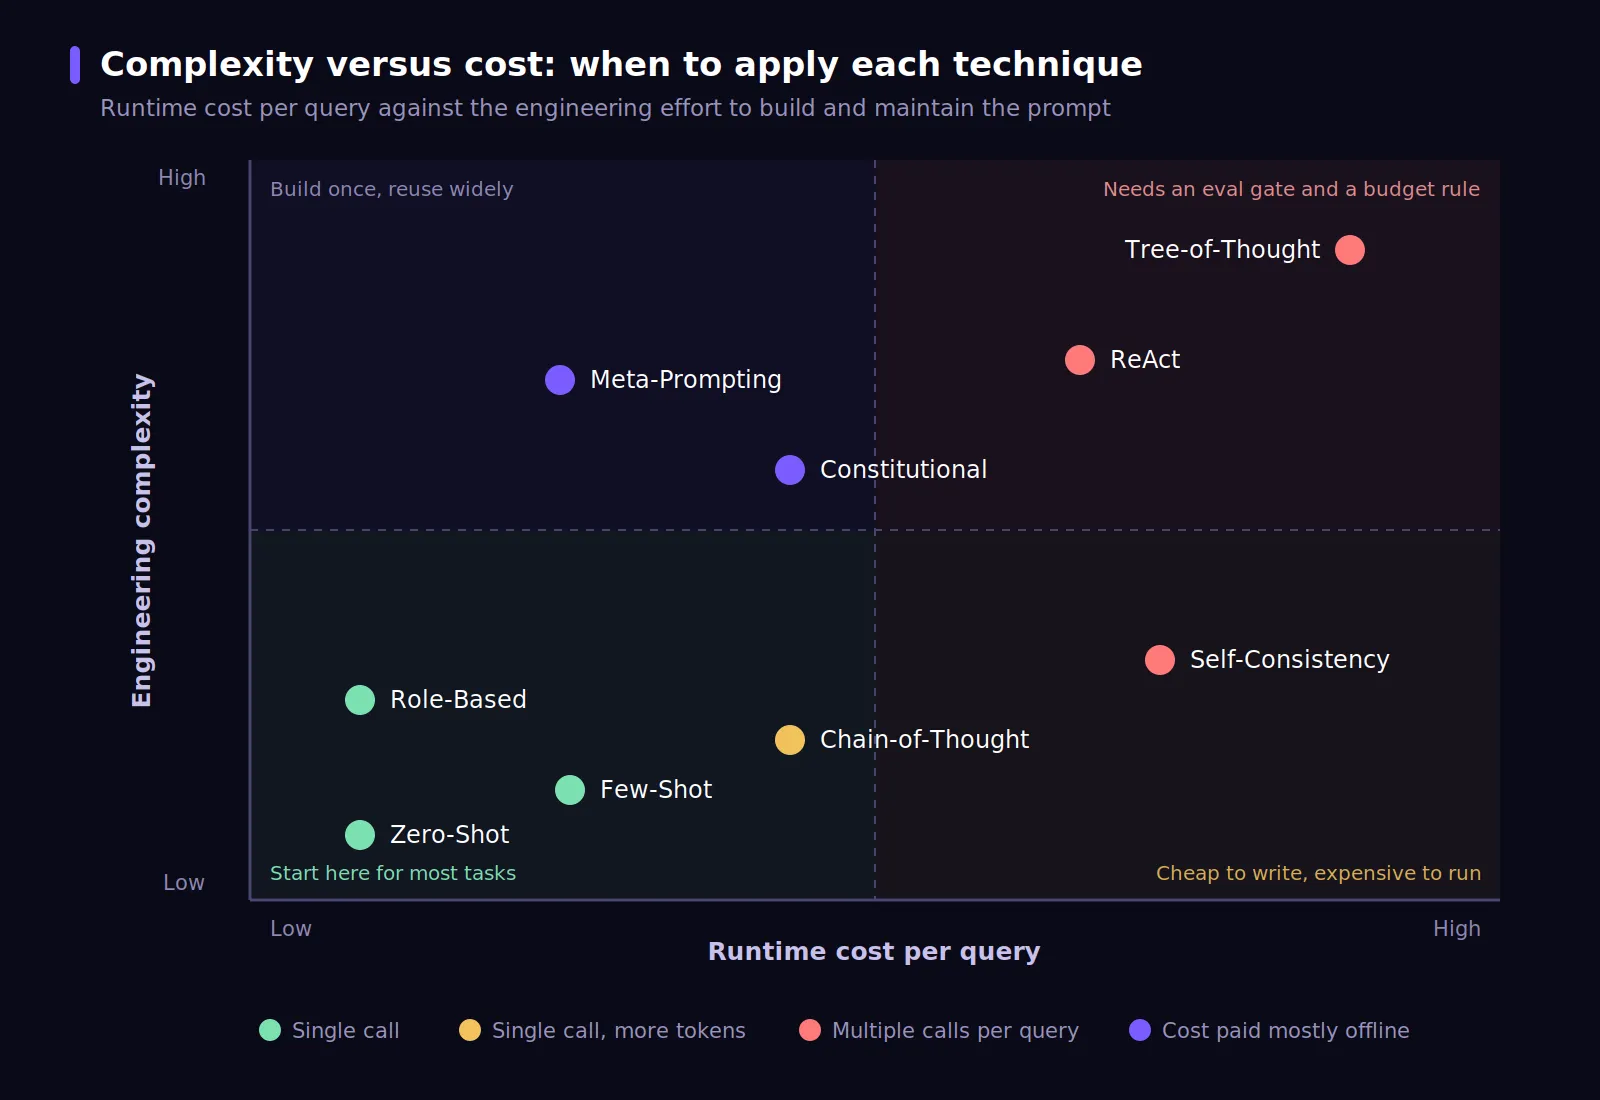
Cost tradeoff: Self-consistency requires multiple model calls per query. Five sampled chains turn one billable request into five. Per-team budget enforcement through an AI Gateway is essential when teams apply this method at scale.
ReAct prompting combines reasoning and acting. The model alternates between a Thought step, an Action step, and an Observation step. This pattern lets the model reason, call external tools, read the result, and continue until the task is complete.
Best for: Agentic workflows that require information retrieval, tool execution, real-time context, or multi-step task completion. ReAct is useful when an AI assistant must interact with databases, APIs, SaaS tools, or internal systems.
ReAct changes the security question. The prompt no longer shapes text alone. It also influences tool selection and action sequencing. When tools interact with business systems, the MCP Gateway serves as the enforcement layer for permissions, validation, and audit logging.
Role-based prompting assigns the model a specific persona, expertise domain, or behavioral context at the system prompt level. "You are a senior financial analyst reviewing a client portfolio" produces different reasoning patterns and output styles than the same question without role assignment.
Best for: Domain-specific applications, customer service agents with defined personas, technical support bots, and any application where consistent voice and behavioral context matter across all interactions.
Enterprise application: Role-based system prompts are a primary mechanism for enforcing behavioral guardrails at the application level, before output filtering is applied at the infrastructure layer.
Note a boundary that surprises most teams. TrueFoundry's guardrails documentation confirms that system prompts are excluded from guardrail evaluation by default, so the role definition itself is never inspected, blocked, or redacted. Persona instructions shape behavior, and they do not act as a policy that the infrastructure verifies.
Meta-prompting uses the LLM to analyze, critique, and improve prompts rather than directly completing end-user tasks. A prompt engineer can use it to generate candidates, compare common patterns, and refine instructions in less time.
Best for: Teams that iterate frequently on prompt design and want to accelerate optimization. It is useful for complex activities, strategic planning, and agent system prompts with many key elements.
Production note: Meta-prompting generates candidate prompts that still require evaluation against a test set before promotion to production. It accelerates the candidate generation step, not the validation step.
A systematic prompt-enhancement workflow keeps that distinction honest by scoring candidates against a fixed eval set rather than a reviewer's impression.
The advanced techniques below trade more compute or design effort for gains on problems that simpler techniques handle poorly. Use them when an evaluation set proves the simpler method has plateaued.
Tree-of-Thought extends linear chain-of-thought prompting into a branching structure. The model explores multiple reasoning paths, evaluates potential solutions, and selects the most promising branch to continue.
Best for: Problems where the solution path is not obvious from the initial statement. Examples include research synthesis, creative work such as a short story, strategy development, complex debugging, and open-ended planning.
Tree-of-Thought can improve results on difficult reasoning tasks. It also scales cost through branching factor and depth. This makes budget caps important before the technique reaches customer-facing endpoints.
Constitutional prompting embeds a set of principles into the system prompt. The model uses those principles to self-evaluate and revise its own response before returning an answer.
Best for: AI applications where consistent alignment with organizational values, safety rules, or compliance standards matters. It can help guide behavior before post-generation filtering runs.
Treat the constitution as quality control, not audit control. The principles live inside the system prompt. Compliance evidence should come from guardrails, traces, policy outcomes, and logs that the model cannot influence.
Directional stimulus prompting adds a brief hint, keyword, or guiding signal to steer the model toward the most relevant information. It can help when the base prompt is clear, yet the model needs a stronger cue about what matters.
Best for: Classification, summarization, and extraction tasks where a small directional cue improves focus. For example, a climate change summary may use a stimulus such as “policy impacts” to guide attention.
This is an advanced technique because small cues can shift the answer unexpectedly. Teams should compare performance against a baseline and confirm that the stimulus improves the desired output without harming other cases.
Individual prompt engineering methods work differently in controlled tests than in production environments with real users. Several operational realities affect which techniques remain viable once traffic, cost, risk, and governance increase.
TrueFoundry's built-in prompt injection guardrail runs in validate mode only, and it analyzes the user prompt and any document or context content as two separate surfaces. Splitting the analysis matters because indirect injection occurs within retrieved documents rather than in the user's own message.
تحدد تقنيات هندسة الأوامر مدى كفاءة النموذج اللغوي الكبير (LLM) في فهم المهام وتنفيذها، بينما تحدد طبقة الحوكمة ما إذا كان هذا التنفيذ يتم بأمان، وضمن حدود التكلفة، ومع توفر عناصر التحكم في الوصول وأدلة التدقيق التي تتطلبها بيئات العمل المؤسسية.
تطبق بوابة الذكاء الاصطناعي (AI Gateway) من TrueFoundry عمليات تصفية للمدخلات قبل وصول الأوامر إلى أي نموذج، مما يتيح اعتراض محاولات حقن الأوامر (prompt injection) بغض النظر عن مدى تعقيد أساليب هندسة الأوامر المستخدمة في النظام. كما تعمل حواجز الحماية للمخرجات على تطبيق سياسات المحتوى قبل عودة الاستجابات إلى التطبيقات، مما يكمل -ولا يستبدل- الأوامر الدستورية (constitutional prompting) على مستوى النموذج.
يتطلب نموذج التنفيذ قراءة متأنية؛ حيث تعمل حواجز حماية التحقق من المدخلات بالتوازي مع طلب النموذج، وعند فشل التحقق أثناء المعالجة، تقوم البوابة بإلغاء طلب النموذج حتى لا يتم احتساب تكلفة الأمر المحظور. أما حواجز حماية تعديل المدخلات، مثل تنقيح معلومات التعريف الشخصية (PII)، فتعمل قبل إرسال الطلب لأنها تقوم بإعادة صياغة البيانات التي يتلقاها النموذج.
يتم تسجيل كل حاجز حماية في تتبع الطلب كخطوة مستقلة تتضمن زمن الاستجابة، والقرار المتخذ، والنطاق، والكيان الذي طُبق عليه. يتبع الطرح العملي الأدلة المتاحة: ابدأ بتفعيل القواعد في وضع التدقيق (Audit)، ثم انتقل إلى وضع التنفيذ (Enforce) مع تجاهل الأخطاء (But Ignore On Error)، وأخيراً انتقل إلى التنفيذ الكامل بمجرد التأكد من دقة النتائج.
يمكن ربط حواجز الحماية بكل طلب عبر ترويسة `X-TFY-GUARDRAILS`، أو مركزياً كسياسات ضمن AI Gateway → Controls → Guardrails لضمان تطبيقها على مستوى المؤسسة بالكامل.
{
  "llm_input_guardrails": ["my-group/prompt-injection"],
  "llm_output_guardrails": ["my-group/secrets-detection"],
  "mcp_tool_pre_invoke_guardrails": ["my-group/sql-sanitizer"],
  "mcp_tool_post_invoke_guardrails": ["my-group/code-safety"]
}
ميزانيات الرموز (tokens) المخصصة لكل فريق والتي يتم فرضها من خلال بوابة النماذج اللغوية الكبيرة (LLM gateway) تمنع تجاوز التكاليف الذي قد ينتج عن تقنيات الاتساق الذاتي (self-consistency) وشجرة الأفكار (tree-of-thought) عند استخدامها على نطاق واسع في غياب حوكمة التكاليف. قواعد تحديد معدل الاستخدام (Rate limiting rules) تقبل وحدات الرموز (tokens) ووحدات الطلبات، كما يقوم المعامل `rate_limit_applies_per` بإنشاء عداد مستقل لكل مستخدم، أو لكل نموذج، أو لكل مفتاح بيانات وصفية (metadata key).
name: ratelimiting-config
type: gateway-rate-limiting-config
rules:
  # Cap the reasoning-heavy service that runs self-consistency
  - id: "reasoning-service-hourly"
    when:
      metadata:
        service: "risk-analysis"
    limit_to: 200000
    unit: tokens_per_hour

  # Give every user an independent daily token ceiling
  - id: "user-daily-limit"
    when: {}
    limit_to: 1000000
    unit: tokens_per_day
    rate_limit_applies_per: ['user']
تضيف قواعد الميزانية سقفاً مالياً بالدولار لكل مستخدم، أو فريق، أو نموذج، أو حساب افتراضي، أو مفتاح بيانات وصفية. وتساعد تنبيهات المعالم الرئيسية ووضع التدقيق الفرق على معايرة الحدود قبل أن يبدأ النظام في حظر حركة البيانات.
يمكن للتطبيقات استدعاء أمر مُحوكم باستخدام الإصدار FQN بدلاً من إرسال النص مع التطبيق، مما يبقي تعديلات الأوامر خارج دورة الإصدار. حيث تقوم البوابة بمعالجة القالب وتنفيذ الاستدعاء.
from openai import OpenAI

client = OpenAI(
    api_key="your-tfy-api-key",
    base_url="{GATEWAY_BASE_URL}"
)

response = client.chat.completions.create(
    messages=[],
    model="",
    extra_headers={
        "X-TFY-METADATA": '{"service":"risk-analysis","env":"production"}',
    },
    extra_body={
        "prompt_version_fqn": "chat_prompt:truefoundry/default/cot-risk-review:3",
        "prompt_variables": {
            "portfolio_id": "PF-4471",
            "review_window": "Q3"
        }
    },
)

print(response.choices[0].message.content)
هناك تفصيلان في هذا الاستدعاء يحملان أهمية كبيرة؛ فربط الإصدار يعني أن التراجع عن أمر ما لا يتطلب إعادة نشر التطبيق، وترويسة `X-TFY-METADATA` هي ما يجعل ميزانيات الخدمات الفردية، وحدود الاستخدام، و تخصيص التكاليف ترتبط بمالك حقيقي.
تقوم بوابة الوكلاء (Agent Gateway) بحوكمة كل استدعاء للأدوات يقوم به الوكلاء المعتمدون على تقنية ReAct، بحيث تظل خطوات التفكير والتنفيذ خاضعة للحوكمة بشكل مستقل، ويحمل كل استدعاء للأداة سياق هوية المستخدم في سجلاته.
توفر بوابة MCP خطافات ما قبل الاستدعاء وما بعده لفرض ذلك، وتقوم حواجز الحماية بتقييم كل استدعاء للأداة على حدة بدلاً من تقييمه مرة واحدة لكل محادثة. فالوكيل الذي يستدعي خمس أدوات بالتسلسل يخضع لخمس مجموعات من عمليات التحقق.
تعمل خطافات ما قبل الاستدعاء على إيقاف الإجراء قبل تشغيله، وتغطي التحقق من صحة المعلمات، وتنقية لغة SQL، وفحوصات الأذونات المكتوبة كسياسات Cedar أو OPA. أما خطافات ما بعد الاستدعاء فتقوم بفحص مخرجات الأداة، مما يساهم في اكتشاف الحقن غير المباشر وتسريب الأسرار قبل أن تقوم خطوة الملاحظة (Observation) بإعادتها إلى سياق النموذج.
أنشئ مسارات عمل للمطالبات تظل خاضعة للحوكمة في بيئة الإنتاج. احجز عرضاً توضيحياً لترى كيف تربط TrueFoundry بين سجل المطالبات، وحواجز الحماية، وضوابط الميزانية، وسجلات التدقيق داخل بوابة الذكاء الاصطناعي الخاصة بك.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.





أحدث الأخبار والمقالات والموارد تصلك مباشرة إلى بريدك الوارد




















