



October 15, 2026
|
5 min read


Obtenha acesso instantâneo a um ambiente TrueFoundry ao vivo. Implante modelos, direcione o tráfego de LLM e explore a plataforma completa — seu sandbox estará pronto em segundos, sem necessidade de cartão de crédito.



Published: October 15, 2026

Blazingly fast way to build, track and deploy your models!
The Mistral Large 4, dubbed “Le Chonk,” is the newest flagship from Mistral. It is a sparse mixture-of-experts model — roughly 1.05 trillion total parameters with only about 49–52 billion active per token [VERIFY: Mistral’s announcement and docs card disagree on 49B vs 52B active] — paired with a 1.6B-parameter vision encoder, so it takes text and images in and returns text. Tool calling, structured outputs, document Q&A, batching, and built-in tools make this technology clearly fall within the “agent + pipeline” realm rather than purely conversational.
Context is the essential skill. Mistral’s model card lists a 1-million-token context window and a maximum output of 262,144 tokens, though some third-party trackers report 512K [VERIFY against Mistral’s model card before quoting]. Anyway, it’s a model for long contexts, designed for loads of paperwork and agent-based activities.
It shipped as an API public preview on October 6, 2026. The important thing about the word “preview” is that the discount factor applies to it but the weights have not yet been released.
Here is the API rate card next to Claude Sonnet 5.5 and Haiku 5.5 for context — a frontier competitor and a budget baseline.
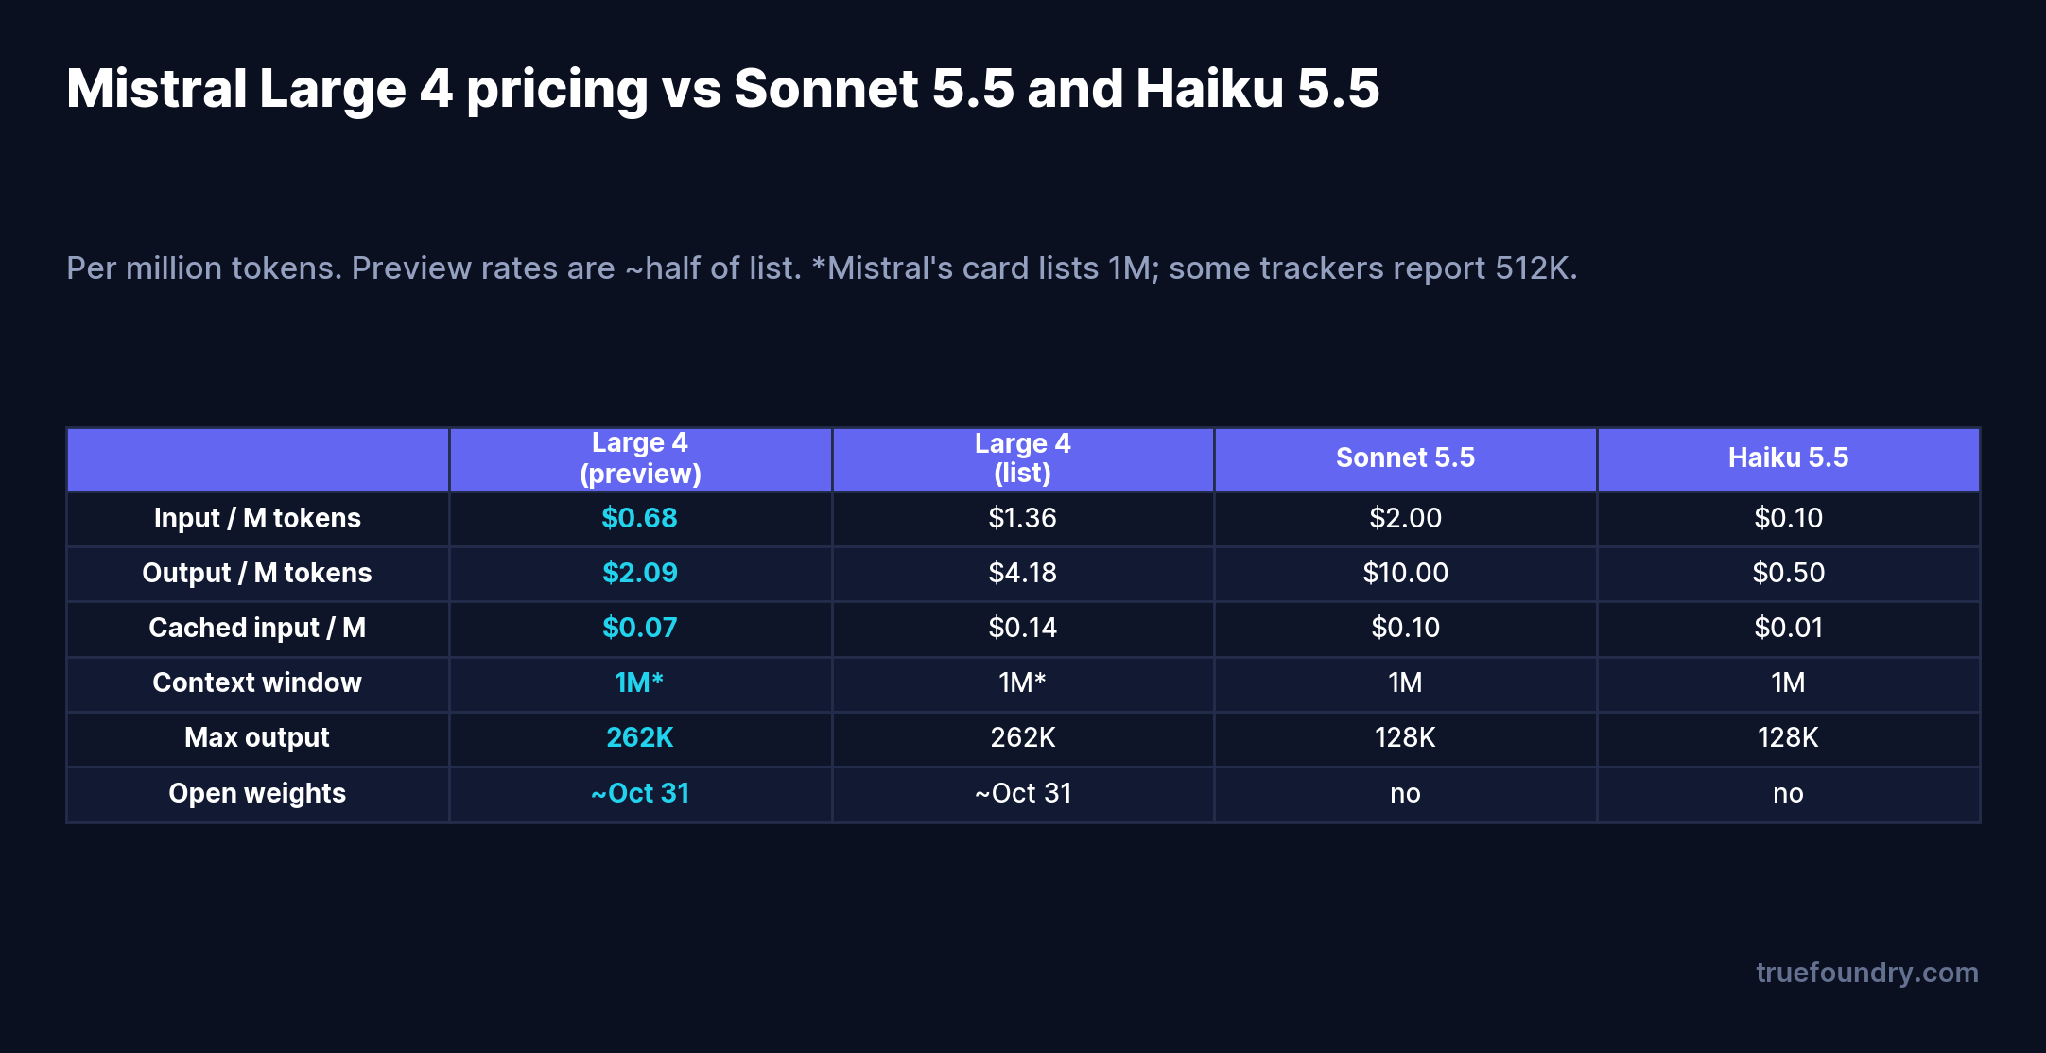
During the preview, Mistral Large 4 costs $0.68 per million input tokens, $0.07 per million cached input tokens, and $2.09 per million output tokens. List pricing — what you should assume for budgeting — is $1.36 / $0.14 / $4.18, exactly double on input and output. Batch processing takes another 50% off, and cached input is discounted up to 90% for repeated prompts [VERIFY API rates against console.mistral.ai; preview discount has no published end date].
At preview rates, Large 4 is meaningfully cheaper than Sonnet 5.5 — a third of the input price and a fifth of the output price. At list rates, the output gap narrows to roughly 2.4× and input to 1.5×. That swing is the single most important fact in this review: the model’s cost position depends entirely on whether you are modeling the preview price or the real one.
Preview discounts are a customer-acquisition tool. They get a model into your pipeline at a price that may not survive general availability, and Mistral has published no end date for this one. If you benchmark Large 4 against Sonnet 5.5 today at $0.68 input and ship it into production, your unit economics can change under you the day the preview ends and the price doubles.
The defensive move is to model both prices before you commit, and to put the model behind a layer where switching is a config change rather than a code change. That is the entire argument for routing model access through a gateway: the day preview pricing ends, you re-run the cost comparison and, if the math no longer works, you re-point traffic — without touching application code.
As with any model, the rate card is not the bill. What you pay depends on the token shape of each task. Here are four representative jobs priced on Large 4 at preview rates, against Sonnet 5.5 and Haiku 5.5.
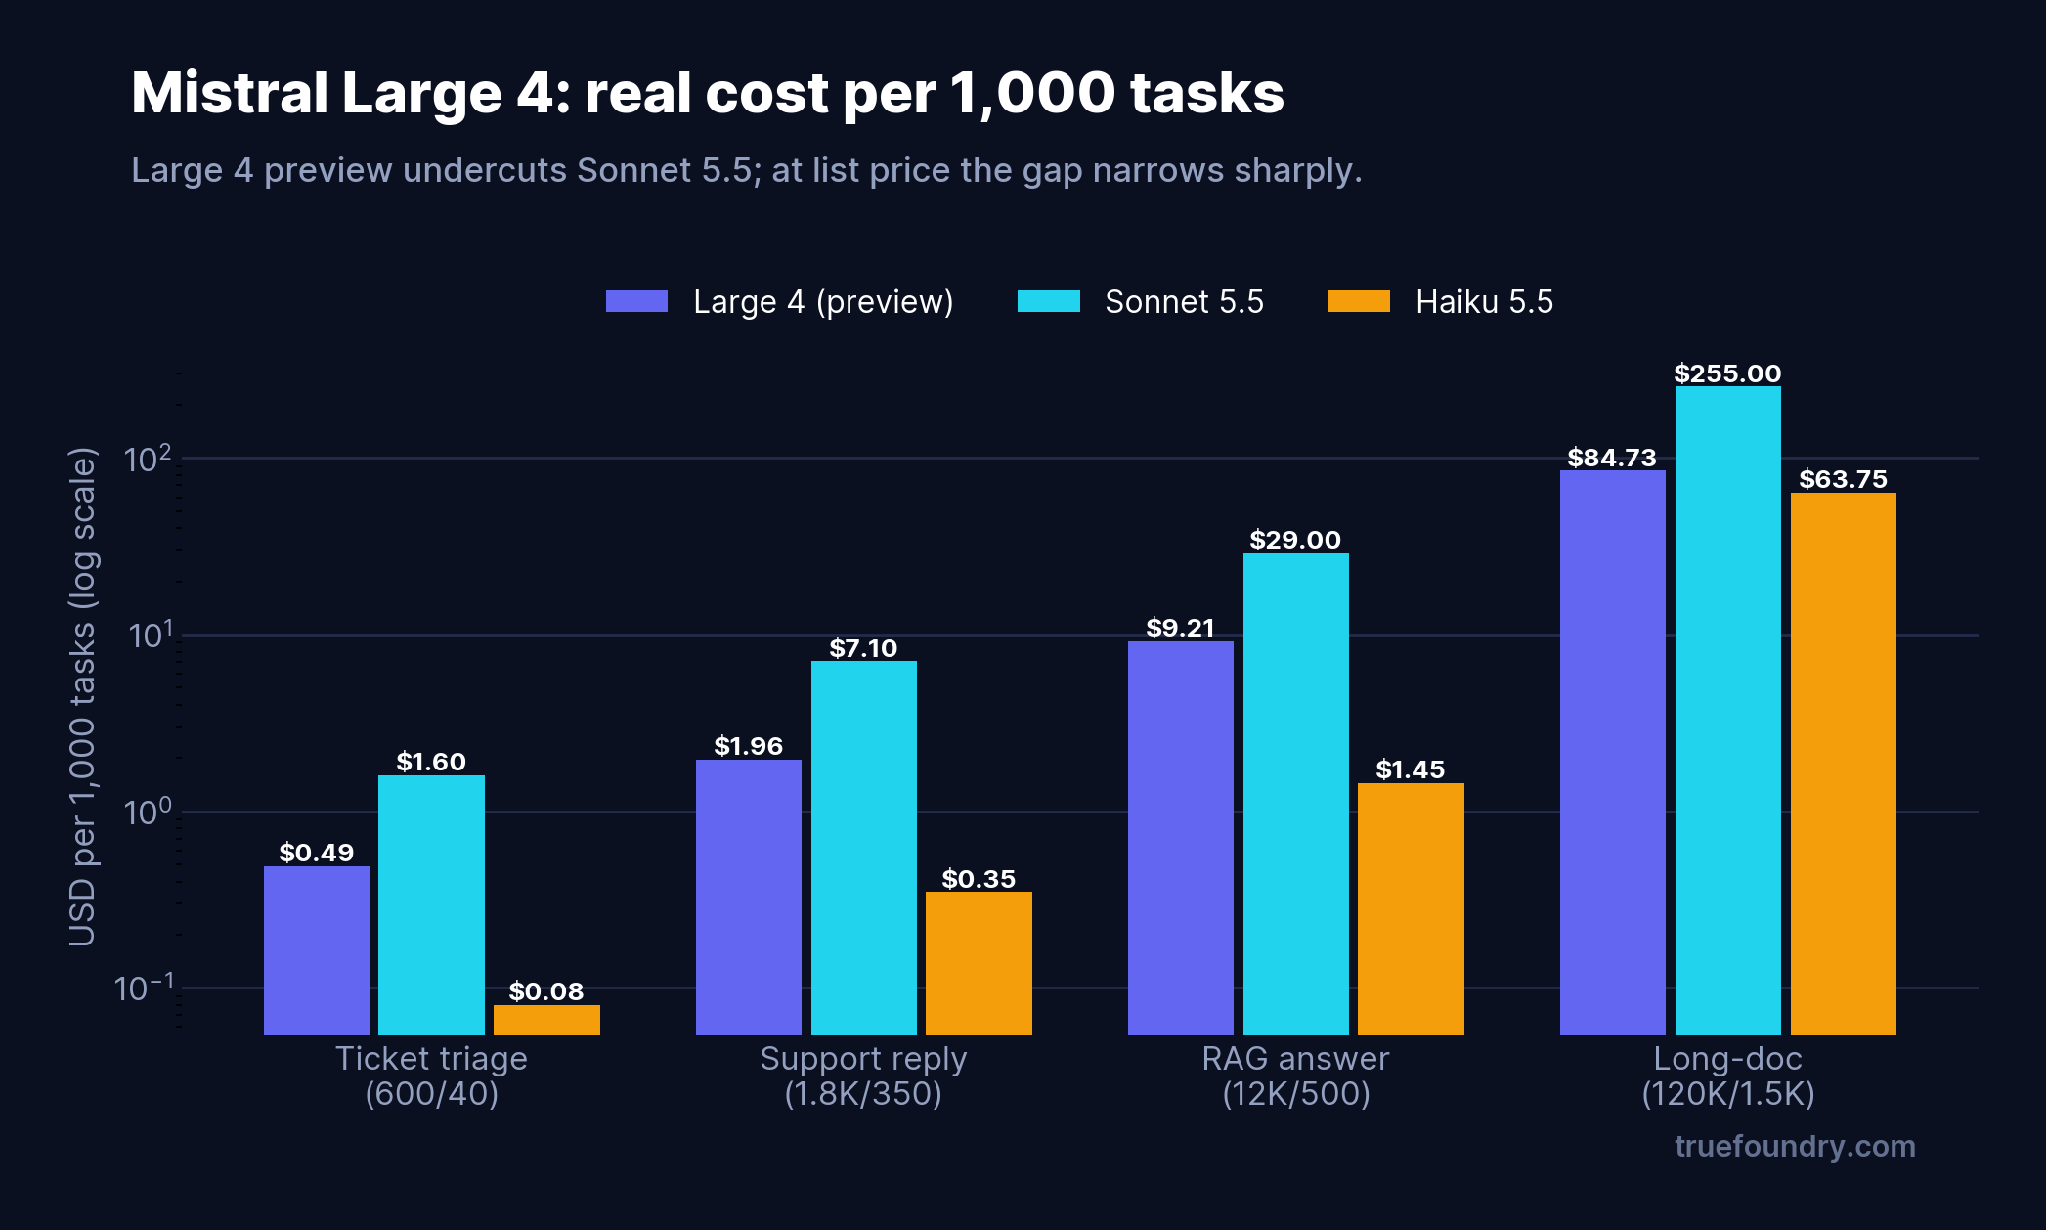
Large 4 preview sits between Haiku and Sonnet on every task — cheaper than Sonnet, well above Haiku. At list price, those Large 4 numbers roughly double, which pushes it much closer to Sonnet territory while Sonnet scores higher on general-intelligence benchmarks. That is the crux of the value question: at preview price it is a genuine bargain; at list price you are paying nearly Sonnet money for a mid-pack intelligence score, unless your workload happens to be one of its strengths.
Large 4’s benchmark profile is lopsided in an interesting way.
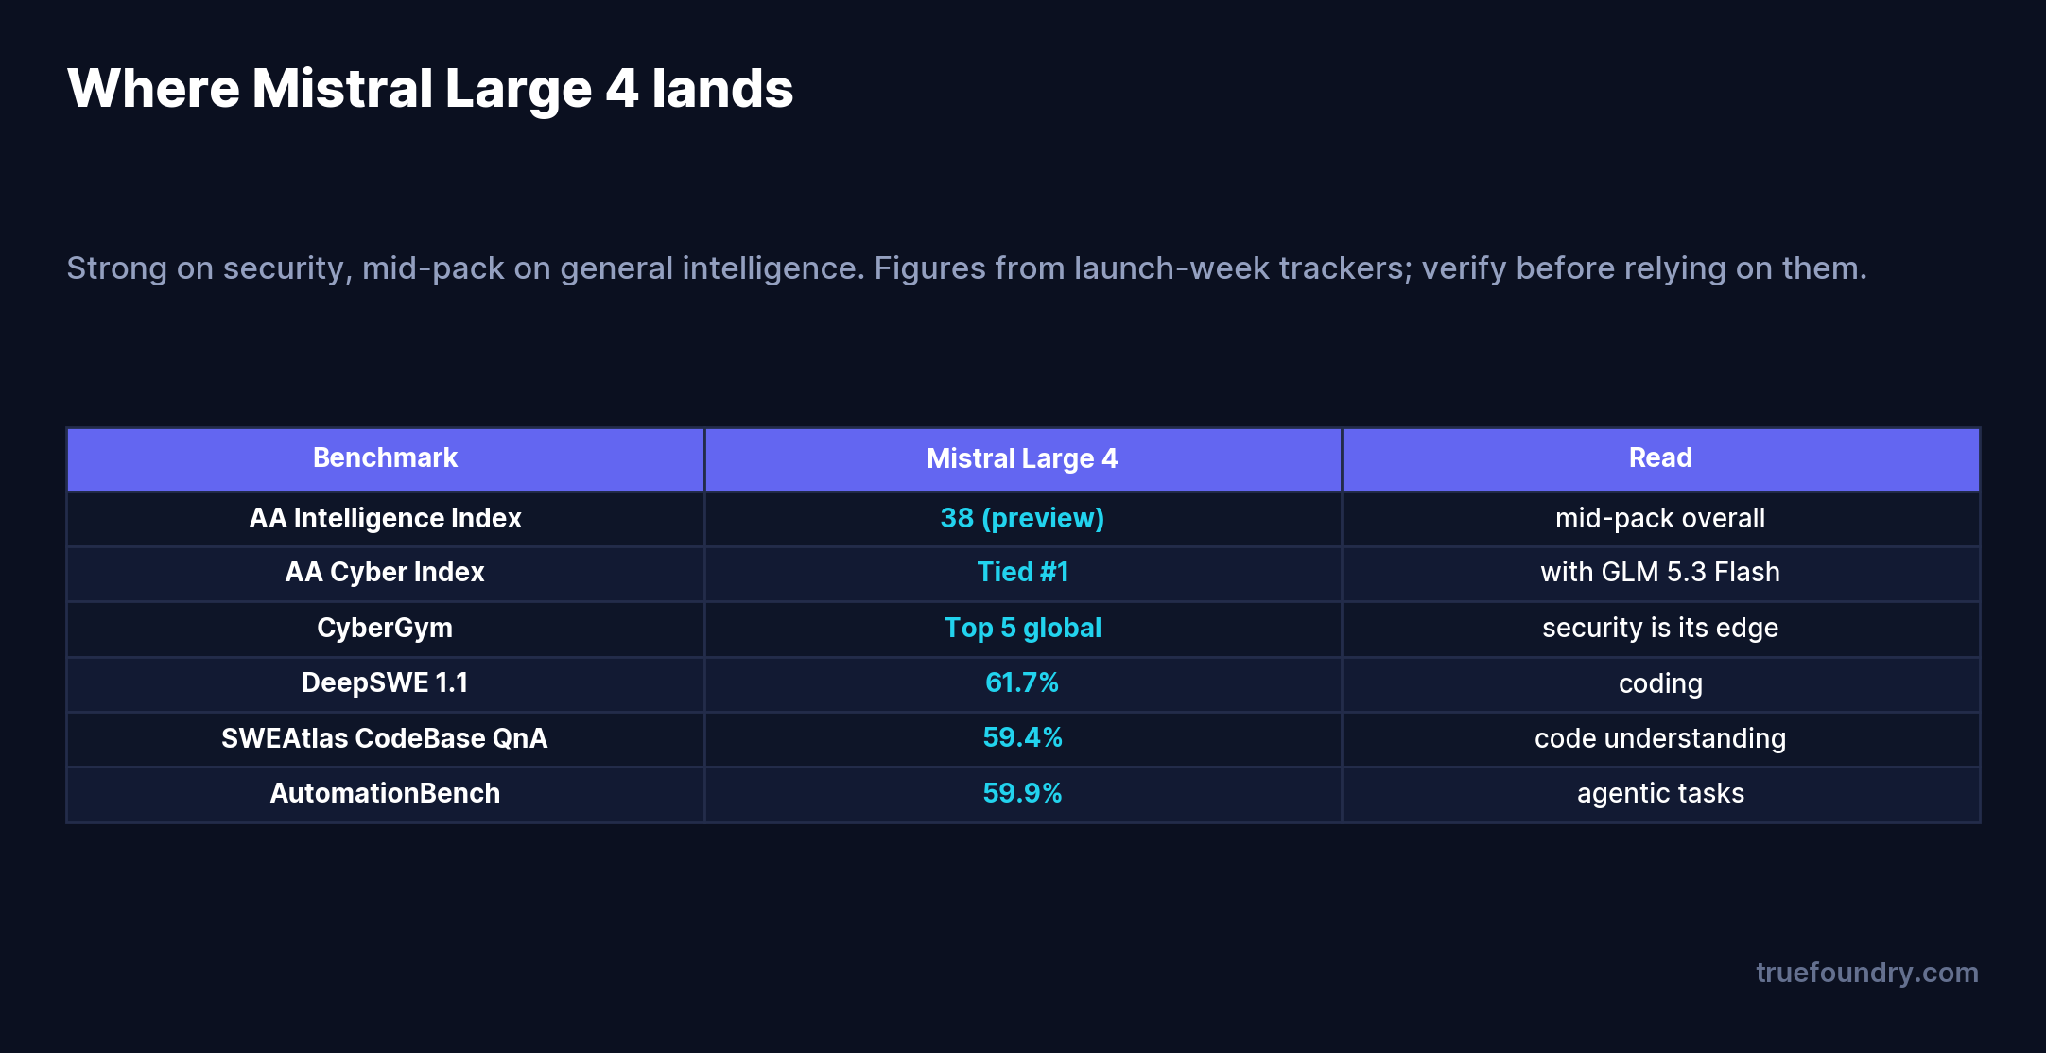
On the Artificial Analysis Intelligence Index it scored 38 in preview — mid-pack, well behind the top closed-source models. But on security it is genuinely strong: tied for first on the AA Cyber Index (alongside GLM 5.3 Flash) and in the top five globally on CyberGym. Coding and agentic results are respectable but not leading [VERIFY: benchmark figures are from launch-week trackers citing single sources; confirm against the original evaluations].
The practical read: if your workload is security tooling, threat analysis, or code-security review, Large 4 is worth a serious look. If you need a general reasoning leader, the intelligence index says you are paying for a specialty you may not use.
They lock in on preview pricing. The most common mistake is building unit economics on the $0.68 input rate. Model the $1.36 list rate; treat the preview as a bonus, not a baseline.
They assume one big model for everything. Large 4’s intelligence score is mid-pack. Routing easy, high-volume work to a cheaper model (Haiku 5.5, Mistral Small) and reserving Large 4 for its strengths beats sending everything to the flagship.
They wait on open weights without a plan. Weights are expected around end of October 2026, but under a custom license, not Apache 2.0. Read the license before assuming self-hosting is free for commercial use.
They compare on sticker price, not task cost. A model’s input/output ratio changes the ranking. Large 4’s output is 3× its input; generation-heavy workloads cost more than the input rate suggests.
The recurring theme — model both prices, keep switching cheap, measure real cost — is exactly what a gateway is for. In the TrueFoundry AI Gateway, Mistral is a provider you add alongside the others, and every call is metered the same way.
From the dashboard, go to AI Gateway > Models and select Mistral AI.
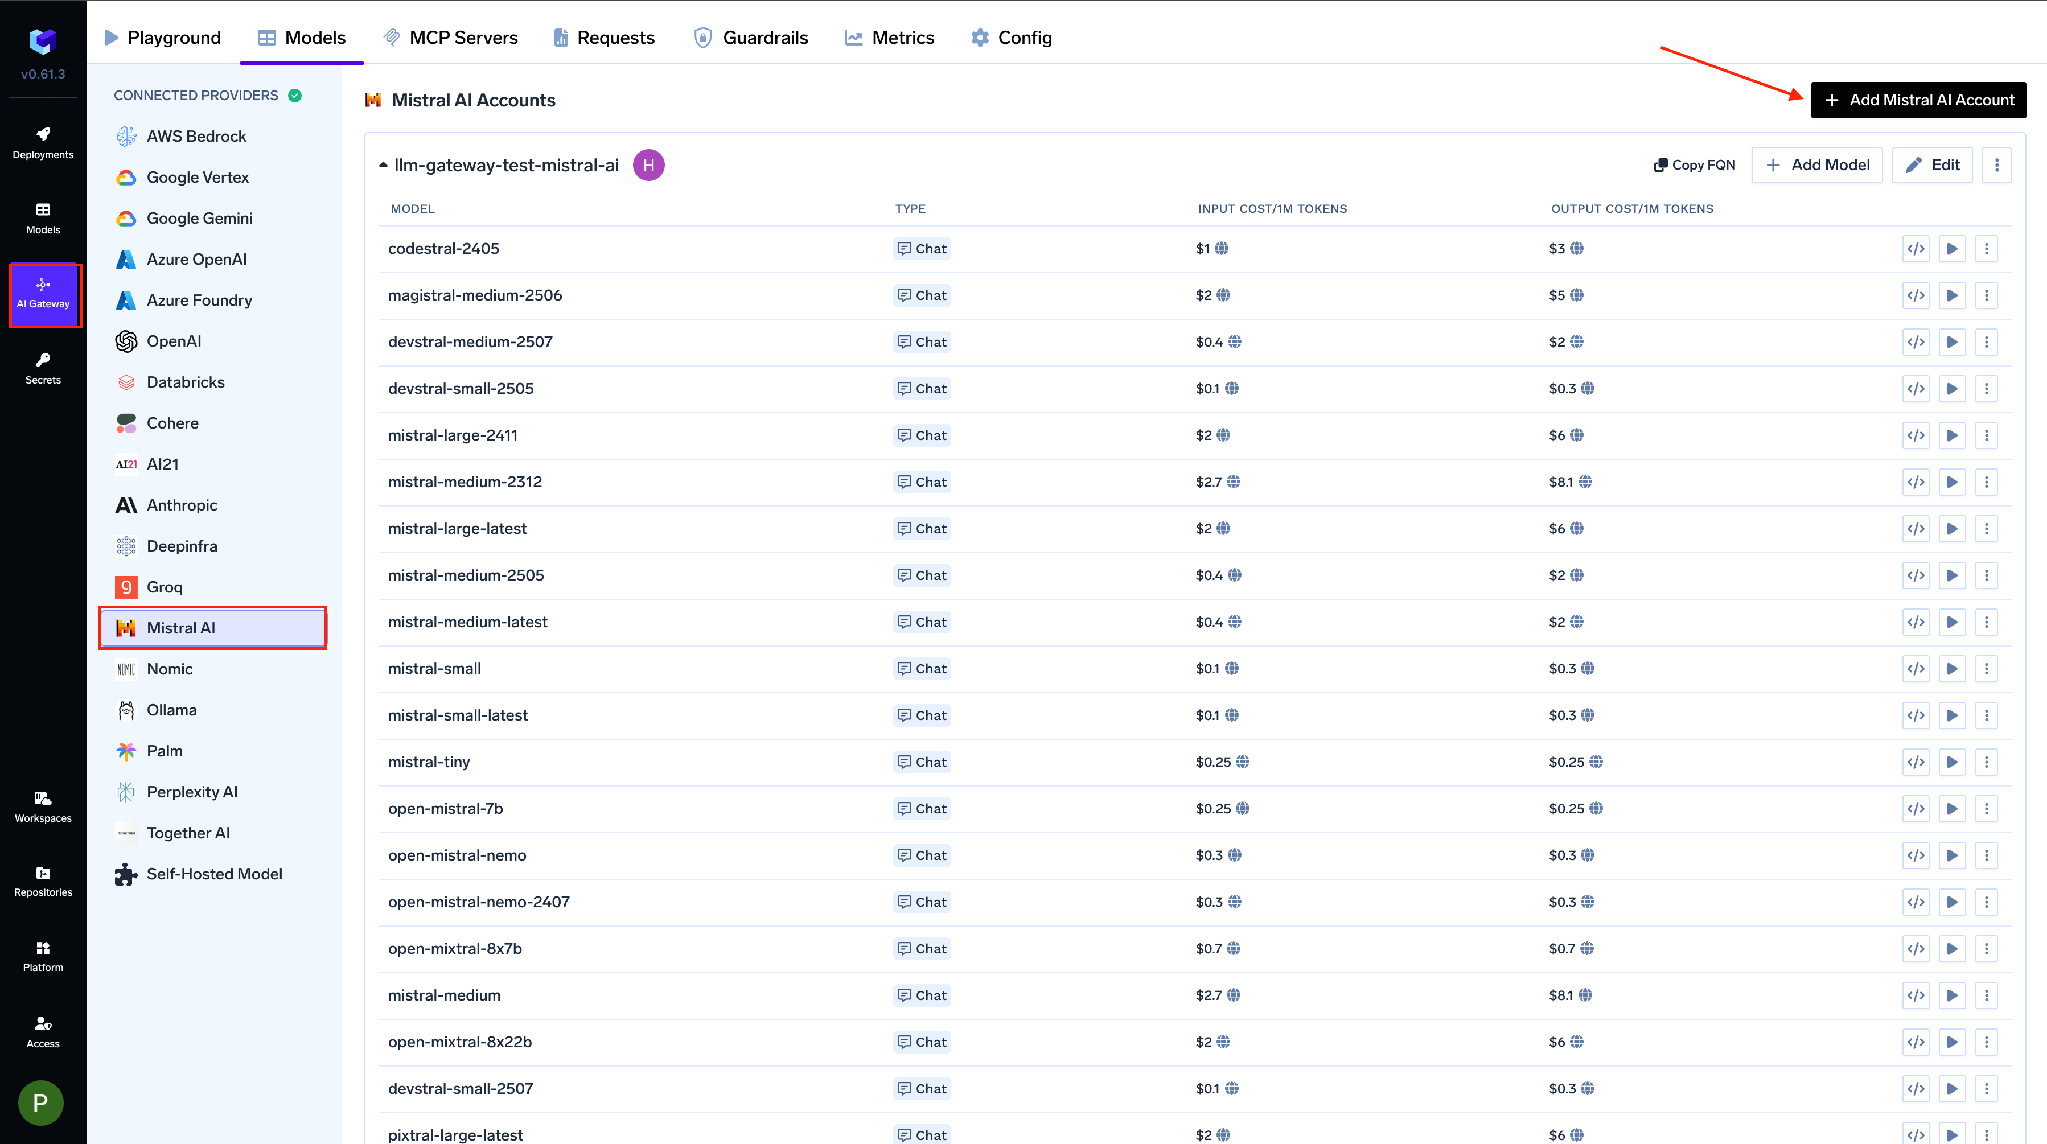
Add your Mistral account with its API key, name it, and set collaborators so the right teams get access.
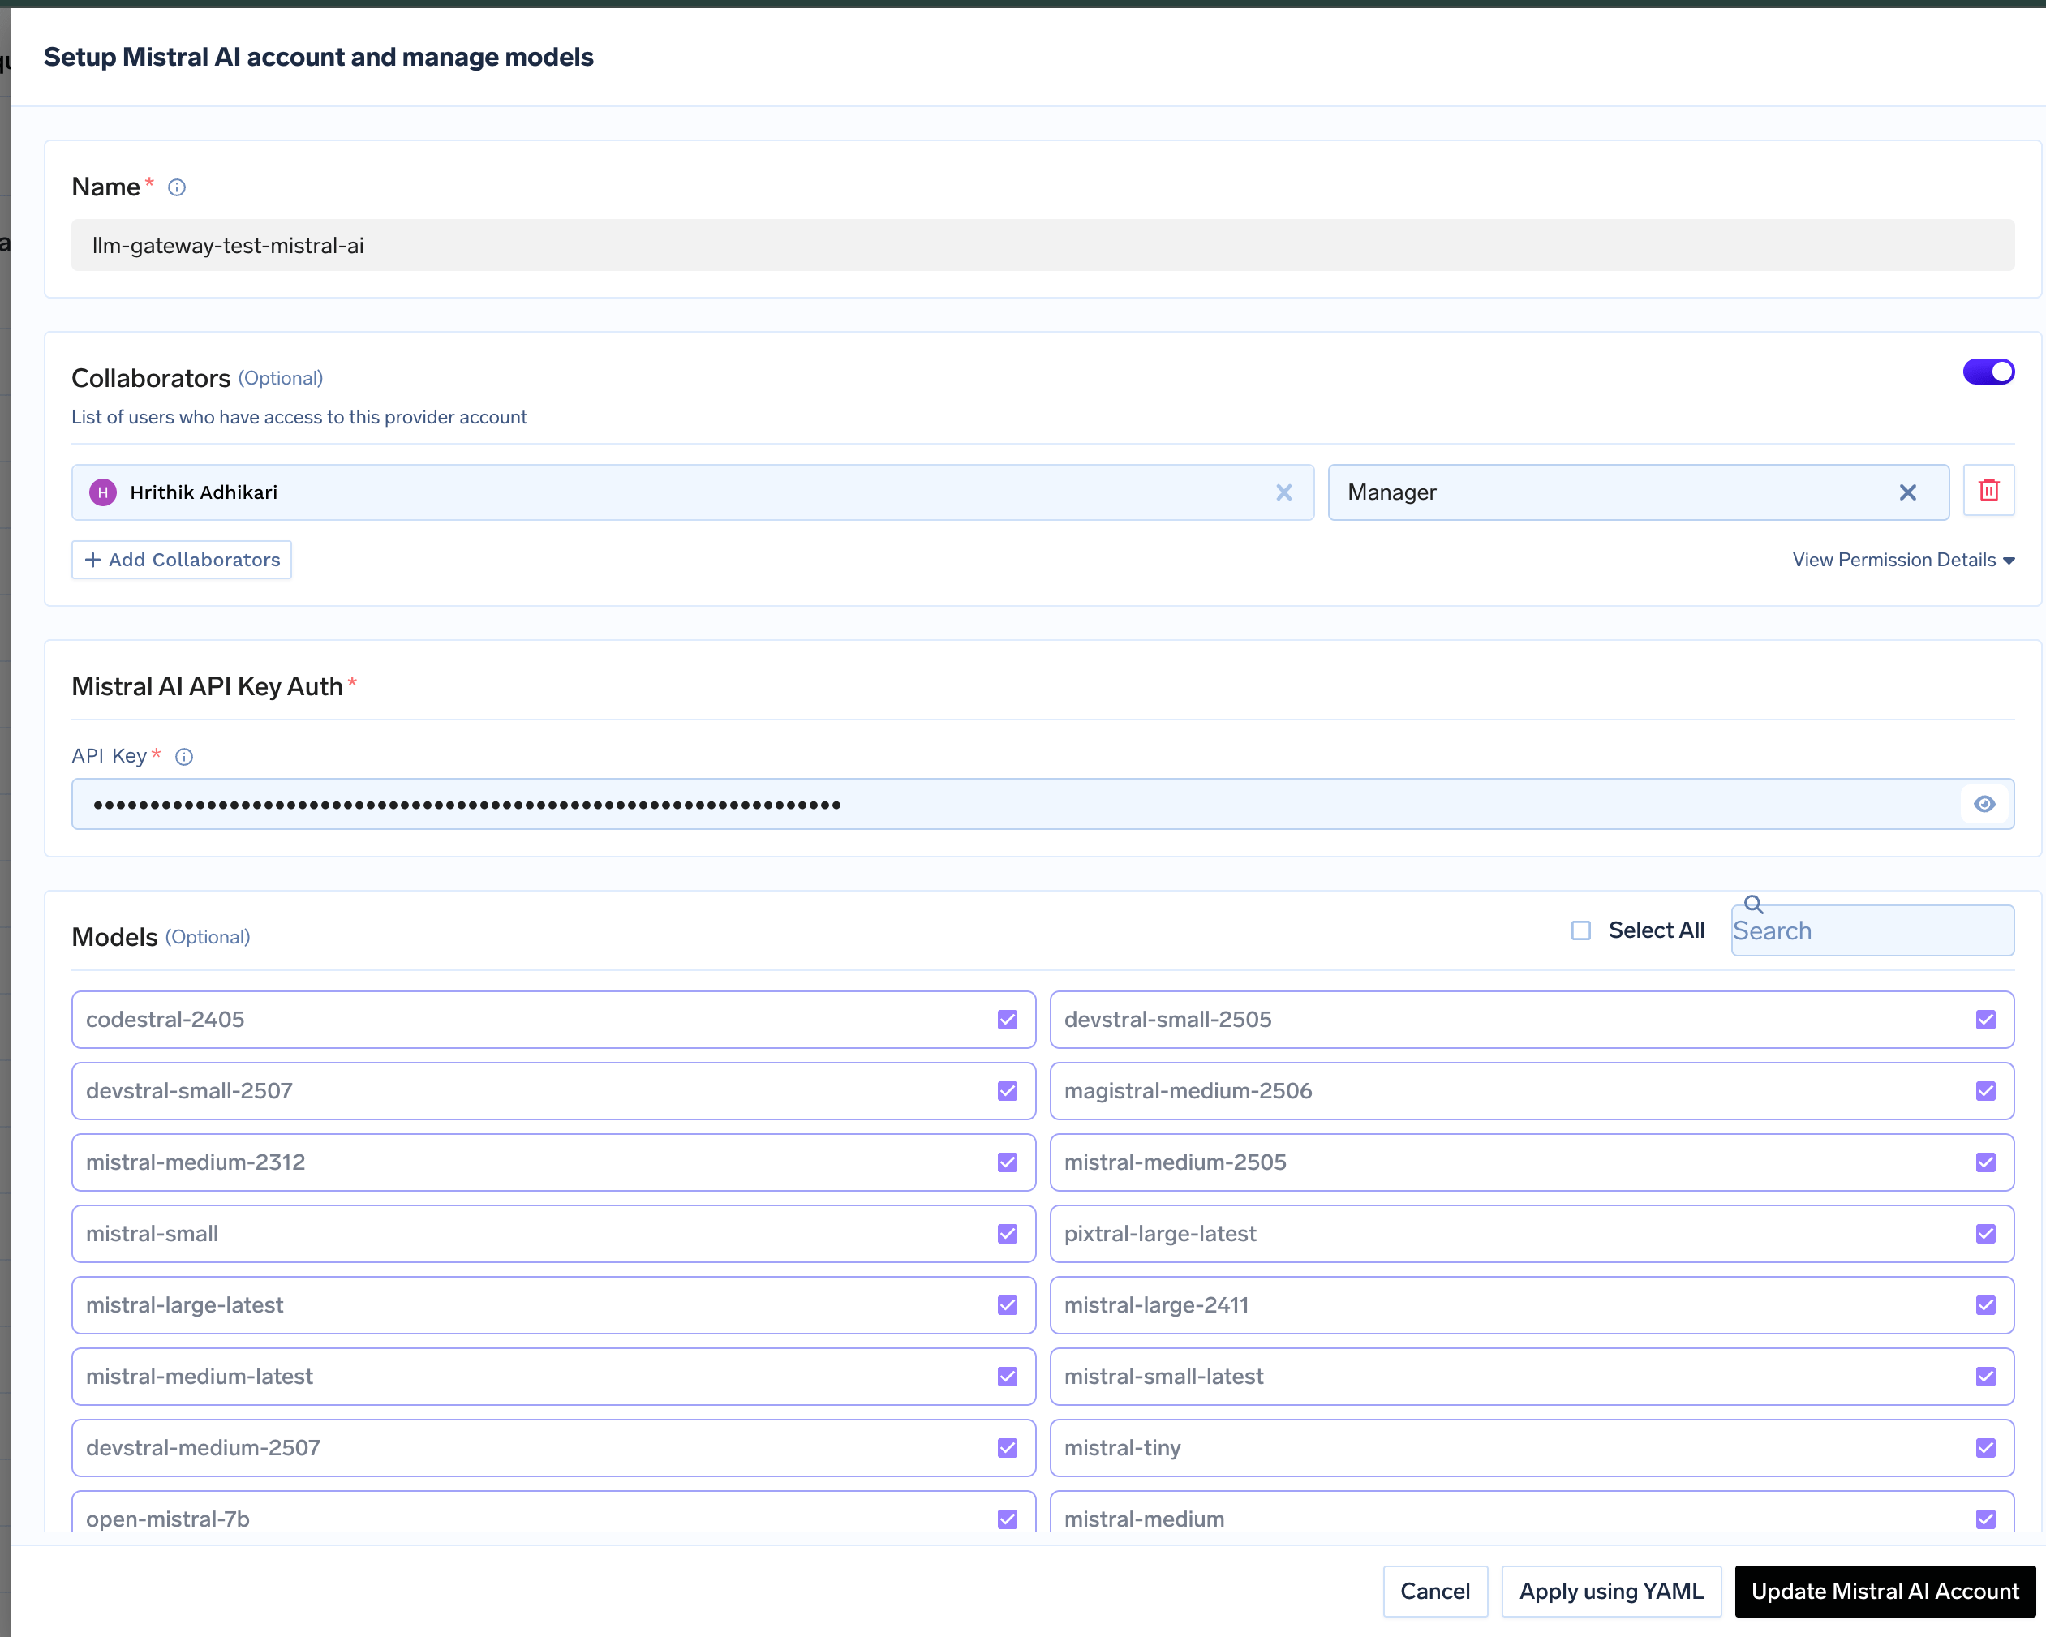
The Mistral account form, with access control built in. Source: TrueFoundry docs.
Pick Large 4 (or any Mistral model) from the list, and you can call it immediately over an OpenAI-compatible API — from the Playground or your own application.
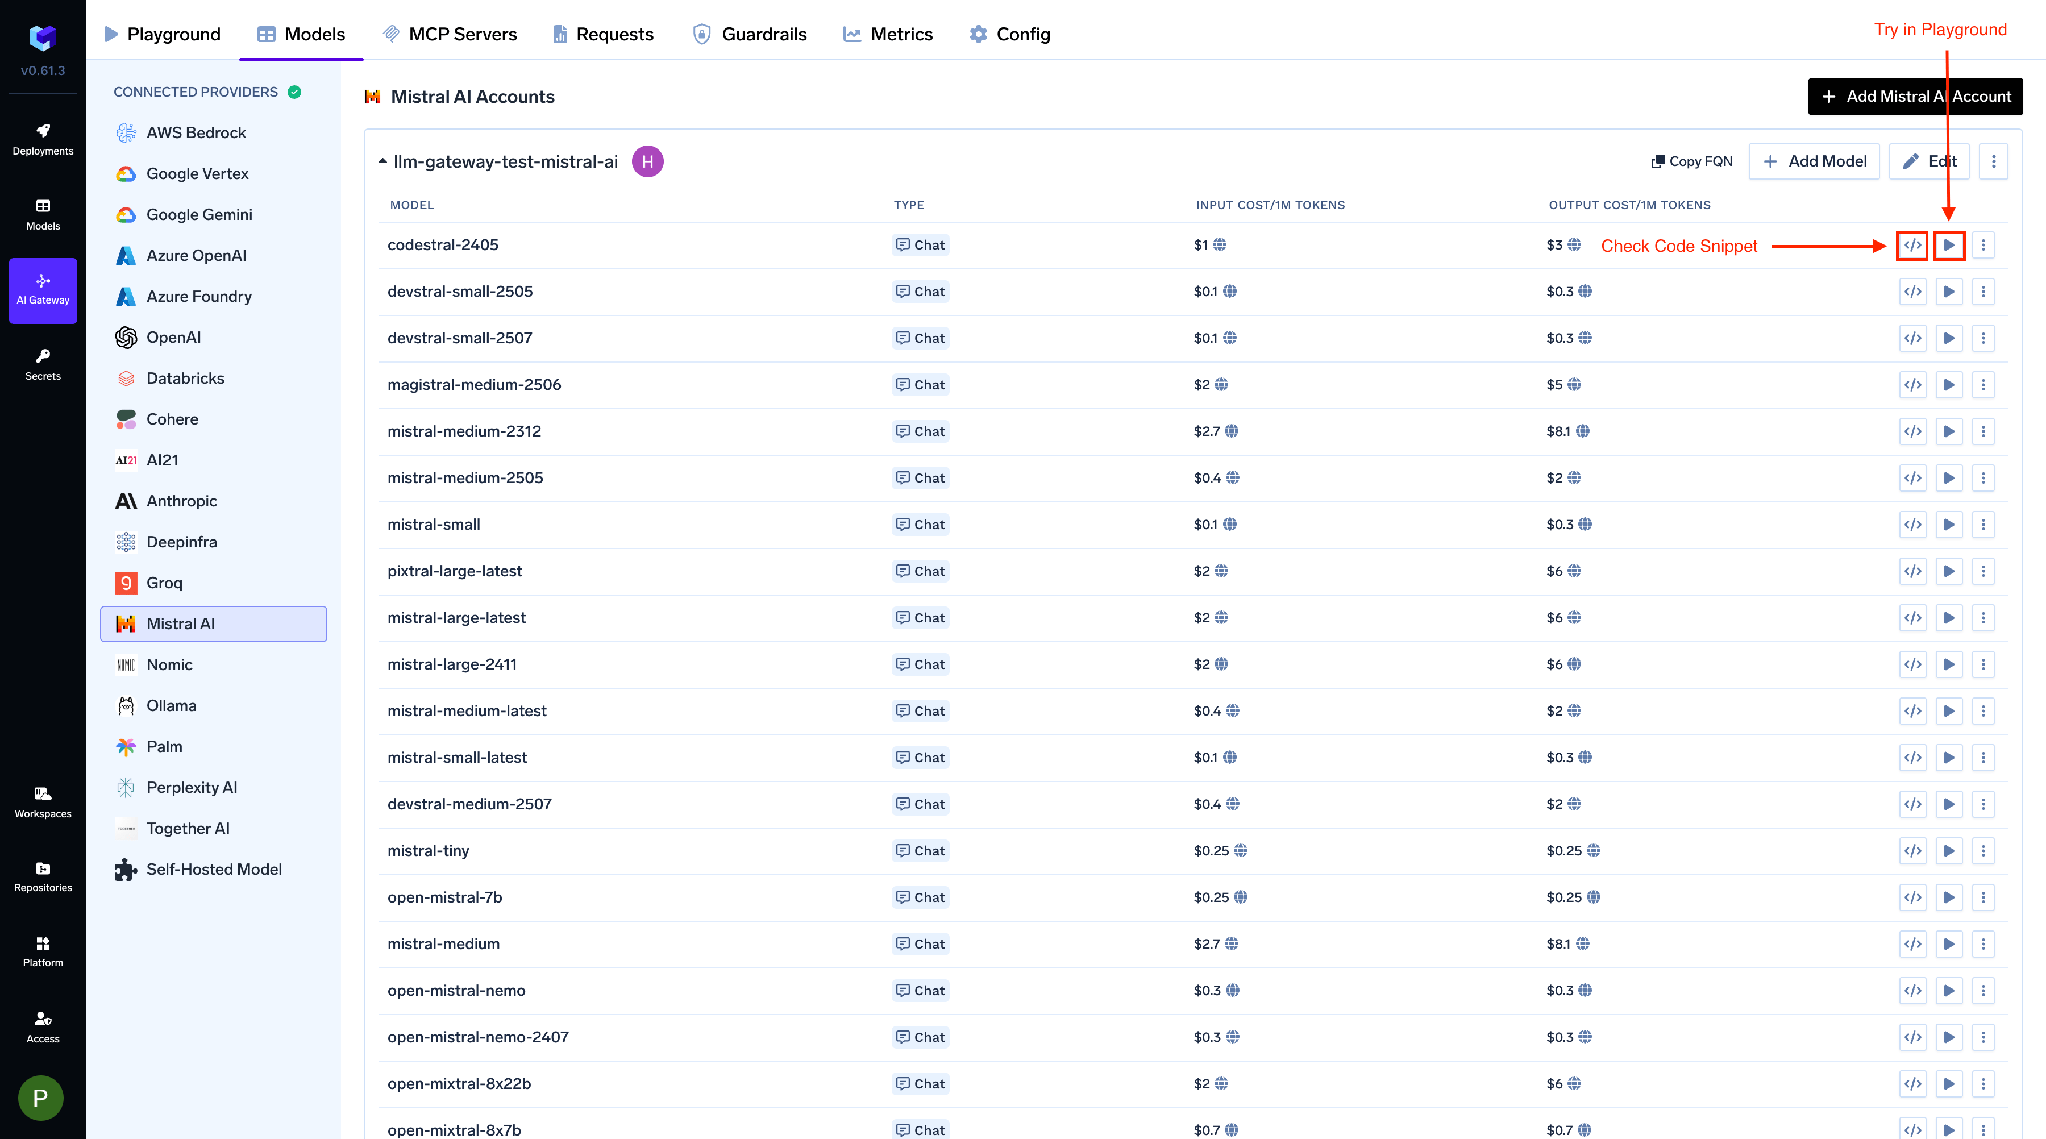
OpenAI-compatible inference and Playground. Source: TrueFoundry docs.
Because Large 4 reaches your app through the same OpenAI-compatible endpoint as every other model, three things become config, not code:
A security team runs an automated code-security review: 40,000 PR-diff tokens in, 1,200 tokens of findings out, 2,000 reviews a month.
On Large 4 at preview rates, that is about (40,000 × $0.68 + 1,200 × $2.09) per million, roughly $0.0298 per review — about $60/month. At list rates it is roughly $0.0595 per review, or $119/month. On Sonnet 5.5 the same job is about $0.092 per review, or $184/month.
For this workload — where Large 4’s security strength is the point — preview pricing makes it a clear win, and even at list it undercuts Sonnet. Route the security reviews to Large 4, keep general chat on a cheaper model, and let the gateway’s metrics confirm the blended cost. If the preview ends and the economics shift, you change one routing rule.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.



During the API public preview, $0.68 per million input tokens and $2.09 per million output tokens, with cached input at $0.07. List pricing is $1.36 input and $4.18 output. Batch processing is 50% off and cached input is discounted up to 90%.
At preview rates, yes — roughly a third of the input price and a fifth of the output price. At list rates the gap narrows to about 1.5× on input and 2.4× on output, so the advantage depends heavily on whether the preview discount is still active.
Not yet. Mistral has committed to releasing open weights around the end of October 2026, but under a custom Mistral license rather than the Apache 2.0 license used for Mistral Large 3.
Security. It is tied for first on the Artificial Analysis Cyber Index and ranks in the top five on CyberGym. On general-intelligence benchmarks it is mid-pack, so it is best matched to security and specialized workloads rather than used as a general reasoning leader.
Route it through the TrueFoundry AI Gateway. It meters every call and attributes cost by model, team, user, and request, so Mistral spend appears in the same dashboard as Claude, OpenAI, and Gemini — with public or private (your preview-rate) pricing.
Through the gateway, yes — the data plane runs in your VPC or on-prem, so prompts and usage stay in your environment. Once Mistral’s open weights ship, you can also self-host the model itself, subject to its license.



As últimas notícias, artigos e recursos enviados para sua caixa de entrada

















