


Accédez instantanément à un environnement TrueFoundry en direct. Déployez des modèles, acheminez le trafic LLM et explorez la plateforme complète : votre sandbox est prête en quelques secondes, aucune carte de crédit n'est requise.


What is fine-tuning and what are its types?

AI models are first trained on large amounts of data so they can learn broad patterns and handle a variety of use cases. This initial training gives a base model general knowledge and the core knowledge needed to process new inputs.
However, a model trained for broad use may not always work well for a particular business need. For example, it may not understand industry-specific terms, follow a preferred writing style, or handle a specialized task with the required level of accuracy.
Fine-tuning helps address this gap through additional training on a specific dataset related to a task or domain. This lets the model adapt without repeating the full model training process from the beginning.
This guide explains what is fine-tuning, how it works, the different approaches, its benefits and limitations, and when it may be useful in generative AI and other machine learning applications.
What is fine-tuning?
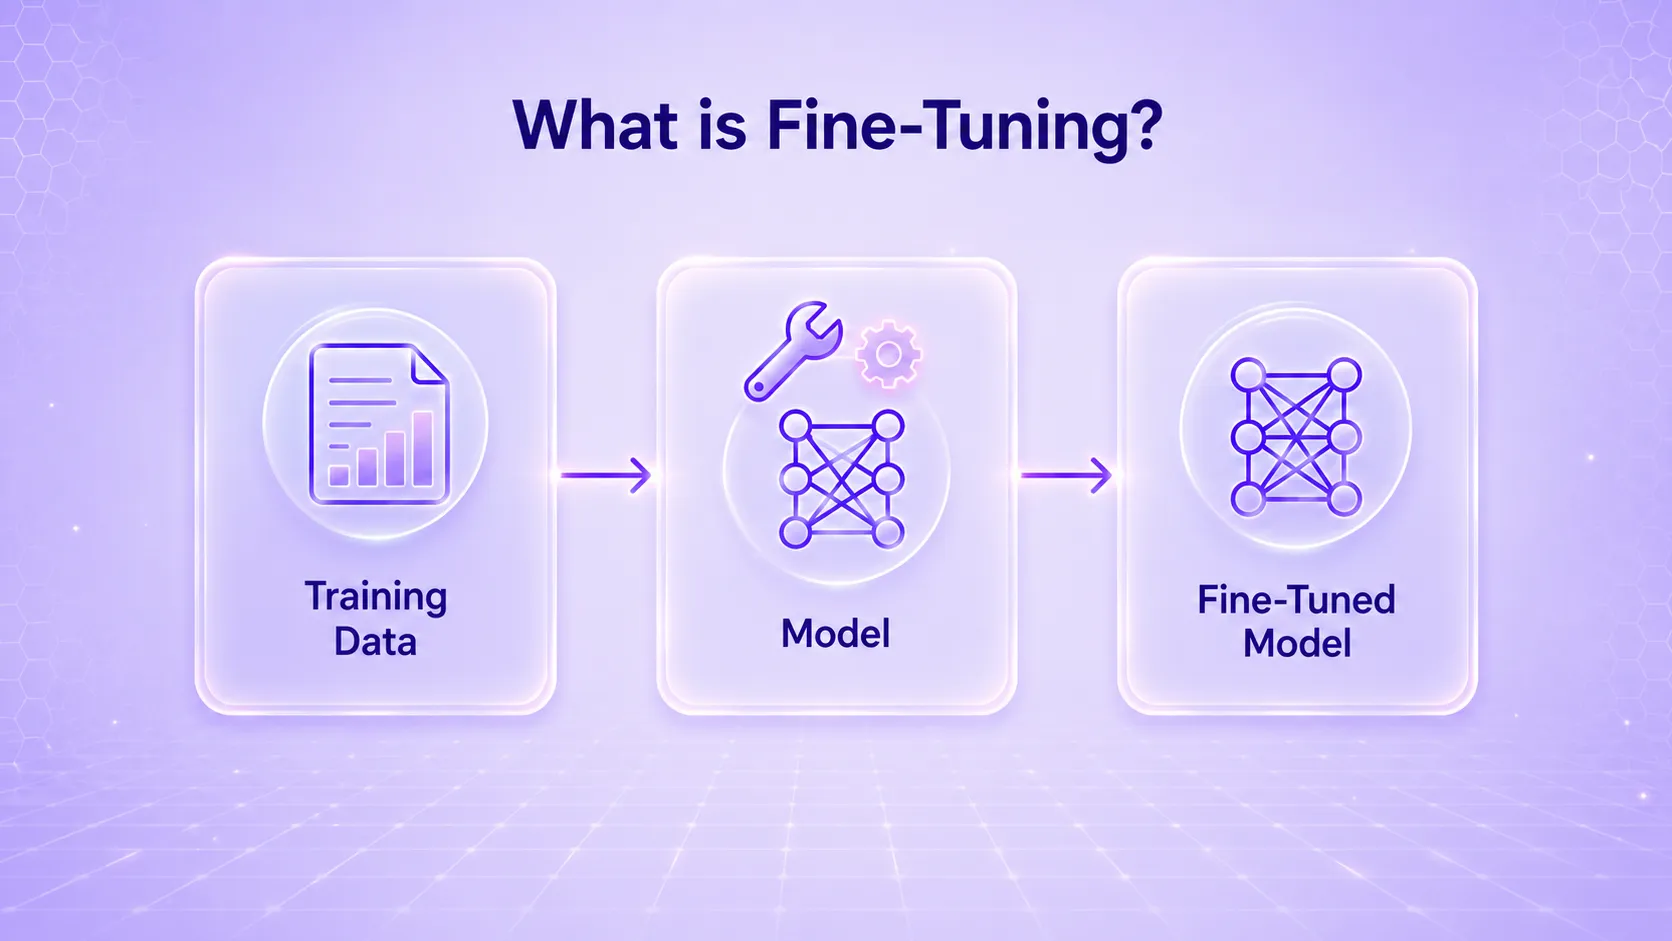
Fine-tuning is a form of transfer learning in which a pretrained model is trained further on a smaller, task-specific dataset. The original model already contains broad capabilities from its earlier training, so fine-tuning adapts those capabilities instead of rebuilding them.
Depending on the method, fine-tuning may update all model weights or only a smaller subset. This further training changes how the model responds to specific inputs while preserving much of the general knowledge learned during the initial training.
For language models, this can improve performance on tasks involving natural language, natural language processing, classification, summarization, or code generation. Fine-tuning can also be used outside language tasks, including image classification and other deep learning applications.
Because the model starts from existing knowledge, fine-tuning usually needs fewer computational resources, lower memory requirements, and lower overall computational requirements than training a neural network from scratch.
What are the types of fine-tuning?
Fine-tuning approaches differ in the training data they use, the goal of the training, and how much of the model changes. The right approach depends on the task, the available training examples, the base model, and the computational resources available.
The major approaches include:
1. Supervised fine-tuning (SFT)
Supervised fine-tuning uses labeled training examples, where each input is paired with an expected output. During the training process, the model compares its predictions with these targets and updates selected parameters.
SFT is commonly used for sentiment analysis, question answering, text generation, classification, and other supervised machine learning tasks.
2. Instruction fine-tuning
Instruction fine-tuning trains the model on examples that pair an instruction or prompt with a response. This helps the model learn how to follow user directions across different tasks.
For example, the training data may show the model how to summarize text, answer a question, or rewrite content based on an instruction.
3. Parameter-efficient fine-tuning (PEFT)
Parameter-efficient fine-tuning (PEFT) keeps most of the pre-trained model unchanged and trains only a small number of parameters. This reduces the memory and processing power needed compared with updating the full model.
Methods such as Low-Rank Adaptation (LoRA) and prompt tuning fall under PEFT. LoRA trains small added matrices, or groups of numerical values, to capture task-specific changes. By contrast, prompt tuning learns soft prompts that guide the model toward a particular task.
4. Domain adaptation
Domain adaptation helps a model work better with the language and patterns used in a particular field. The model trains further on data from that field so it becomes more familiar with its terminology and writing style.
For example, a general-purpose model can be adapted using legal, financial, or technical data to perform better within that field.
5. Reinforcement learning from human feedback (RLHF)
Reinforcement learning from human feedback (RLHF) uses human preferences to guide how the model responds. People compare or rate different model responses, and the model uses that feedback to learn which responses are preferred.
RLHF is often used after earlier training stages to further align the model with preferred behavior.
How does fine-tuning work?
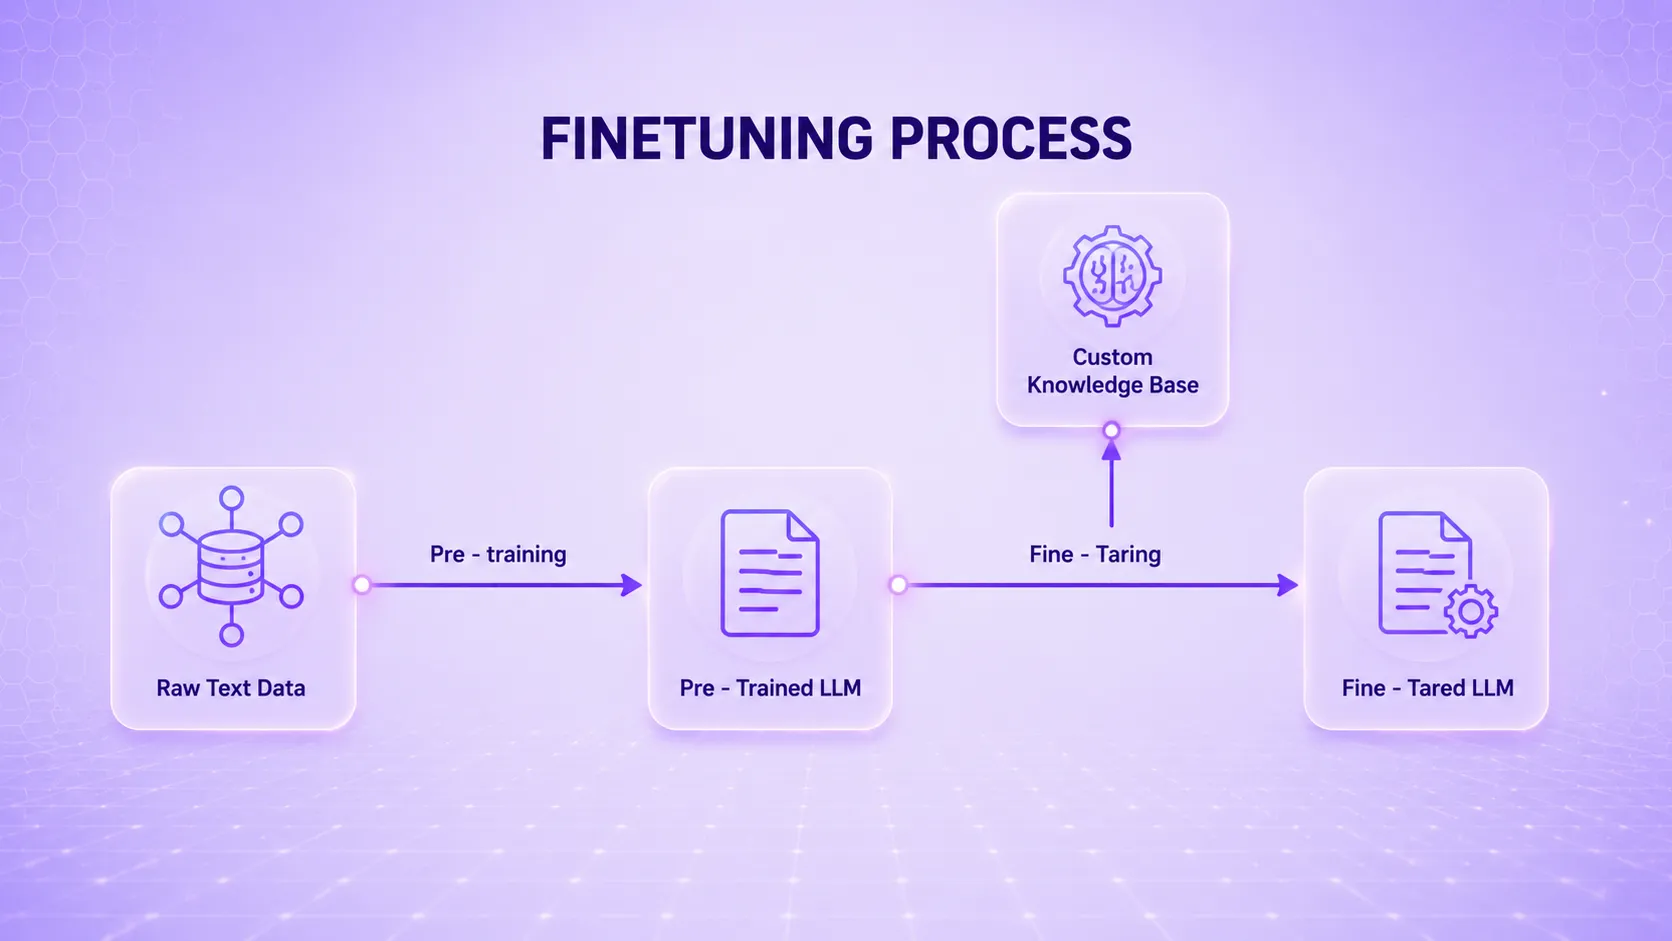
Fine-tuning starts with a pre-trained model that has already learned general patterns from a large amount of data. Instead of training the model from the beginning, you continue training it on a smaller dataset that is relevant to a specific task or domain. This allows the model to build on what it already knows and adapt to the new task.
During fine-tuning, the model compares its predictions with the expected outputs in the training dataset. It then adjusts its parameters to reduce errors and improve future predictions. This process continues across the dataset until the model performs well on the target task.
How much of the model changes depends on the fine-tuning method. In full fine-tuning, the entire model is updated, whereas methods such as PEFT update only a smaller set of parameters.
After training, the model is evaluated on held-out or test data it has not seen before. If it performs as expected, it can then be deployed for tasks such as support-ticket routing, information extraction, document classification, domain-specific question answering, or generating content in a particular style.
Fine-tuning vs training
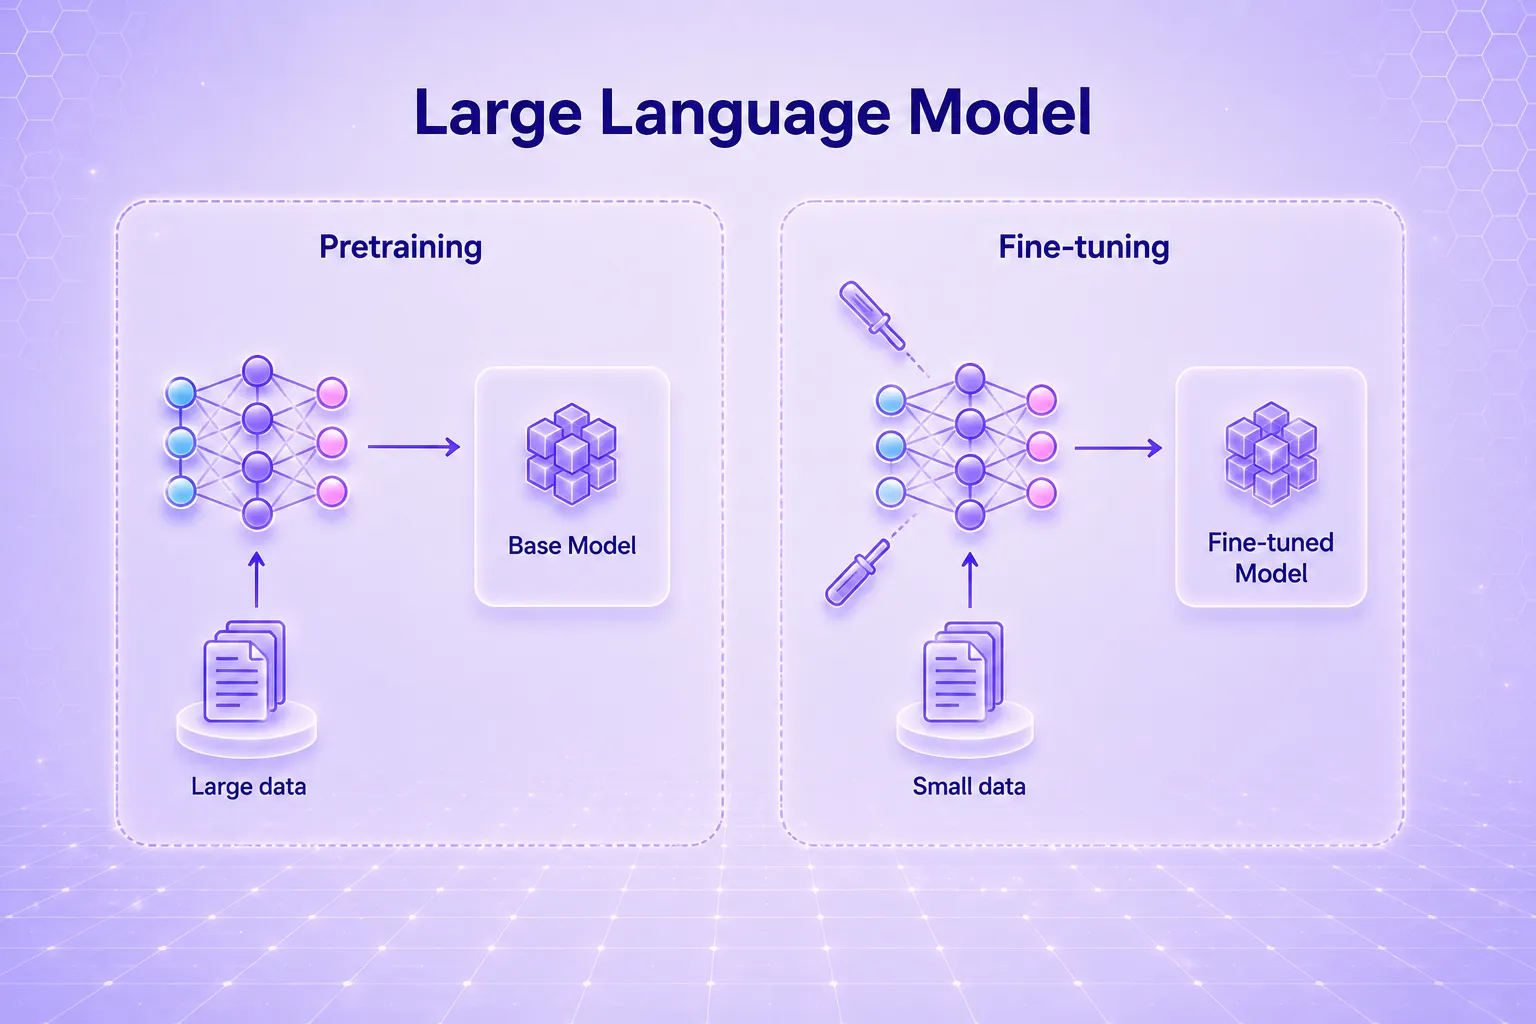
Training builds a model from scratch using very large datasets and substantial computational resources. During this initial training, a neural network learns broad statistical patterns from raw data.
For large language models, this process develops the raw linguistic capabilities of base foundation models. These capabilities include grammar, language structure, reasoning patterns, and broad general knowledge.
Fine-tuning starts from this already trained base model. It adds further training on a narrower dataset so the model becomes better suited to a specific task or domain.
This is the main difference between the two approaches. Initial training builds the model’s core knowledge, while fine-tuning specializes that knowledge. As a result, fine-tuning usually has lower computational requirements and shorter training times.
How to fine-tune large language models?
Fine-tuning a large language model involves several steps, from data preparation to evaluation and deployment. It is an essential part of the LLM development cycle when teams need to adapt a base model for a specific use case.
Step 1: Choose a pre-trained model and dataset
Start by selecting a pretrained model that fits the task and the environment where it will run.
Teams often use open source models available through platforms such as Hugging Face. The selected dataset should contain representative training examples for the intended task.
Step 2: Prepare the data
Data preparation involves cleaning, formatting, and validating the training examples before model training begins.
Depending on the task, examples may be structured as prompts and responses, input-output pairs, labels, or instruction datasets. Good data preparation helps reduce noisy model outputs and inconsistent behavior.
Step 3: Tokenize the data
Next, the text is converted into tokens that the model can process. A tokenizer maps natural language into numerical representations used by the neural network.
For language models, the tokenizer should match the selected pretrained model so the inputs align with what the model saw during its initial training.
Step 4: Load the pre-trained model
Once the data is prepared, the pretrained model is loaded as the starting point. The original model already contains broad language capabilities and general knowledge.
Fine-tuning then adapts those existing capabilities through further training instead of rebuilding the model from scratch.
Step 5: Set up training and evaluation
Before training begins, teams define evaluation metrics and training settings.
Depending on the task, this may include accuracy, precision, recall, F1 score, learning rate, batch size, number of epochs, and evaluation frequency.
These settings help control the training process and provide a way to measure the model’s performance on unseen data.
Step 6: Fine-tune and evaluate the model
The model is then trained on the prepared dataset. During this process, the optimizer updates the selected model parameters to reduce training loss on the target task. After training, it is tested on new data to check how well it performs before model deployment.
What are the benefits of fine-tuning?
Fine-tuning can improve how a model performs for a specific task or domain in several ways:
- Better task performance with less data: Fine-tuning can improve performance on a specific task while using much less data than training a new model from scratch.
- More consistent language and style: The model can learn preferred terminology, writing style, and formatting from the fine-tuning data.
- Less reliance on detailed prompts: Because the model has already learned the desired behavior during training, it may need less prompt guidance for the same task.
- More consistent behavior for specific use cases: Fine-tuning can help the model learn specialized terminology, response patterns, and task behavior for a particular domain.
What are the limitations of fine-tuning?
Fine-tuning can improve model performance, but it also has some limitations:
- Overfitting and catastrophic forgetting: If the training data is too limited, the model may become too specialized or lose some earlier capabilities. Testing it on unseen data and using a representative dataset can help identify these problems before deployment.
- Dependence on data quality: Poor labels, bias, or inconsistent examples can affect model responses. Reviewing and cleaning the training data before fine-tuning can reduce this risk.
- It does not keep knowledge up to date: Fine-tuning mainly changes model behavior and is not a reliable way to provide changing information. Retrieval-Augmented Generation (RAG) can be used when the model needs access to current external sources.
- Performance may drop on different data: A model may perform well during testing but struggle with different inputs. Testing with varied, realistic data can help identify distribution shifts.
- Privacy and compliance concerns: Sensitive or regulated data requires careful controls around access, storage, and training use.
- Ongoing cost and maintenance: Fine-tuned models still need evaluation and monitoring after deployment so teams can identify performance changes and decide when retraining is needed.
How TrueFoundry simplifies LLM fine-tuning
Fine-tuning is an important part of the LLM development cycle, but it is only one stage. Teams also need to prepare data, run training jobs, evaluate model outputs, deploy approved versions, monitor performance, and manage access.
TrueFoundry brings these stages into one platform. Teams can fine-tune popular open-source LLMs using methods such as LoRA or full fine-tuning.
LoRA preserves the base model’s original weights and trains smaller added components instead. This can reduce memory requirements and computational resources compared with full fine-tuning.
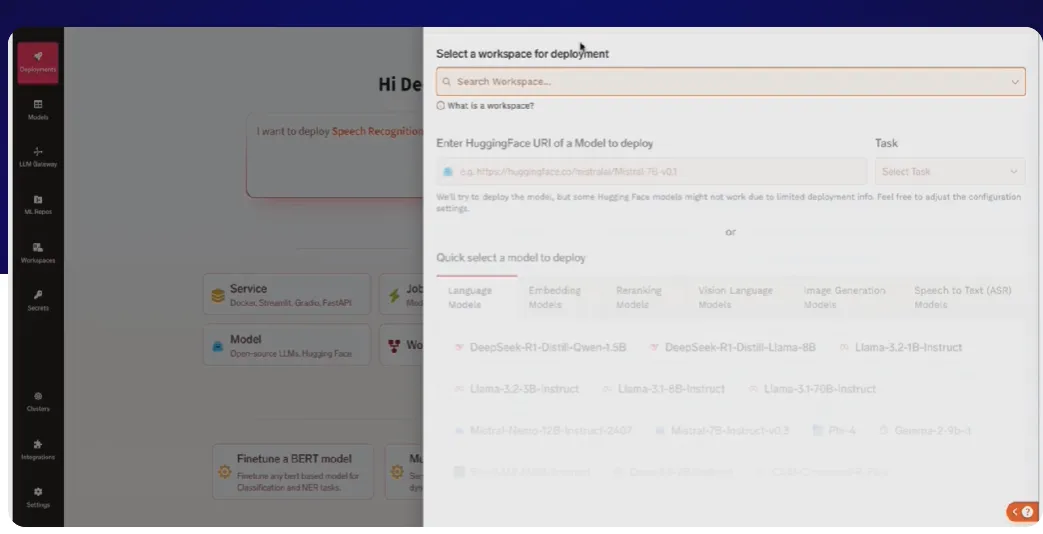
Once a fine-tuned model is ready for application use, TrueFoundry’s AI Gateway can provide a unified layer for accessing self-hosted and third-party models, with routing, access control, usage monitoring, and observability built in.
This workflow supports the broader LLM development cycle, from additional training through deployment and monitoring.
Move Fine-Tuned Models to Production
Fine-tuning adapts an existing model to a specific task or domain without training it again from scratch. The results depend on the training data, the fine-tuning method, and how well the model is tested.
Once the model is ready, TrueFoundry can help manage the move to production, including deployment, monitoring, access control, and model management. Book a demo.
Gouvernez, déployez et suivez l'IA dans votre propre infrastructure

GenAI infra- simple, plus rapide et moins cher
Les meilleures équipes lui font confiance pour faire évoluer GenAI

- © 2022 ENSEMBLE Technologies



Abonnez-vous à notre newsletter
Les dernières nouvelles, articles et ressources envoyés dans votre boîte de réception


