


Obtenga acceso instantáneo a un entorno TrueFoundry en vivo. Implemente modelos, dirija el tráfico de LLM y explore la plataforma completa: su sandbox estará listo en segundos, sin necesidad de tarjeta de crédito.


What is Retrieval-Augmented Generation (RAG) and how does it work?

Imagine asking an AI assistant about your company's latest policy or a product update released yesterday. A standard large language model (LLM) may struggle because it relies primarily on the knowledge it gained during training, which can quickly become outdated. In some cases, it may even produce responses that sound plausible but aren't accurate.
That's why many organizations are turning to Retrieval-Augmented Generation (RAG). By combining the reasoning capabilities of LLMs with access to trusted external knowledge, RAG helps AI applications deliver more reliable and context-aware responses.
In this article, you'll learn what Retrieval-Augmented Generation meaning, how it works, its benefits, common use cases, and how it compares with semantic search and fine-tuning.
What is Retrieval-Augmented Generation (RAG)?
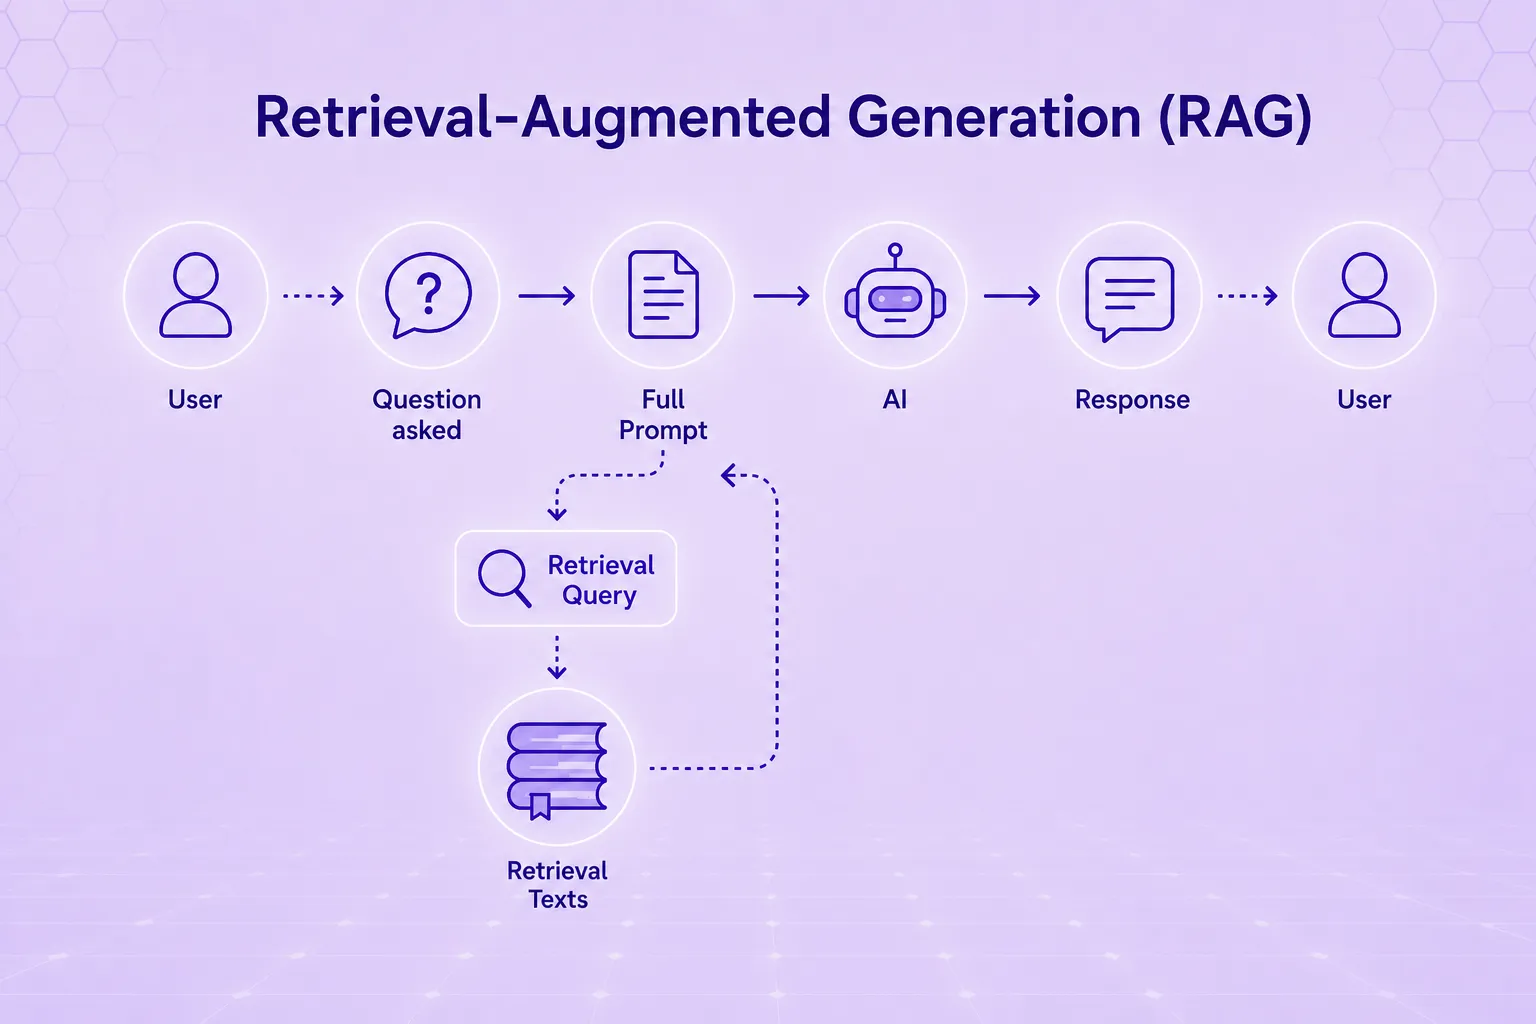
Retrieval-Augmented Generation (RAG) is an AI technique that improves the performance of large language models (LLMs) by enabling them to retrieve relevant information from external knowledge sources before generating a response.
Rather than answering solely from the data it was trained on, a RAG system first searches trusted sources, such as documents, databases, APIs, or knowledge bases, for information related to user’s query. It then uses that retrieved context to generate a more accurate, relevant, and well-informed answer.
In simple terms, Retrieval-Augmented Generation combines the strengths of information retrieval and generative AI.
This approach helps AI applications deliver responses that are grounded in reliable data, stay up to date with changing information, and reduce the risk of hallucinations, making it especially valuable for enterprise AI, customer support, research, and knowledge management.
How does Retrieval-Augmented Generation (RAG) work?
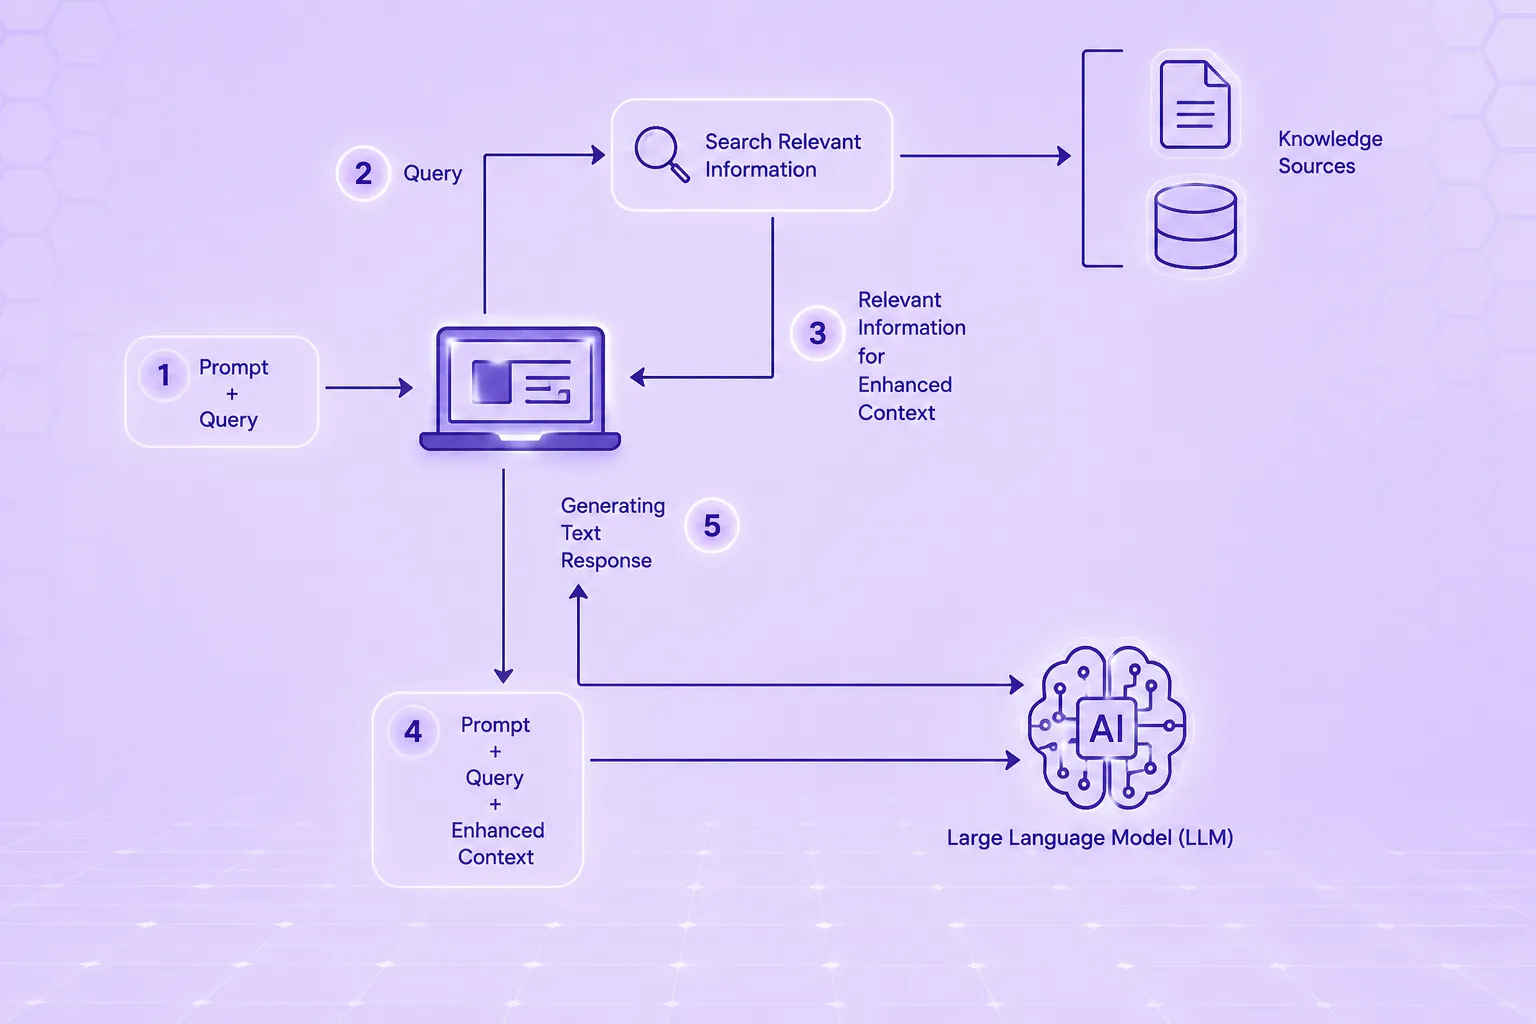
The RAG workflow is built around four key stages that work together to help an AI system retrieve relevant information and generate context-aware responses.
Create external data
The process begins by preparing the information that the AI will use during retrieval. This information can come from many places, including business documents, customer support articles, databases, APIs, or research publications. Along with storing this content, the system also transforms it into machine-readable representations called embeddings.
These embeddings capture the meaning of the content and are stored in a vector database, making it easier for the system to find related information later.
Retrieve relevant information
When a user submits a question, the system first interprets the meaning behind the query instead of looking for exact keyword matches. It searches the vector database to identify the pieces of content that are most relevant to the user's intent.
For instance, if someone asks an HR assistant about their remaining leave balance, the system may retrieve both the company's leave policy and the employee's leave history. By narrowing the search to the most useful information, the model receives the context it needs to answer accurately.
Augment the LLM prompt
The retrieved information is then combined with the original question before it is sent to the language model. Instead of working from memory alone, the LLM now has supporting context that helps it understand the request more clearly.
This allows it to generate responses that are grounded in reliable information, making them more accurate and reducing the chances of fabricated or misleading answers.
Update external data
Unlike retraining an LLM, updating a RAG system is relatively straightforward. As new documents become available or existing information changes, the knowledge base can be refreshed by adding the latest content and generating new embeddings.
This ensures the system continues to retrieve current information without modifying the underlying language model.
What are the benefits of Retrieval-Augmented Generation (RAG)?
RAG offers several benefits that make AI applications more accurate, practical, and easier to maintain. Here are some of the biggest advantages:
Cost-effective implementation
Instead of retraining a language model every time the underlying data changes, organizations only need to update the knowledge base. This saves time, reduces costs, and makes it easier to keep AI applications running.
Current information
RAG can retrieve the latest information from documents, databases, or other trusted sources. This allows the AI to answer questions using up-to-date content instead of relying only on older training data.
Enhanced user trust
Because responses are based on relevant information from trusted sources, users are more likely to trust the answers. Some RAG systems can even show the source of the information, making it easier to verify.
More developer control
Developers can choose exactly which documents or data sources the AI can access. This helps improve the quality of responses and ensures the model uses only relevant information.
Greater data security
RAG keeps sensitive business data in external knowledge sources instead of embedding it into the model’s parameters. This gives organizations more control over how their data is accessed while supporting privacy and compliance requirements.
What are the components of a Retrieval-Augmented Generation (RAG) system?
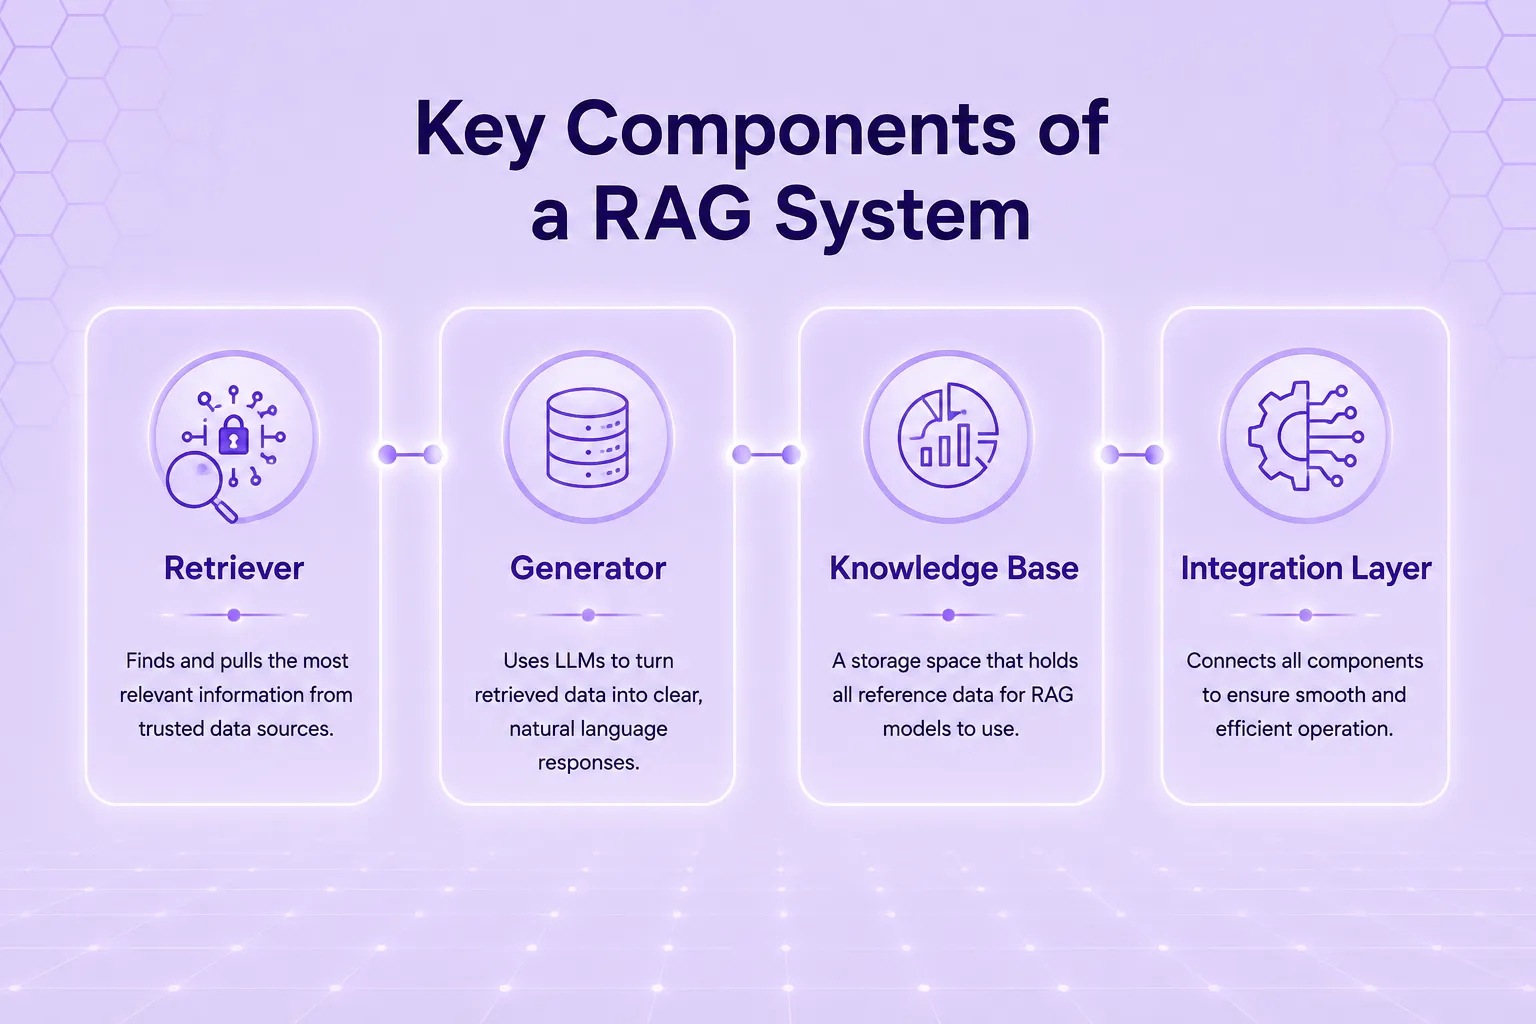
A RAG system relies on four key components that work together to retrieve relevant information and generate accurate responses. Each component plays a specific role in the overall workflow.
The knowledge base
The knowledge base is where all the information the AI can access is stored. It may include company documents, product manuals, FAQs, research papers, databases, or internal wikis. Before this information is used, it is processed and organized so it can be searched quickly and efficiently.
The retriever
The retriever is responsible for finding the most relevant information based on a user's query. Instead of looking for exact keyword matches, it searches for content with similar meaning, helping the system identify the best information even when the wording is different.
The integration layer
The integration layer connects the retriever with the language model. It takes the information returned by the retriever, combines it with the user's question, and prepares it in a format the LLM can understand. This ensures the model receives the right context before generating a response.
The generator
The generator is the large language model that creates the final response. Using both the user's query and the retrieved information, it generates a natural, context-aware answer that is more accurate and reliable than one based only on its pre-trained knowledge.
What are the use cases for Retrieval-Augmented Generation (RAG)?
RAG can be used across a wide range of industries and business functions. Any application that needs accurate, up-to-date, or domain-specific information can benefit from combining information retrieval with a large language model.
Here are some of the most common use cases:
1. Specialized chatbots and virtual assistants: RAG powers AI assistants that can answer questions using company-specific information instead of relying only on general knowledge. For example, customer support bots can retrieve product documentation, while internal HR assistants can answer questions about company policies, employee benefits, or leave balances.
2. Research: Researchers often need to review large volumes of information from journals, reports, or technical documents. A RAG system can quickly retrieve the most relevant sources and help summarize key findings, making the research process faster and more efficient.
3. Content generation: Marketing teams, technical writers, and content creators can use RAG to generate articles, FAQs, product descriptions, or documentation based on approved business content. This helps maintain accuracy and consistency while reducing manual effort.
4. Market analysis and product development: Businesses can use RAG to analyze customer feedback, competitor information, market reports, and industry trends. By retrieving relevant insights from multiple sources, teams can make better-informed decisions when developing new products or refining existing ones.
5. Knowledge engines: Many organizations use RAG to build intelligent knowledge engines that allow employees to search internal documents using natural language. Instead of manually browsing multiple files, users can ask questions and receive direct, context-rich answers from the organization's knowledge base.
6. Recommendation services: RAG can improve recommendation systems by combining customer preferences with information from product catalogs, user guides, or knowledge bases. This enables businesses to deliver more personalized recommendations, whether they're suggesting products, learning resources, or support articles.
What problem does RAG solve for large language models?
Large language models (LLMs) are great at understanding and generating text, but they also have limitations. They can make up facts, miss recent information, or struggle with large collections of business documents.
Retrieval-Augmented Generation (RAG) helps overcome these challenges by giving the model access to relevant information before it generates a response.
Hallucinations and ungrounded responses
LLMs can sometimes produce answers that sound confident but are incorrect. This is known as a hallucination. Since RAG retrieves information from trusted sources before generating a response, it helps the model stay grounded in facts and reduces the chances of inaccurate answers.
Knowledge cutoffs and fast-changing information
A language model only knows what it learned during training. It doesn't automatically know about new product launches, updated company policies, or recent industry developments. RAG solves this by retrieving the latest information from connected knowledge sources, allowing the AI to provide more current and relevant responses.
Limited context windows and long-document understanding
Organizations often have thousands of pages of documentation, and feeding all of it into an LLM on every request is costly, slow, and can degrade answer quality. Instead of sending entire documents to the model, RAG finds only the sections that are most relevant to the user's question. This helps the model understand the context better and generate more focused answers.
Enterprise needs
Businesses need AI systems that can work with sensitive information without compromising security. RAG allows organizations to keep their data in approved internal systems while controlling what the AI can access. It also makes it easier to trace responses back to the original documents, improving transparency and helping meet compliance requirements.
What is the difference between Retrieval-Augmented Generation and semantic search?
Semantic search is designed to retrieve information based on the meaning of a query rather than exact keywords. Instead of returning results that contain the same words, it identifies documents or passages that are closely related to what the user is trying to find. The user still needs to read through those results to get the answer.
Retrieval-Augmented Generation (RAG) combines a retrieval step, often semantic search, with a large language model. After retrieving the most relevant information, it uses that content to generate a clear, natural-language response. Rather than simply showing a list of matching documents, RAG summarizes the retrieved information into a direct answer while keeping it grounded in trusted sources.
Semantic search helps you find information, while RAG helps you understand it. Semantic search points you to the right content, whereas RAG retrieves that content and uses it to answer your question in a conversational way.
This is why RAG is commonly used for AI chatbots, knowledge assistants, and customer support applications where users expect answers rather than search results.
What is the difference between RAG and fine-tuning?
Fine-tuning changes the model itself by training it on additional data. This helps the model learn a specific writing style, understand industry-specific terminology, or perform specialized tasks more effectively. However, whenever the underlying information changes, the model may need to be fine-tuned again, which can be time-consuming and expensive.
RAG, on the other hand, doesn't modify the language model. Instead, it connects the model to an external knowledge base and retrieves relevant information whenever a user asks a question. This means you can keep the AI up to date simply by updating the knowledge base, without retraining the model.
In many real-world applications, RAG is the better choice when information changes frequently, such as product documentation, company policies, or research data. Fine-tuning is more suitable when you want the model to consistently adopt a particular tone, follow specific instructions, or perform a specialized task.
Many organizations even use both together, fine-tuning to improve the model's behavior and RAG to ensure its responses are based on the latest, most accurate information.
How TrueFoundry helps you build RAG applications
Building a Retrieval-Augmented Generation (RAG) application involves more than connecting a language model to a knowledge base. You also need to manage document ingestion, retrieval pipelines, model deployment, security, and monitoring. As your application scales, keeping all these components working together can become challenging.
TrueFoundry simplifies this process by providing the infrastructure needed to build, deploy, and manage production-ready RAG applications. With its open-source framework, Cognita, you can connect your preferred document parsers, embedding models, and vector databases while keeping your AI stack flexible and customizable.
For enterprise deployments, TrueFoundry AI Gateway adds an extra layer of control by helping teams securely manage access to AI models, enforce guardrails, protect sensitive information, and monitor how applications use LLMs. This makes it easier to build RAG applications that meet enterprise security and governance requirements.
Conclusion
As AI applications become more integral to business operations, delivering reliable, context-aware responses is no longer optional. Retrieval-Augmented Generation (RAG) provides a practical way to combine the strengths of large language models with trusted, up-to-date knowledge, making enterprise AI more accurate, scalable, and useful.
If you're looking to build production-ready RAG applications, TrueFoundry can help you simplify deployment, governance, and model management while keeping your AI stack flexible. Sign up today.
Controle, implemente y rastree la IA en su propia infraestructura

GenAI infra: simple, más rápido y más barato
Los mejores equipos confían en nosotros para escalar GenAI

- © 2022 ENSEMBLE Technologies



Suscríbase a nuestro boletín
Las últimas noticias, artículos y recursos enviados a tu bandeja de entrada


