


Erhalten Sie sofortigen Zugriff auf eine TrueFoundry-Live-Umgebung. Stellen Sie Modelle bereit, leiten Sie den LLM-Verkehr weiter und erkunden Sie die gesamte Plattform — Ihre Sandbox ist in Sekundenschnelle einsatzbereit, ohne dass eine Kreditkarte erforderlich ist.


What Are LLM Evals and How Do They Work?

Steuern, implementieren und verfolgen Sie KI in Ihrer eigenen Infrastruktur
Frequently Asked Questions
What are LLM evals in simple terms?
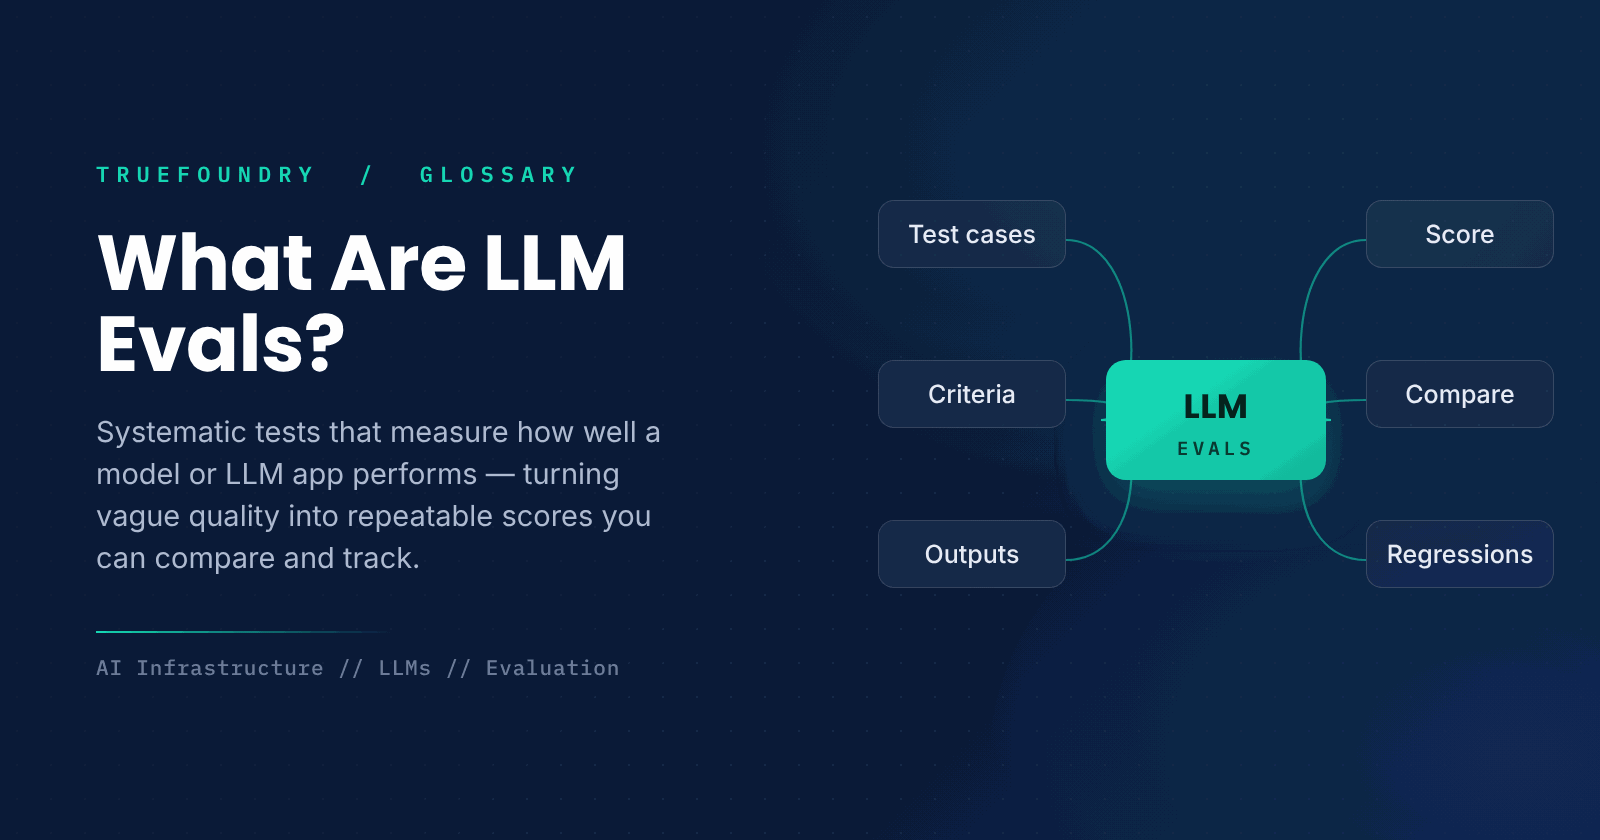
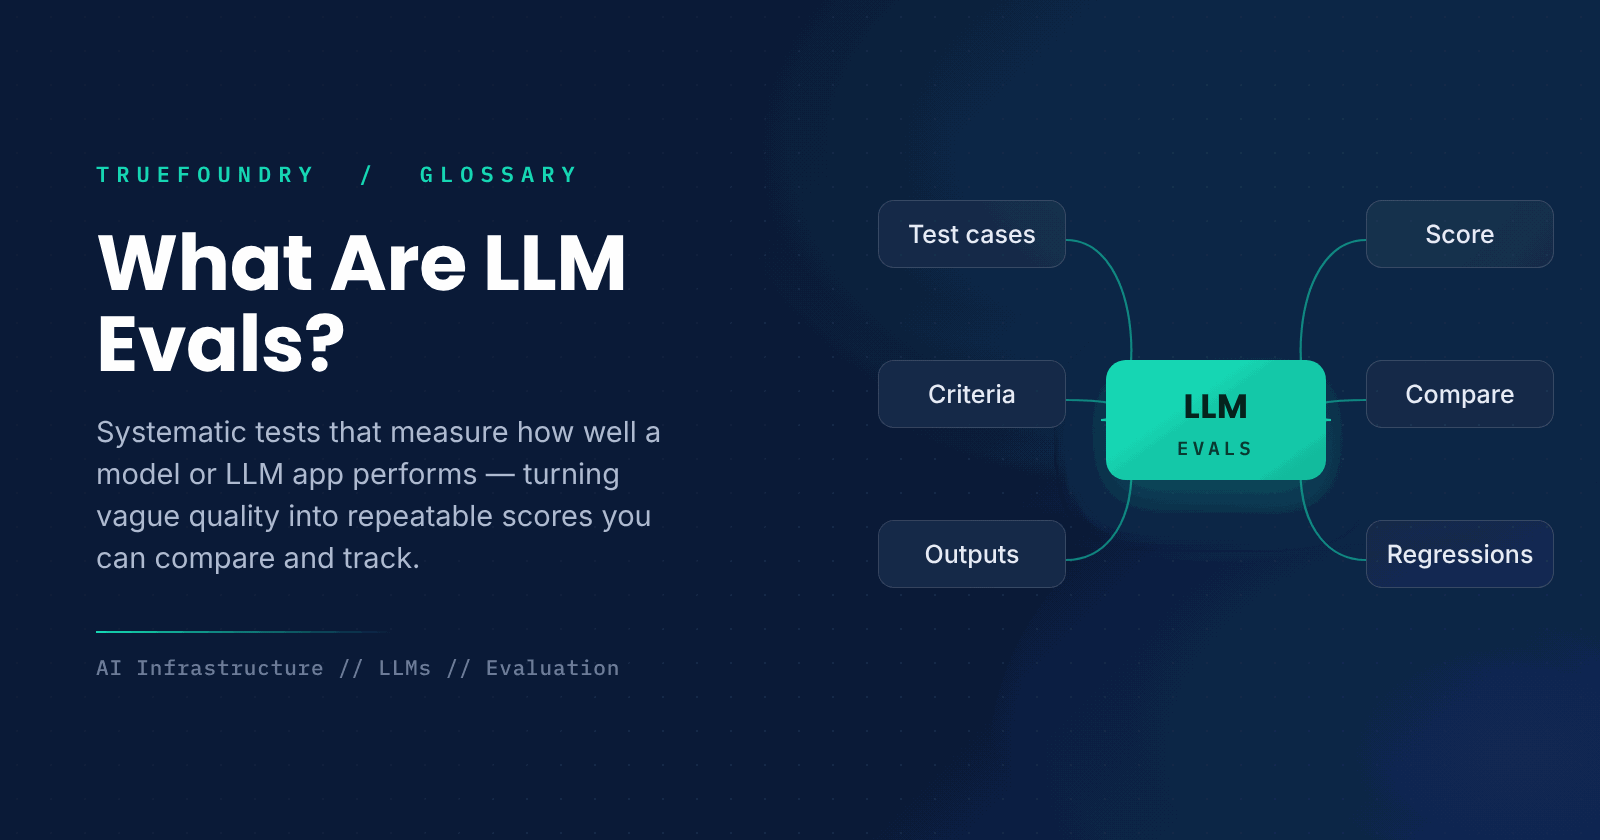
These are formalized tests that evaluate how well a model or LLM application does its job. You define test cases and criteria, run the model, and grade the results, translating quality into metrics you can compare and track.
Why are LLM evals important?
Because you will not know whether a change has been positive or negative without them. Evaluations help detect regressions before users see them, allow comparisons between models on evidence, and help track whether the system is improving.
How do you score open-ended outputs?
Frequently with model-based scoring, where an additional model evaluates the output against certain criteria, or with human assessment for the most critical cases. Exact-match scoring applies only when there is one right answer.
What is the difference between evals and monitoring?
Evals test quality by comparing against known cases, normally prior to release or whenever there is an update. Monitoring and observability watch the actions the system performs in production. Together they cover both pre-release testing and live behavior.
How big should an eval set be?
Large enough to represent real usage, including the significant cases and corner cases, not only the easy ones. A few carefully selected cases are more helpful than a large number that do not represent actual system usage.

GenAI infra- einfach, schneller, günstiger
Top-Teams vertrauen uns bei der Skalierung von GenAI

- © 2022 ENSEMBLE Technologies



Abonnieren Sie unseren Newsletter
Die neuesten Nachrichten, Artikel und Ressourcen werden in Ihren Posteingang gesendet


