


Erhalten Sie sofortigen Zugriff auf eine TrueFoundry-Live-Umgebung. Stellen Sie Modelle bereit, leiten Sie den LLM-Verkehr weiter und erkunden Sie die gesamte Plattform — Ihre Sandbox ist in Sekundenschnelle einsatzbereit, ohne dass eine Kreditkarte erforderlich ist.


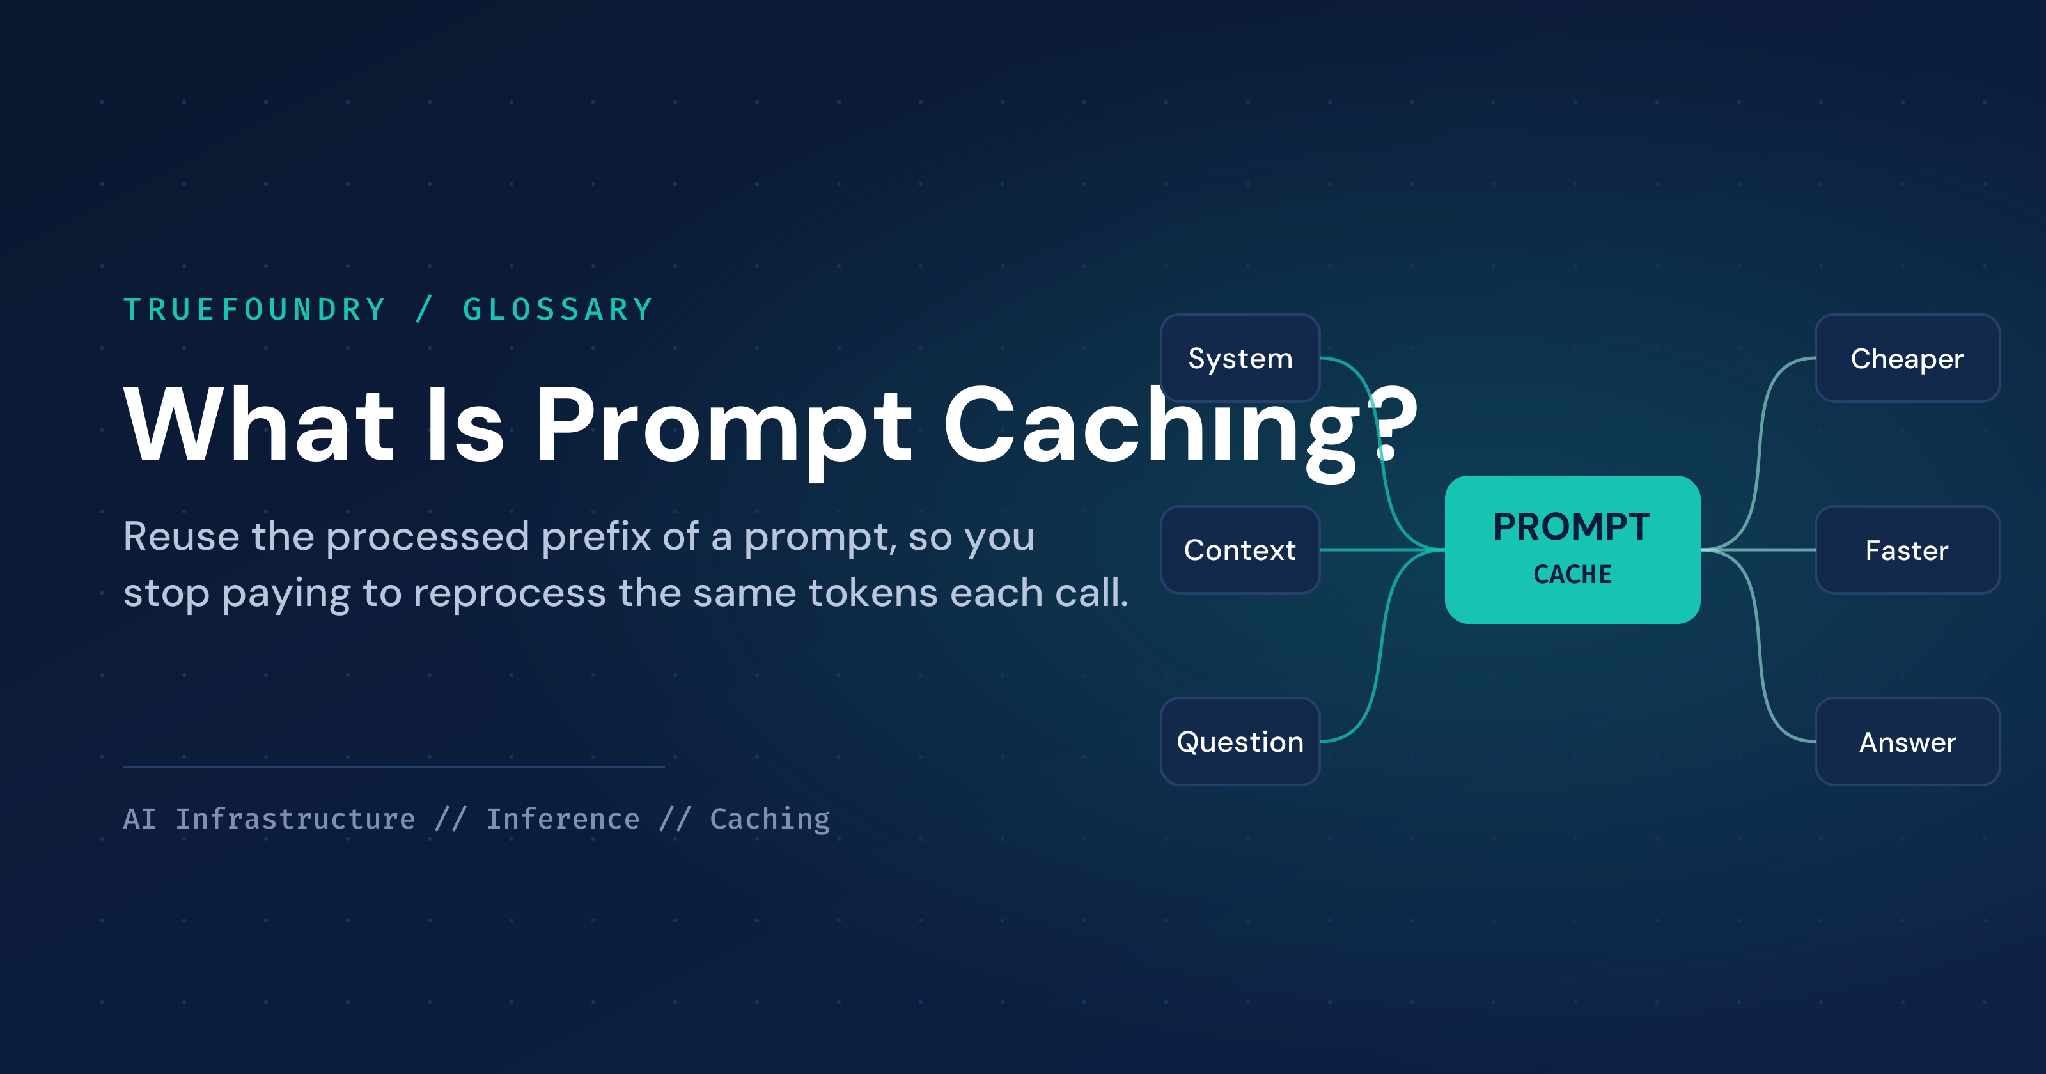
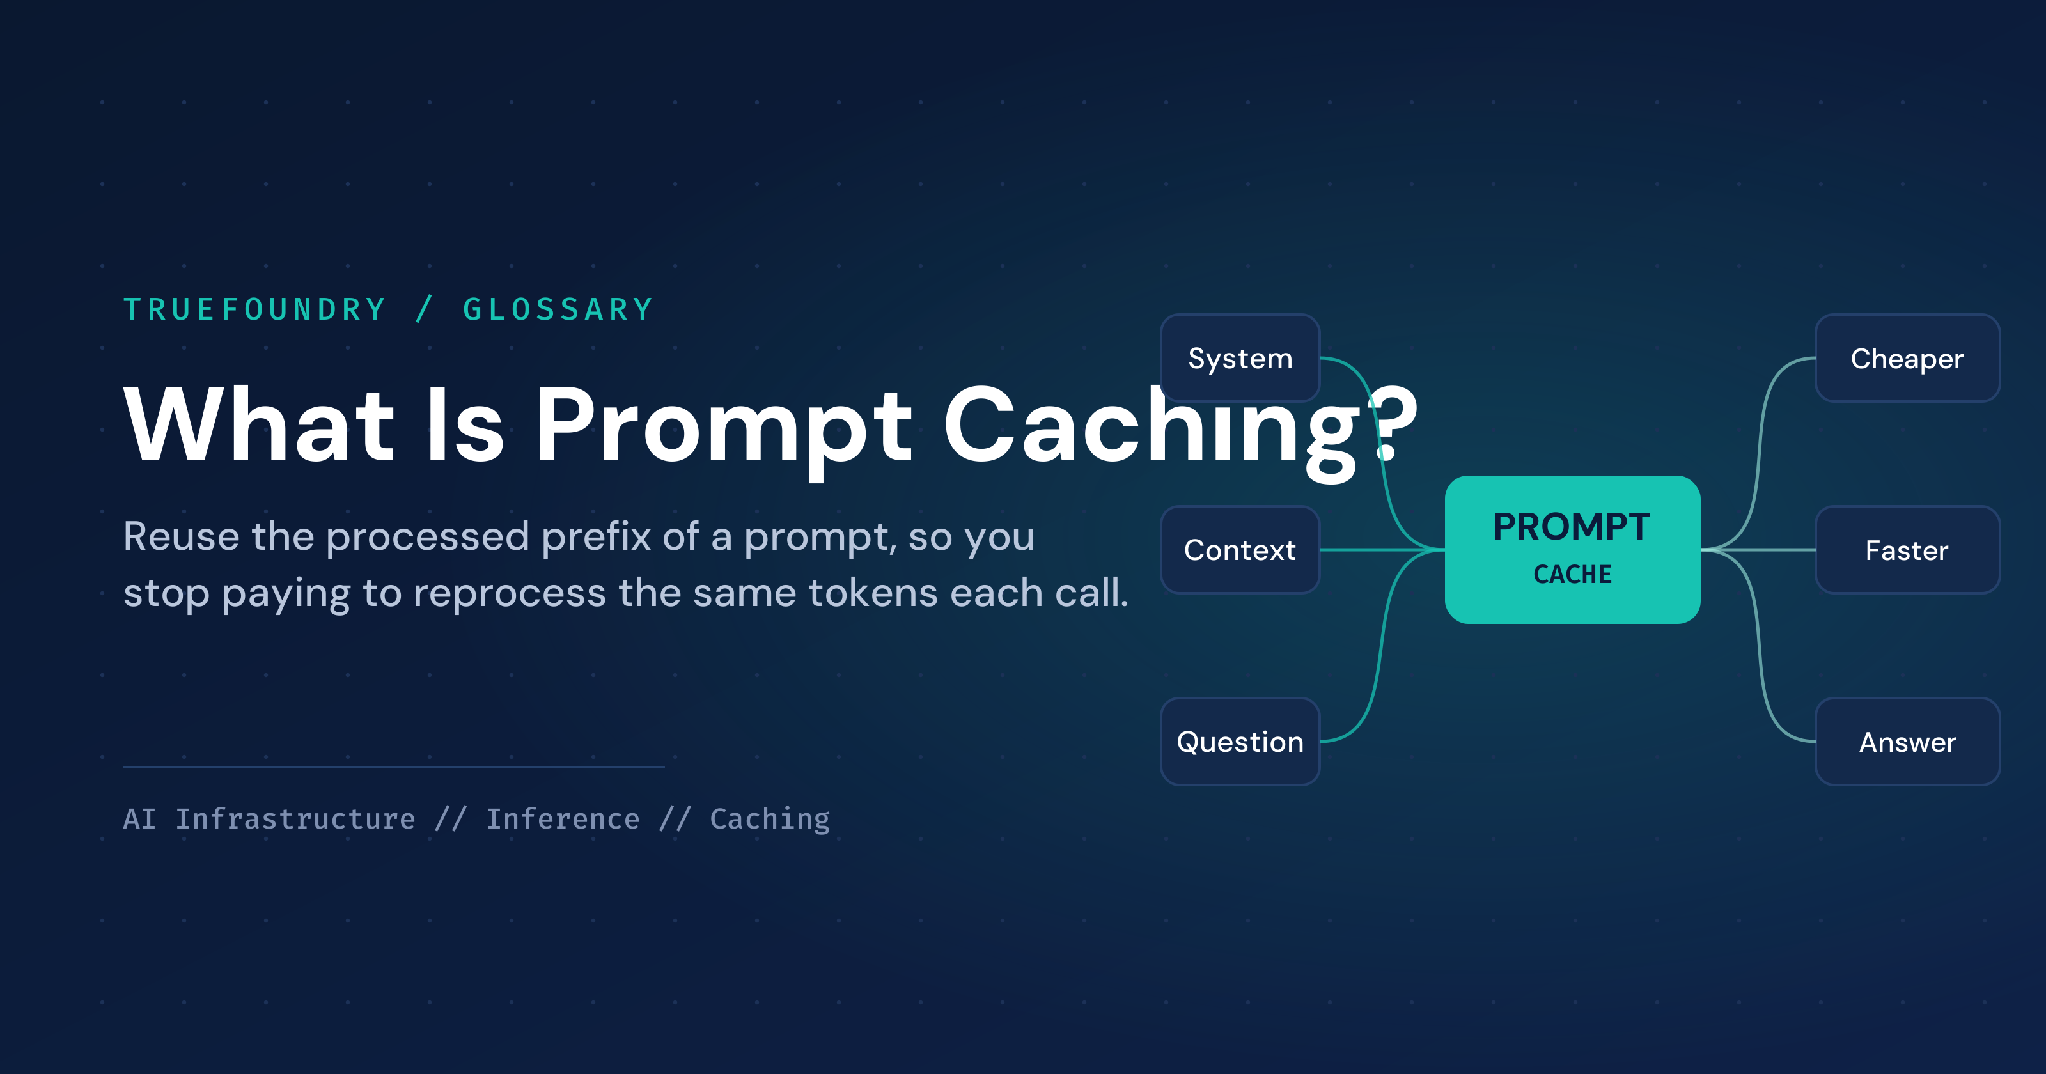
What Is Prompt Caching and How Does It Work?

Steuern, implementieren und verfolgen Sie KI in Ihrer eigenen Infrastruktur
Frequently Asked Questions
What is prompt caching in simple terms?
It lets a model recycle what it has already done when part of the prompt repeats. Those tokens cost you less and you get an earlier answer.
What is the difference between prompt caching and semantic caching?
Prompt caching recycles the inputted prefix within one inference, thus making the inference less costly but still taking place. Semantic caching uses an already saved answer directly without making the model run whenever the new query is semantically the same.
Does prompt caching change the model's output?
No, because the machine produces an original output. Caching just ensures that the repeated prefix does not get re-evaluated; consequently, the quality remains unchanged, but the time and cost reduce.
Why does the order of my prompt matter?
Prompt caching relies on the prefix, which is the beginning of the prompt. Placing stable data at the beginning and changeable data at the end makes more of the prompt cacheable.
Does prompt caching work across different providers?
No, because the cache lives within a single provider. Different providers have different pricing and time-to-live policies. The caching is not carried forward when models or providers are switched.

GenAI infra- einfach, schneller, günstiger
Top-Teams vertrauen uns bei der Skalierung von GenAI

- © 2022 ENSEMBLE Technologies



Abonnieren Sie unseren Newsletter
Die neuesten Nachrichten, Artikel und Ressourcen werden in Ihren Posteingang gesendet


