


Erhalten Sie sofortigen Zugriff auf eine TrueFoundry-Live-Umgebung. Stellen Sie Modelle bereit, leiten Sie den LLM-Verkehr weiter und erkunden Sie die gesamte Plattform — Ihre Sandbox ist in Sekundenschnelle einsatzbereit, ohne dass eine Kreditkarte erforderlich ist.


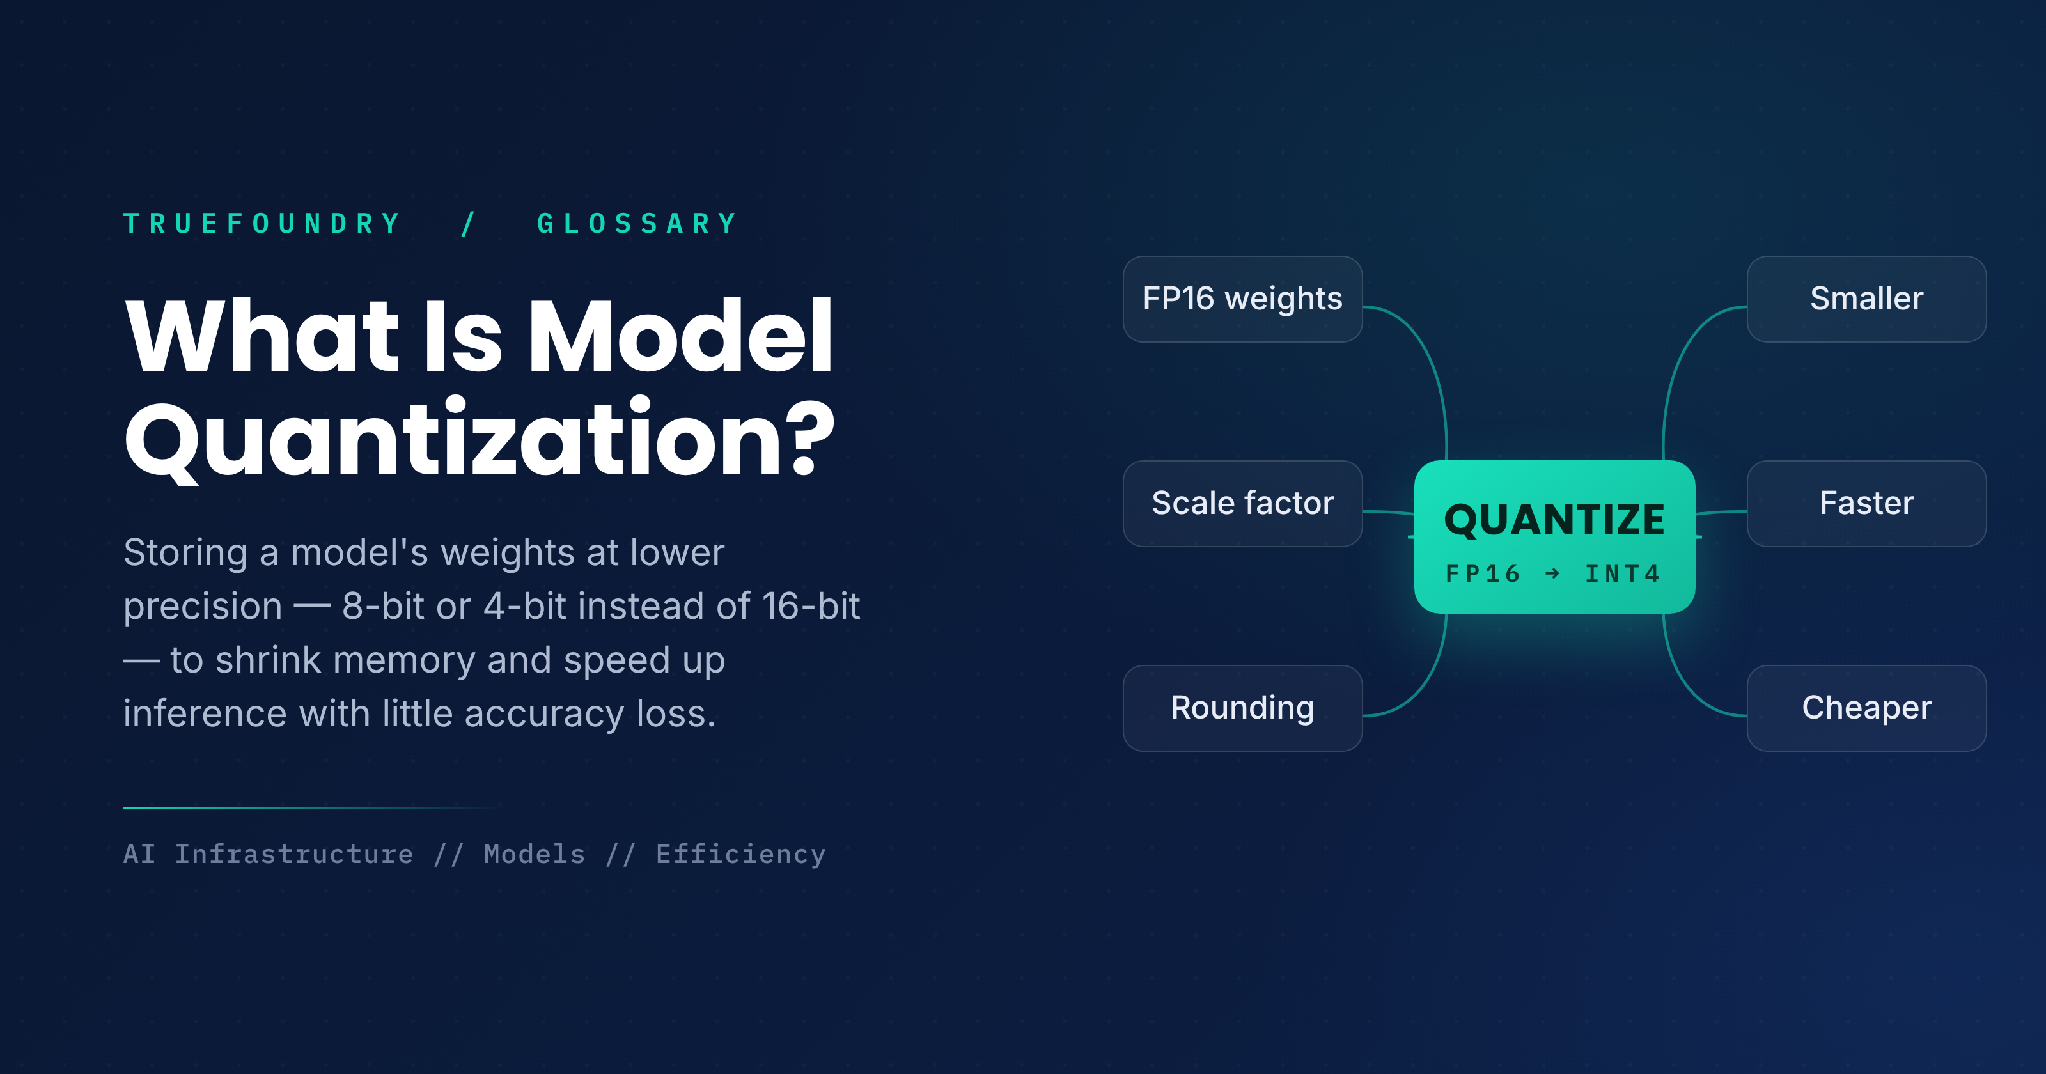
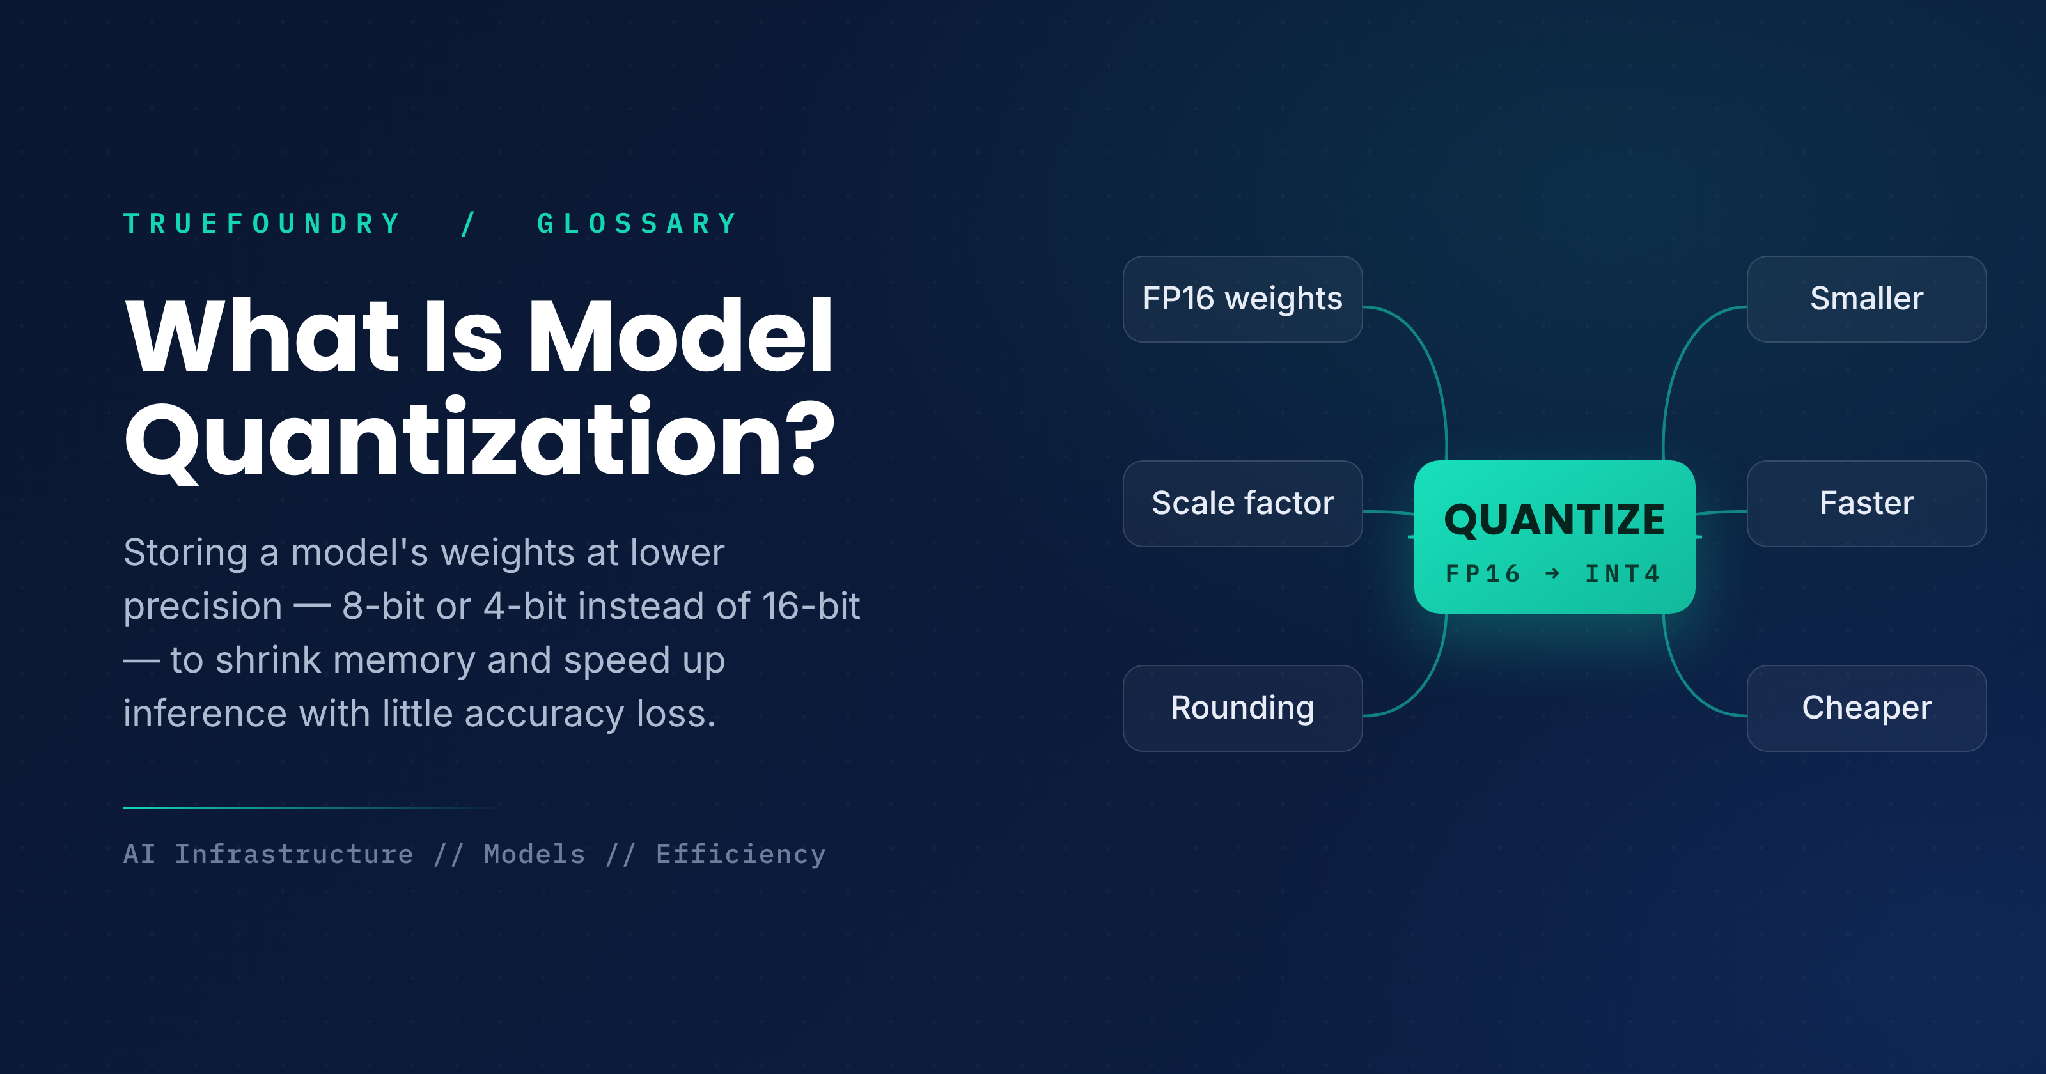
What Is Model Quantization and How Does It Work?

Steuern, implementieren und verfolgen Sie KI in Ihrer eigenen Infrastruktur
Frequently Asked Questions
What is model quantization in simple terms?
It refers to storing the model's numerical data at reduced precision, such as 8-bit or 4-bit as opposed to 16-bit. The model becomes smaller and faster but operates almost identically, hence being more cost-effective.
Does quantization make a model worse?
Yes, to a certain degree. There will be a slight decrease in accuracy that increases with lower bit widths, though in most cases the trade-off between memory consumption and efficiency is worth the small cost.
What is the difference between INT8 and INT4 quantization?
INT8 is represented by 8 bits per number while INT4 is represented by 4. While INT4 reduces the size of the model even more and improves its loading speed, it poses greater risks of losing accuracy.
What is the difference between PTQ and QAT?
Post-training quantization works on an already-trained model and takes very little time. Quantization-aware training simulates low precision while training the model, which recovers more of its accuracy at the cost of a full training run.
Does quantization speed up inference?
Normally, yes. Less precision means moving less data, and it can use fast integer operations, reducing latency and increasing how many requests a GPU can handle in parallel.

GenAI infra- einfach, schneller, günstiger
Top-Teams vertrauen uns bei der Skalierung von GenAI

- © 2022 ENSEMBLE Technologies



Abonnieren Sie unseren Newsletter
Die neuesten Nachrichten, Artikel und Ressourcen werden in Ihren Posteingang gesendet


