


Erhalten Sie sofortigen Zugriff auf eine TrueFoundry-Live-Umgebung. Stellen Sie Modelle bereit, leiten Sie den LLM-Verkehr weiter und erkunden Sie die gesamte Plattform — Ihre Sandbox ist in Sekundenschnelle einsatzbereit, ohne dass eine Kreditkarte erforderlich ist.


What Is LoRA and How Does It Work?

Steuern, implementieren und verfolgen Sie KI in Ihrer eigenen Infrastruktur
Frequently Asked Questions
What is LoRA in simple terms?
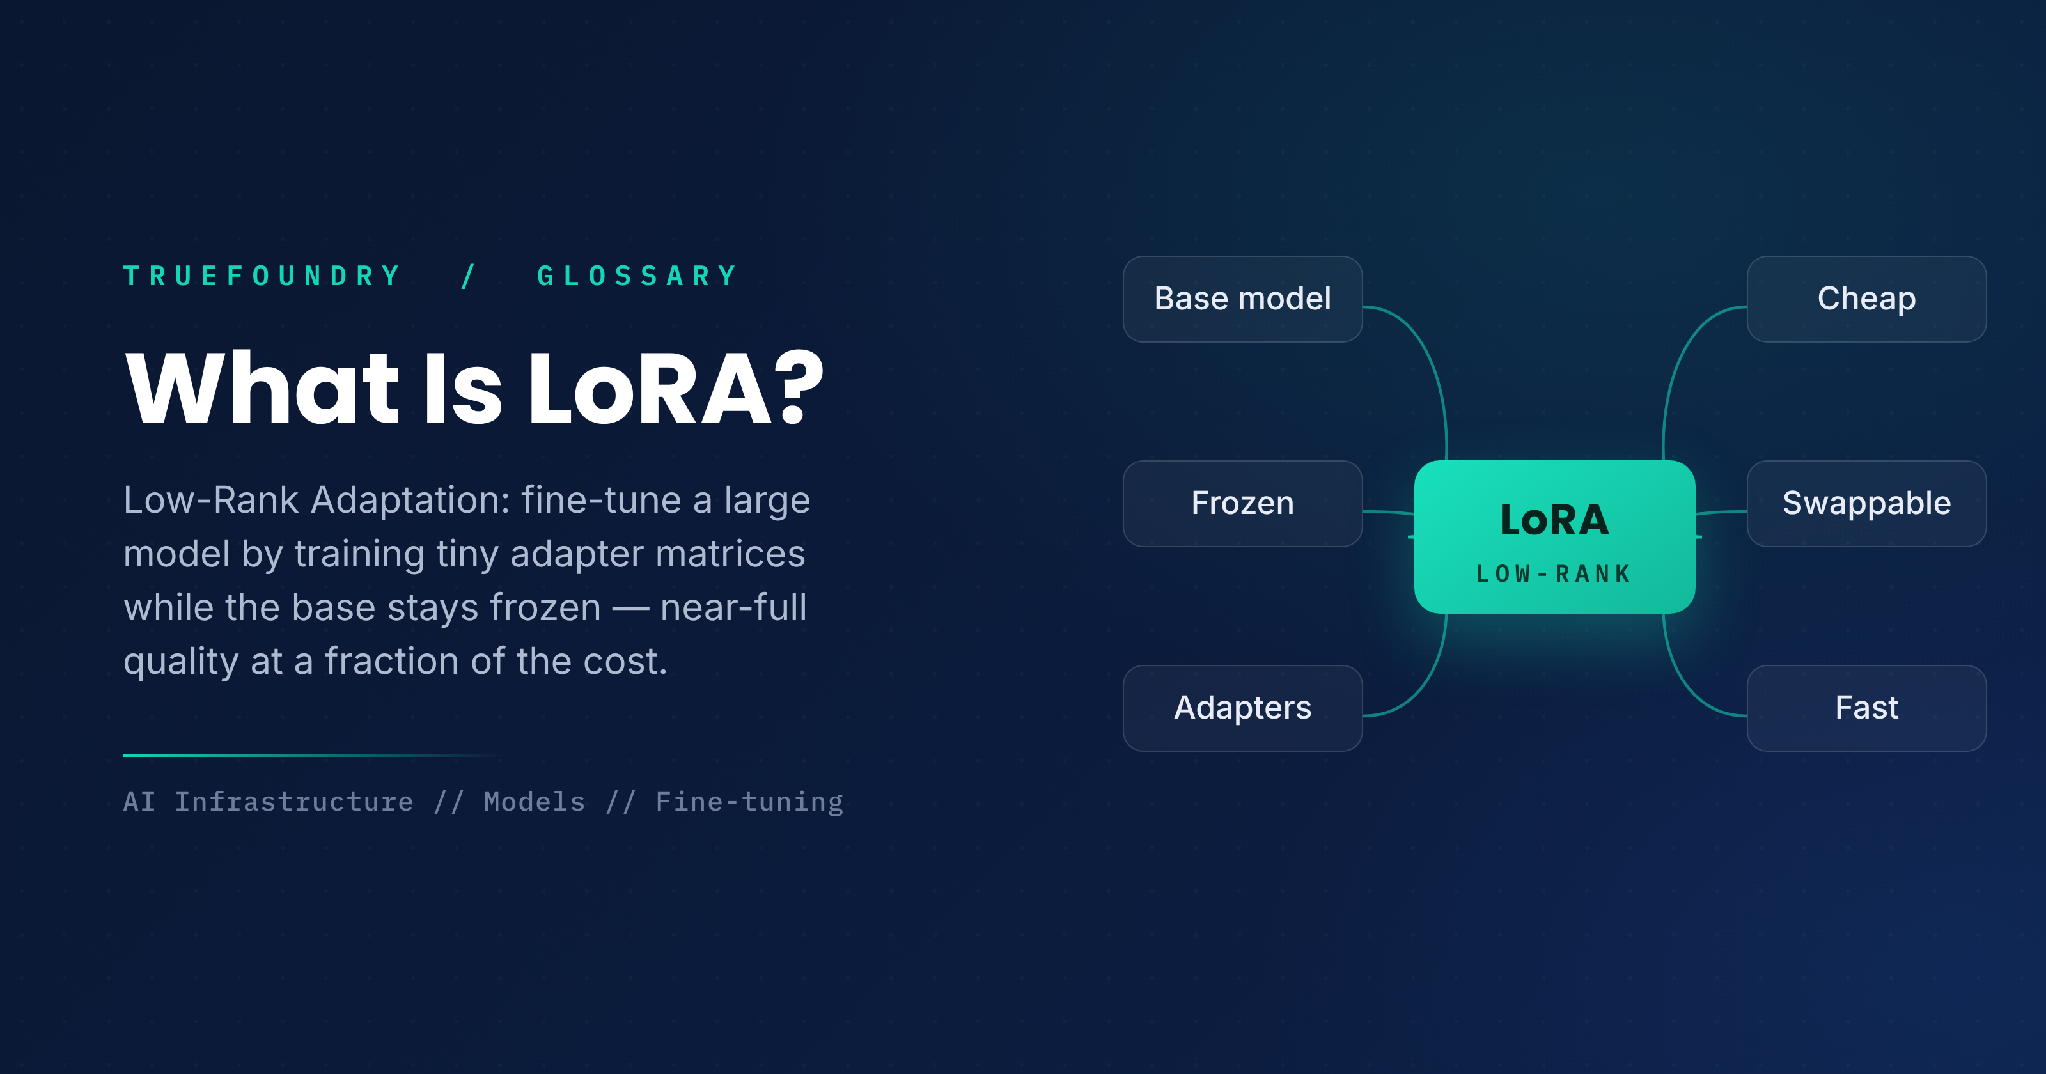
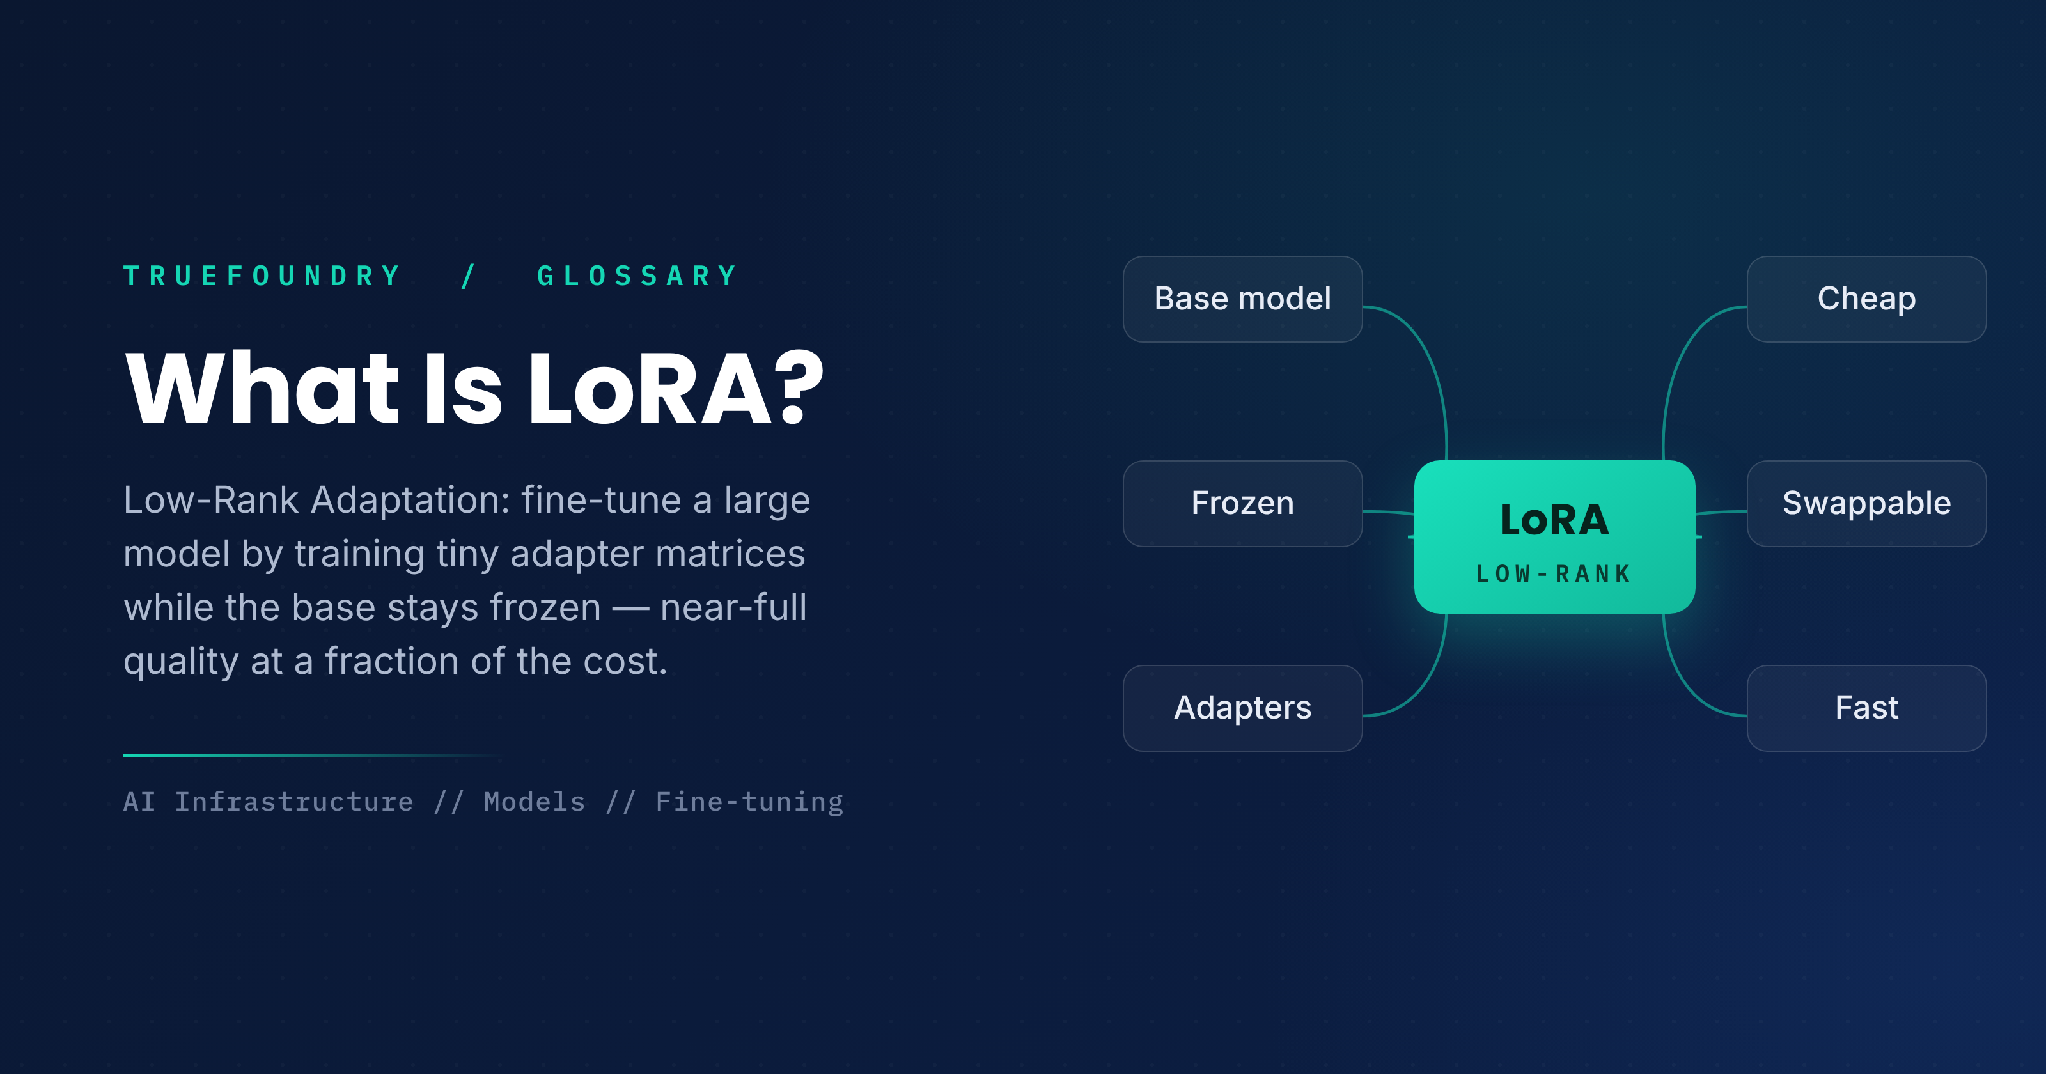
LoRA is an inexpensive method of fine-tuning large models. Rather than modifying the entire set of model weights, it freezes the weights of the large model and trains small additional matrices, so you adapt the model while training only a tiny fraction of it.
How is LoRA different from full fine-tuning?
Full fine-tuning tunes all the weights and requires a complete copy of the model for each new task. LoRA keeps the base model intact and only tunes small adapters, saving enormous amounts of memory and storage while matching full tuning closely on most tasks.
What is a LoRA adapter?
It is the tiny pair of low-rank matrices that LoRA trains and stores, only a couple of megabytes in size. You apply it on top of the frozen base model to obtain the adapted behavior, and you can replace it with another.
Does LoRA reduce model quality?
Almost never. In most cases LoRA does about as well as full fine-tuning. Where large changes are required to the way the model operates, full fine-tuning can still have an advantage.
What is QLoRA?
QLoRA is a combination of LoRA and a quantized base model, so the frozen weights require far less memory. QLoRA lets us fine-tune very large models even on limited hardware, while keeping LoRA's efficiency.

GenAI infra- einfach, schneller, günstiger
Top-Teams vertrauen uns bei der Skalierung von GenAI

- © 2022 ENSEMBLE Technologies



Abonnieren Sie unseren Newsletter
Die neuesten Nachrichten, Artikel und Ressourcen werden in Ihren Posteingang gesendet


