


Accédez instantanément à un environnement TrueFoundry en direct. Déployez des modèles, acheminez le trafic LLM et explorez la plateforme complète : votre sandbox est prête en quelques secondes, aucune carte de crédit n'est requise.


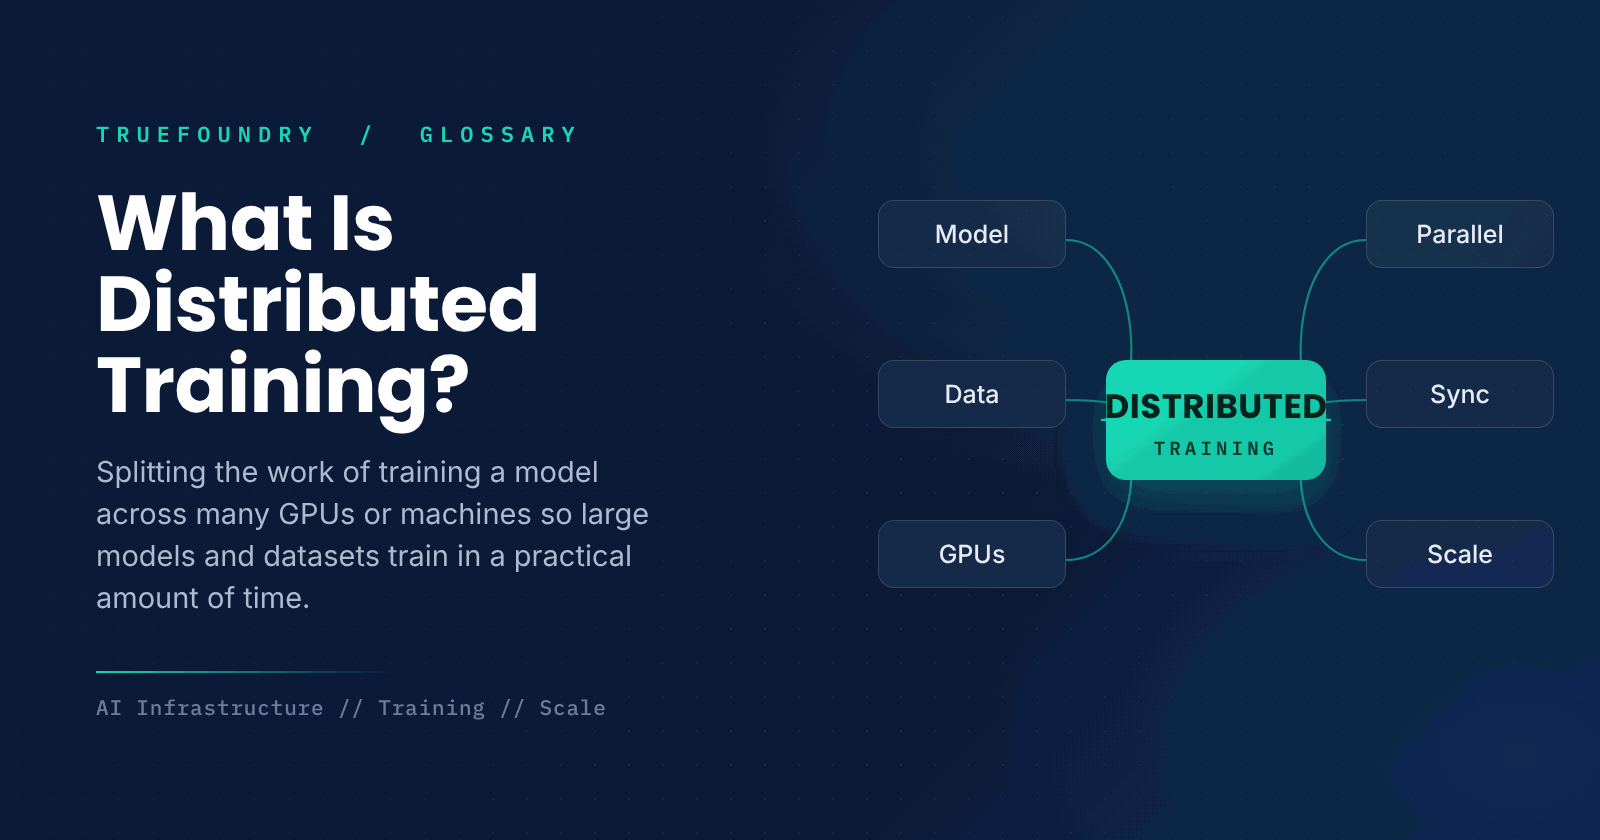
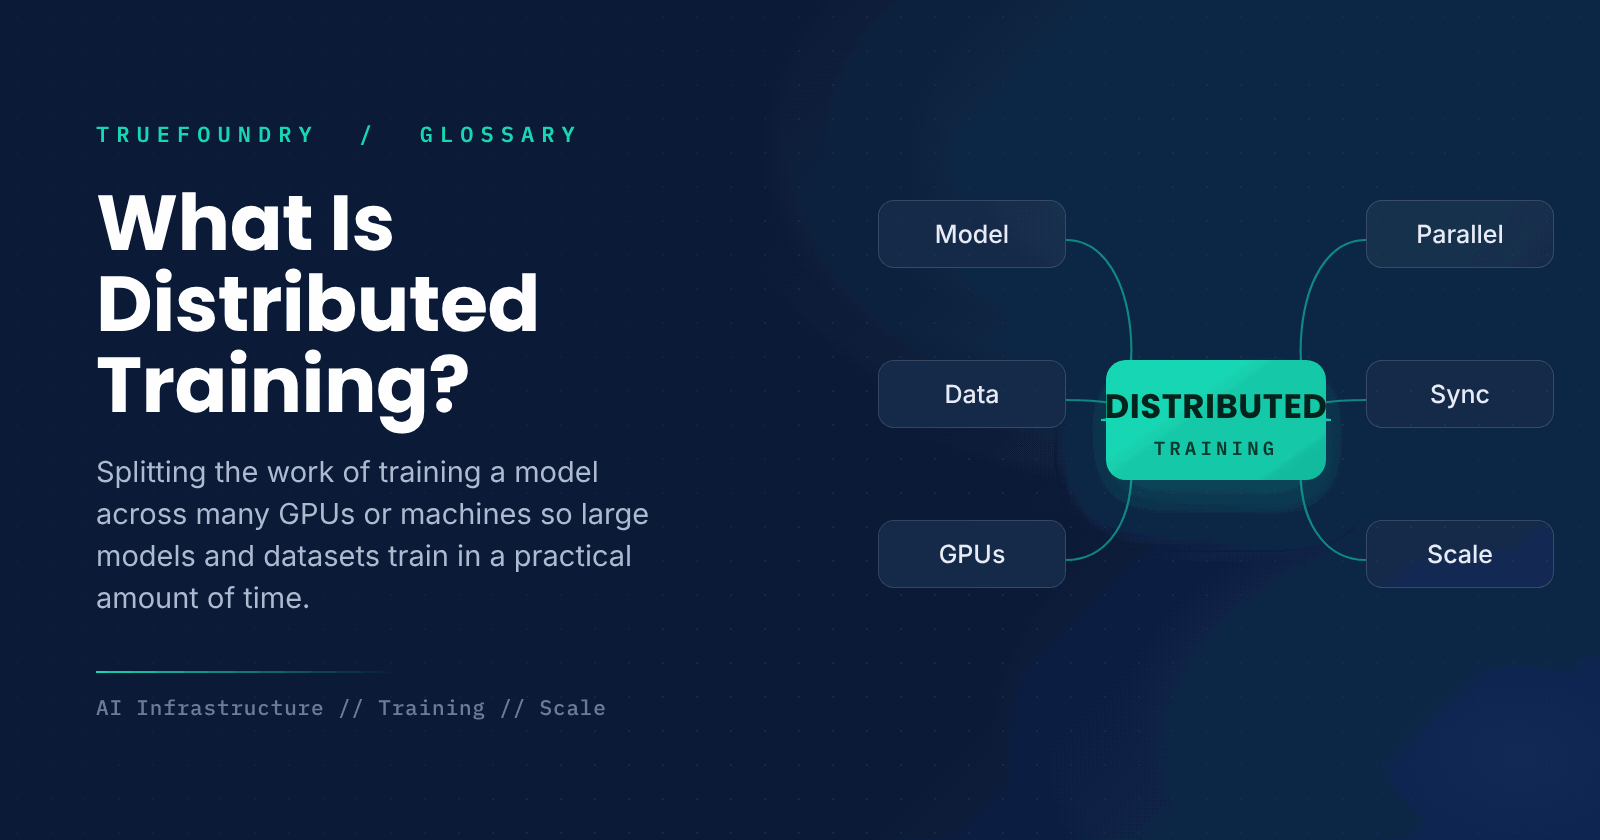
What Is Distributed Training and How Does It Work?

Gouvernez, déployez et suivez l'IA dans votre propre infrastructure
Frequently Asked Questions
What is distributed training in simple terms?
This refers to training a model using several GPUs or computers simultaneously, as opposed to one computer only. The machines divide up the task and work in parallel to produce results equivalent to training on a single large machine, just faster or bigger.
What is data parallelism?
Data parallelism involves copying the entire model to each device and assigning each device a unique portion of the data. Gradients between devices are synchronized at each step to keep them consistent. It scales throughput as long as the model fits on a single device.
What is the difference between data and model parallelism?
Data parallelism replicates the model and splits the data. Model parallelism splits a single model across multiple devices because it is too big to fit on one. Large runs often combine both, plus pipeline parallelism.
Why is synchronization important?
Because every device has to conclude each step with identical weights. Synchronizing gradients among devices lets them work together as one model; however, this introduces communication overhead that can become the bottleneck.
Do I always need distributed training?
No. When the model or dataset fits on one device, using a single GPU is easier and more economical. You need distribution only when the model or dataset exceeds the capacity of one device, or the time needed for training becomes too long.

GenAI infra- simple, plus rapide et moins cher
Les meilleures équipes lui font confiance pour faire évoluer GenAI

- © 2022 ENSEMBLE Technologies



Abonnez-vous à notre newsletter
Les dernières nouvelles, articles et ressources envoyés dans votre boîte de réception


