


احصل على وصول فوري إلى بيئة TrueFoundry مباشرة. انشر النماذج، ووجّه حركة مرور LLM، واستكشف المنصة بالكامل — بيئة الاختبار الخاصة بك جاهزة في ثوانٍ، ولا يلزم وجود بطاقة ائتمان.


What Is LLMOps and How Does It Work?

Govern, Deploy and Trace AI in Your Own Infrastructure
Frequently Asked Questions
What is LLMOps in simple terms?
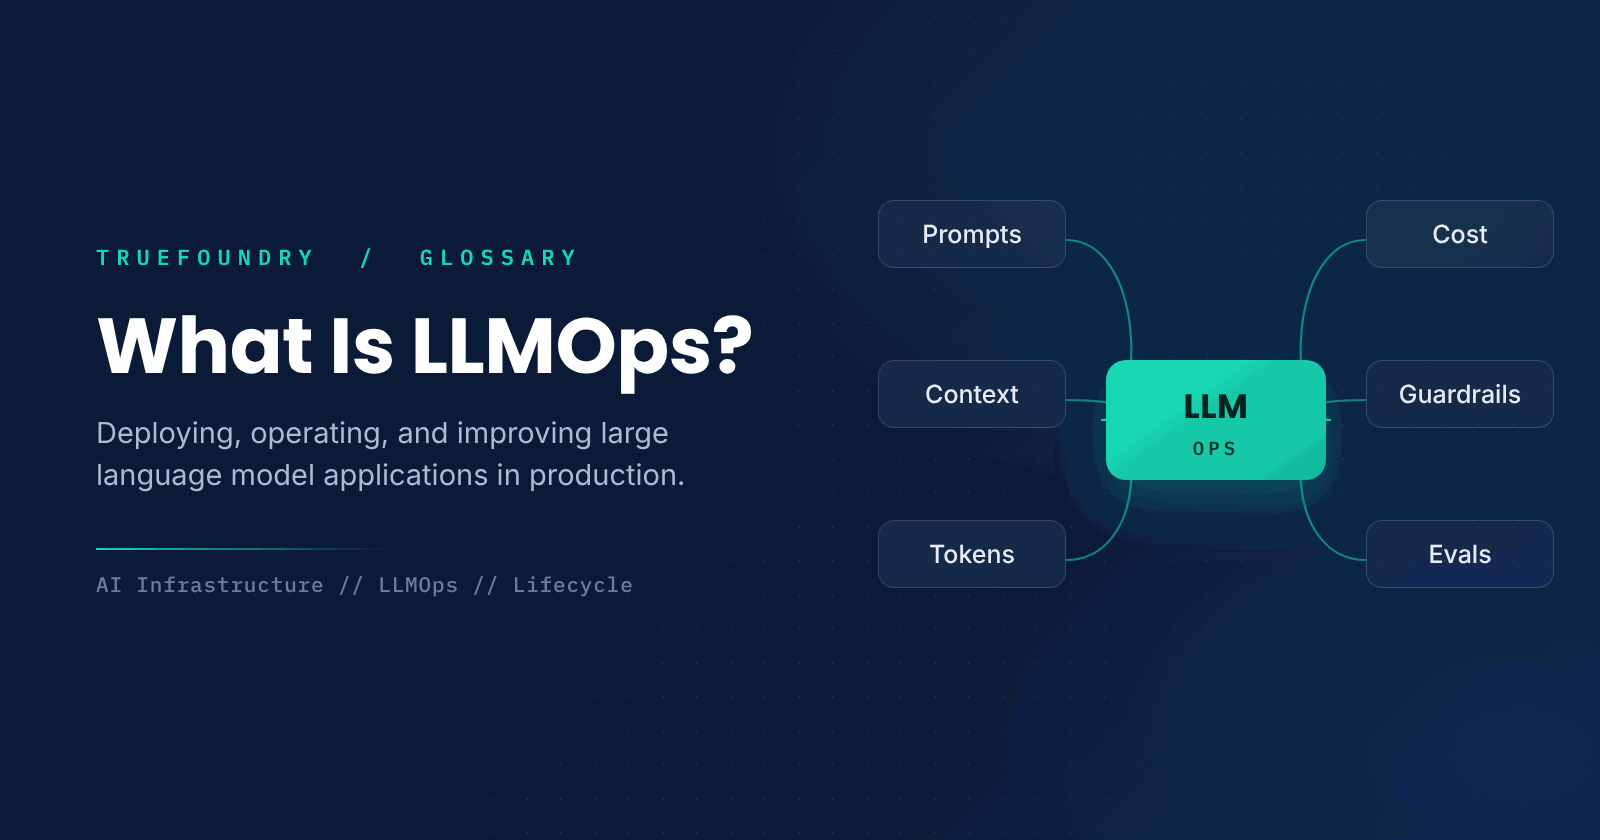
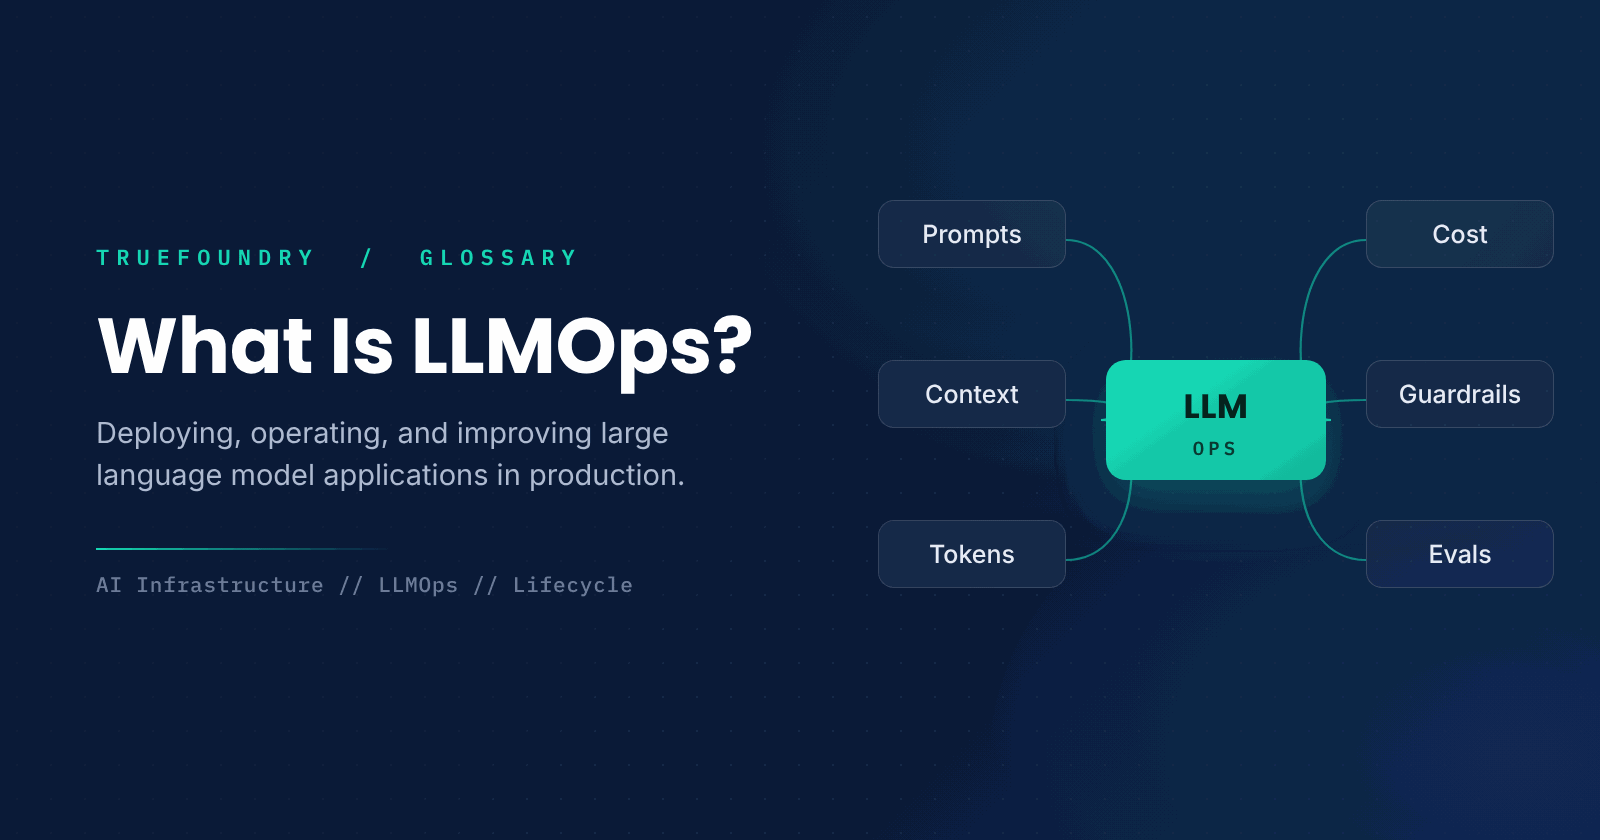
It refers to the practices involved in running large language model applications in production, managing prompts, cost, latency, safety, and quality, so the application stays reliable and affordable rather than just working in a demo.
How is LLMOps different from MLOps?
MLOps involves creating, deploying, and monitoring models you build, tracking accuracy and drift. LLMOps focuses on applications built on pre-trained LLMs, so the work is prompts, context, routing, cost, and output quality rather than training.
Why is managing cost central to LLMOps?
Because LLMs are typically priced per token, so spend scales with usage and prompt size. Without monitoring and limits, cost can climb quickly, which makes tracking and controlling it a core part of operating LLM applications.
How do you improve an LLM app without retraining?
By changing prompts, context, retrieval, routing, and guardrails, then measuring the effect through evaluation. In most cases you do not control the model's weights, so the leverage lies in how you use the model, not in retraining it.
How does a gateway support LLMOps?
A gateway consolidates routing across models, guardrails, and monitoring of cost, latency, and quality. It provides a single place to operate and govern LLM traffic rather than handling each model and application separately.


- © 2022 ENSEMBLE Technologies



اشترك في نشرتنا الإخبارية
أحدث الأخبار والمقالات والموارد تصلك مباشرة إلى بريدك الوارد


